$TTD is up about 40% from its October low after a Q3 beat, but stalled near $16. If dips hold around $13.50, this can be the first leg of a new uptrend toward ~$21. If $11.62 breaks, the long slide likely resumes. New trend or bear rally? #ElliottWave
Run this prompt in your agent and thank me later. Game changer
Create a dreamer cron that runs every night, checks past days crons and error logs and proactively fixes any issues it can to keep my jobs going
There’s 100% a kind of mania you can get into with coding agents, where it feels like you’re getting a lot done and working all the time but nothing is really happening.
I think it's often a form of avoidance of something else in life.
Gave my agent a stick-figure animator. I describe a scene, it plans the beats, checks the frames and renders an MP4.
Works in Claude Code, Codex and the rest:
npx skills add cherifya/figures
The Verge: "I don't think most people should buy an iPhone Duo yet."
iPhonedo: "You're going to love it."
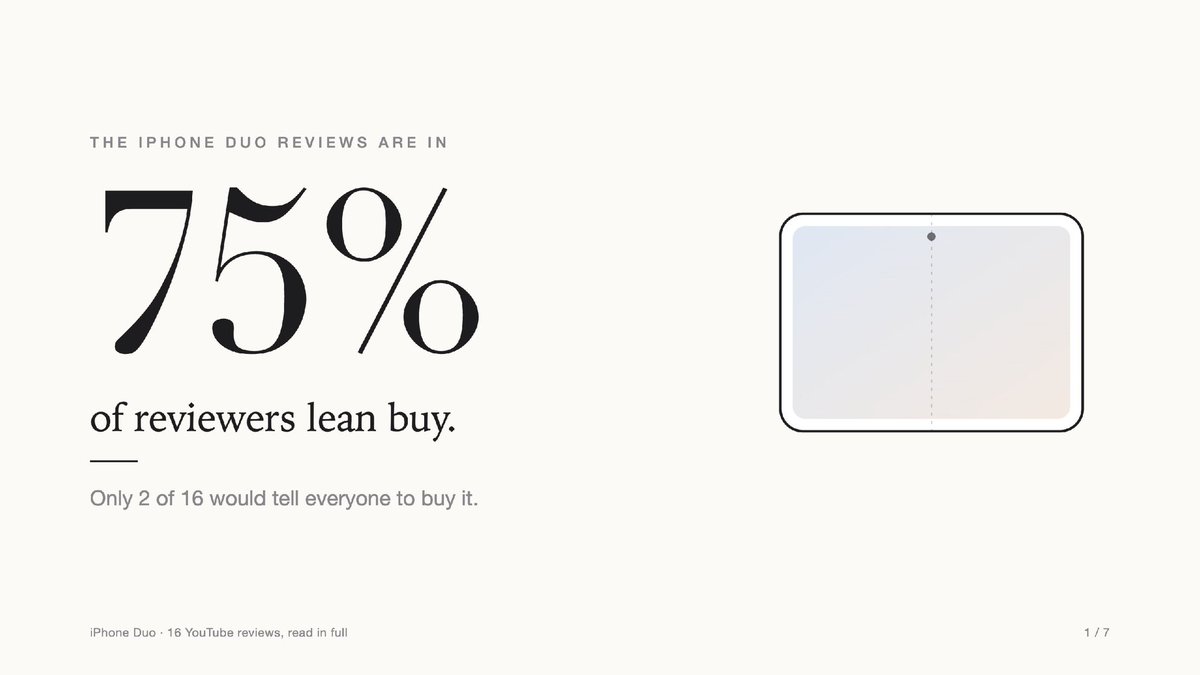
Finally the iPhone Duo reviews are in and I read them to see who's right. 12 lean buy. Only 2 say it's for everyone.
Almost all of them get hung up on the same things.
All 16 ran into apps that aren't built for the big screen yet. HTX Studio found 60% of the 25 popular apps they tested hadn't been updated. 15 missed a telephoto camera, since the Duo tops out at a 2x crop. 14 missed Face ID, because Touch ID in the side button takes some getting used to. It also starts at $1,999 and weighs 254 g, the heaviest iPhone Apple has made.
The hardware is a different story. 15 of 16 called out the 7.6" inner screen, 12 said the crease is barely visible and 11 praised the hinge. Joanna Stern ran hers through about 32,000 robot folds and it held up. CNET went from 8:15 a.m. to 11 p.m. and still had 29% battery left.
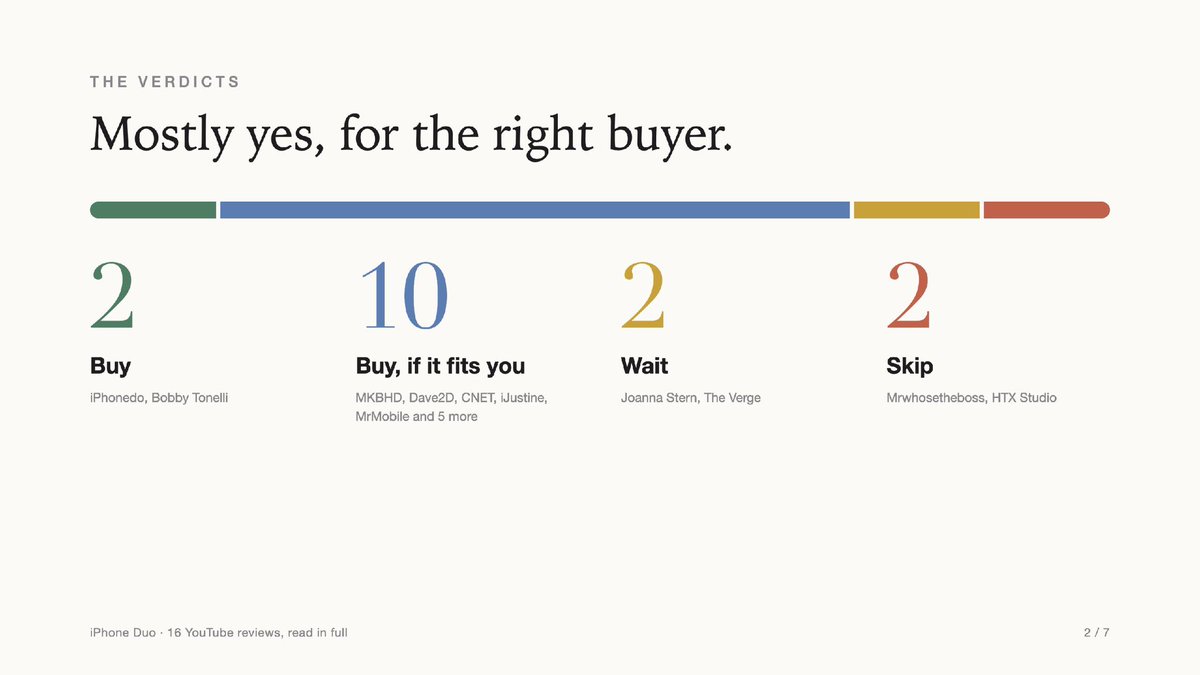
The split: 2 buy (iPhonedo, Bobby Tonelli), 10 buy if it fits how you use your phone (MKBHD, Dave2D, CNET, iJustine, MrMobile and others), 2 wait (The Verge, WSJ) and 2 skip (Mrwhosetheboss, HTX Studio).
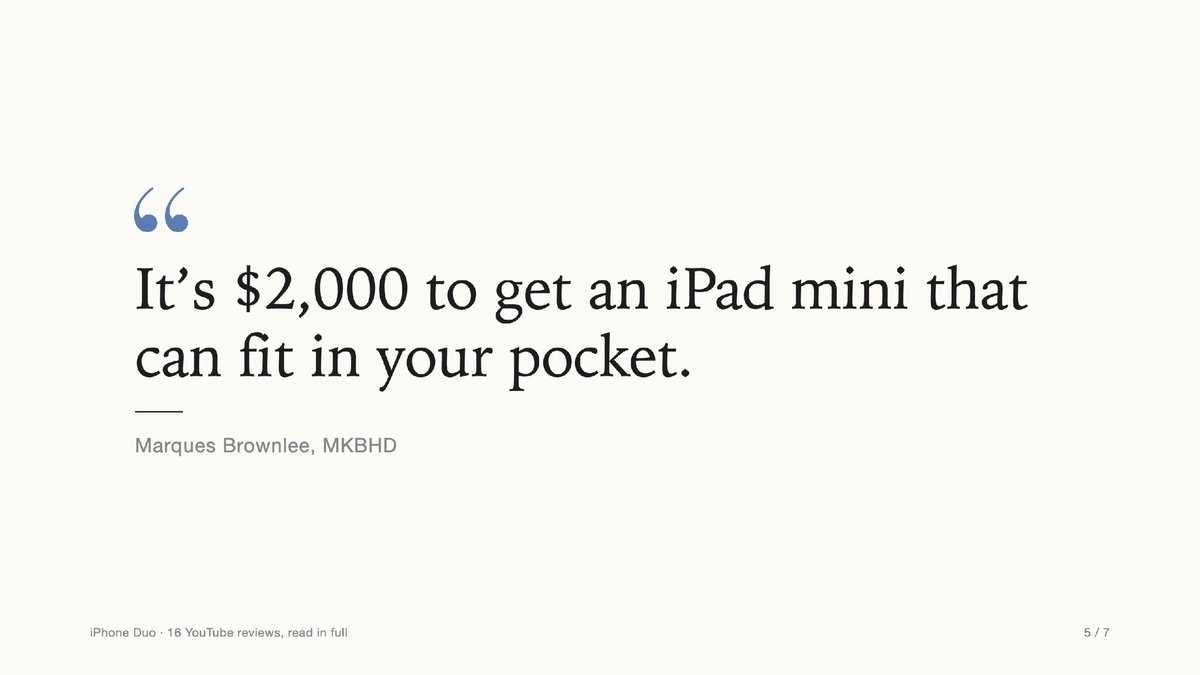
MKBHD put it best: "It's $2,000 to get an iPad mini that can fit in your pocket."
If you read, watch and multitask on your phone more than you shoot photos and video, most of these reviewers think you'll love it. If the camera matters most or you can't give up Face ID, they'd point you to the 18 Pro or tell you to wait for gen 2.
My take: I'm a heavy iPhone user, and a tablet-size screen I can actually get work done on that folds away into my pocket is really compelling to me. As an ex-Apple, I'm always excited when my old colleagues ship a new form factor.
I'll probably order one once the pre-order craziness dies down. New orders already ship in late January, so I'm not fighting for one this week.
Getting one, or waiting for gen 2?
my experience as well. Opus 5.5 seems to just get it. In heavy use over last weeks in my #Hermes agents, the number of times I had to rephrase a request is less than 1%. Btw, these are very complex prompts such as “build me a motion video for this or that…”
@AnthropicAI has a history of nerfing their best models a few weeks on, for whatever reasons. Please don’t. this model is just so good as it is. For now just enjoy it while it lasts.
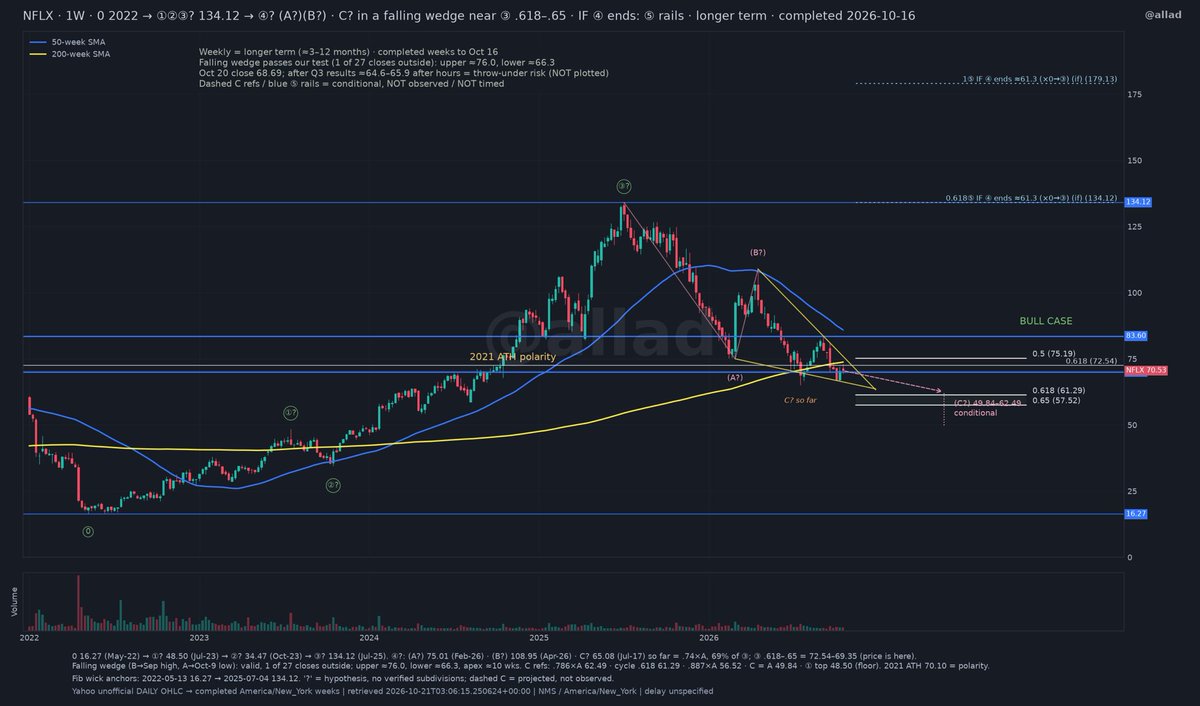
Wedge end or breakdown?
$NFLX sits on its 2021 high (~$70) after a 50% drop, inside a falling wedge. Post-Q3 selling risks a dip to ~$61–62, where supports meet. A quick move back above ~$73 would fit a washout; staying under $65 means more correction.
$IREN There is a path for this to be a $200 stock.
Here is my current count.
We are in the last leg of a much needed ABC correction after the monster run.
$IREN just hit the spot where this correction "should" end, and buyers stepped in on the heaviest volume in 5 months.
If ~$27 holds, the pullback is likely done and $49 is the next target to flip.
(Not financial advice)
I’m ok. Make no mistake: this is an attempt to target political enemies and weaponize federal law enforcement. For ten years, Trump has targeted me with baseless lies and smear campaigns. This is just the latest escalation in his campaign of political intimidation.
I will not be silenced.
@jtaby That’s beside the point isn’t it?… they are open source after all. What would it take to make it production grade with the right eval and tests set?
Not much.
5.5 Seems like a solid bump to the Haiku models.
Pretty much competitive with the previous gen frontier open source models like Kimi-K3 (one of my favorite models of all time).
On a related note, a little birdy tells me the frontier lab are probably distilling the n-1 gen frontier models to achieve this performance/cost ratio in the low end models.
Anthropic has released Claude Haiku 5.5, scoring 43 on the Artificial Analysis Intelligence Index - up 26 points one year after the last Haiku release
Haiku 5.5 is the first Haiku model with Anthropic’s effort settings and adaptive thinking, and Anthropic has introduced tiered pricing.
Haiku 5.5 is cheaper than its predecessor - it costs $0.10/$0.50 per 1M input/output tokens for prompts up to 100k tokens (the same as GPT-6 Luna and 10% of the previous Haiku model). However, this pricing rises 5x to $0.50/$2.50 above 100k. The site does not yet reflect tiered pricing, so provisional cost figures for Haiku 5.5 do not include the step up cost. We are working on support and will follow up with Cost per Task coverage soon.
Key takeaways:
➤ Leading small-class model performance: At max effort Haiku 5.5 sits slightly ahead of models such as GLM-5.3 Flash (42), Gemini 3.8 Flash (41) and GPT-6 Luna (38). Its score is comparable to Kimi K3 (44), a 2.8T parameter open weights model, and trails Claude Sonnet 5.5 (max, 56) by 13 points
➤ Heavy token use compared to GPT-6 Luna: Haiku 5.5 (max) uses ~162k output tokens per Intelligence Index task, ~3x GPT-6 Luna (max, ~50k). Moving from xhigh to max adds 2 points for ~1.8x the tokens. At similar intelligence it also uses more tokens than GPT-6 Luna: Haiku 5.5 (high) scores 38 with ~55k tokens per task against 38 with ~50k for Luna (max), and the gap widens at lower effort settings
➤ Highly capable at agentic knowledge work: on AA-Briefcase, our private evaluation for realistic knowledge work tasks, Haiku 5.5 (max) reaches 1578 Elo, ahead of models including Kimi K3 and GLM-5.3, and comparable to Muse Spark 1.3 (max)
➤ Improvements on terminal use: on Terminal-Bench 4.0 it scores 33%, up from 0% for Haiku 4.5. This is level with GLM-5.3 Flash, and ahead of Gemini 3.8 Flash (20%) and GPT-6 Luna (13%)
➤ Lower factual knowledge, but relatively low hallucinations: as expected for a smaller-class model, Haiku 5.5 has lower factual knowledge than its siblings. AA-Omniscience accuracy is 36%, against 55% for Gemini 3.8 Flash and 44% for GPT-6 Luna, but this is partly driven by more willingness to admit when it doesn’t know - its hallucination rate is lower, at 40% against 55% and 77%
➤ AutomationBench-AA result likely understated: Haiku 5.5 scores 35%, against 53–60% for GPT-6 Luna, Gemini 3.8 Flash and GLM-5.3 Flash. During pre-release testing, a safety refusal issue caused the model to over-refuse. Anthropic is working on resolving this - we will re-run this evaluation with the fix, and expect this score to rise
Other model details:
➤ Context window: 1 million tokens, up from 200k for Claude 4.5 Haiku
➤ Pricing: $0.10/$0.50 per 1M input/output tokens up to 100k tokens, $0.50/$2.50 above. Cache reads $0.01 ($0.05 above 100k), 5 minute cache writes $0.125 ($0.625 above 100k)
➤ Multimodality: Text and image input, with text output
Pick a challenge too big for who you are now.
That's how people change. A challenge above your level drags the new version of you out.
It will suck. You'll fail constantly. You'll feel like a fraud for months. Your old self will beg you to stay the same.
But if you can pull this off, 10-20 times throughout your life, you will blow past everyone else.
For anyone who still needs to hear this.
* Data is king *
Especially in the age of quasi infinite intelligence. I think we still don’t fully appreciate all the implications.