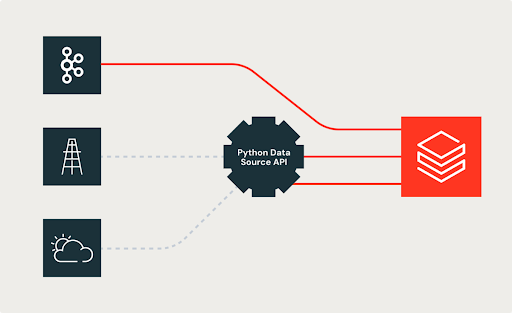
Apache Spark’s Python Data Source API simplifies data ingestion from custom sources. Now, data engineers can efficiently integrate a broader array of data sources and sinks into their Spark pipelines.
"The fact that we can now build, test, and surface reusable Spark data sources across the org will help our teams move faster and have more confidence in their work." - Bryce Bartmann, Chief Digital Technology Advisor, Shell
https://t.co/O3Bqoj58Ye
🚀 Introducing Python UDTFs in Apache Spark 3.5 & Databricks Runtime 14.0! Move beyond single scalar returns—now you can return entire tables. Explore our @langchain example leveraging GPT-4 within Python UDTFs! https://t.co/5USyzewV4u
#ApacheSpark#PySpark#LLM#Databricks
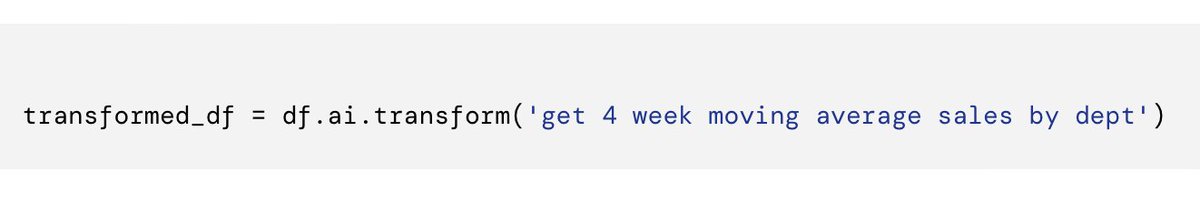
One of my favorite announcements: English SDK for @ApacheSpark! No more need to remember weird syntax, just chain transformations in natural language with the familiar Spark API. So many fun examples.
https://t.co/4JNfwPEElp