🎓 On July 9, 2026, I successfully defended my PhD dissertation and was awarded the degree of Doctor of Philosophy (PhD) in Computer Science at Lviv Polytechnic National University.
Dissertation title:
"Methods and Technologies of Natural Language Processing for Program Code Generation."
Academic supervisor:
Yaroslav Vykliuk, Doctor of Technical Sciences, Professor, Department of Artificial Intelligence Systems, Institute of Computer Science and Information Technologies, Lviv Polytechnic National University.
My research focuses on building autonomous AI agents capable of planning, reasoning, collaborating, and solving complex long-horizon tasks with minimal human intervention. The dissertation introduces new approaches to multi-agent architectures, reasoning management, and reinforcement learning aimed at improving the reliability and adaptability of modern AI systems.
The research introduces two key contributions:
• Thought Management System (TMS) — a hierarchical reasoning framework that enables LLM agents to maintain structured reasoning and execute long-horizon, goal-driven tasks more reliably. (Published in the Journal of Computational Science, Elsevier.)
• LLMAgentNet — a collaborative network architecture that allows autonomous AI agents to coordinate, delegate tasks, and solve complex problems as a distributed multi-agent system.
I am sincerely grateful to my academic supervisor, the dissertation committee, my colleagues, friends, and family for their guidance, encouragement, and support throughout this journey.
This milestone marks the end of one chapter and the beginning of another. I'm excited to continue advancing research and building reliable AI systems for the next generation of autonomous agents.
---
🇺🇦 Успішний захист дисертації PhD
9 липня 2026 року я успішно захистив дисертацію та здобув ступінь доктора філософії (PhD) за спеціальністю 122 «Комп'ютерні науки» у Національному університеті «Львівська політехніка».
Тема дисертації:
«Методи та засоби обробки природньої мови для генерації програмного коду».
Науковий керівник:
Виклюк Ярослав Ігорович — доктор технічних наук, професор, професор кафедри систем штучного інтелекту Навчально-наукового інституту комп'ютерних наук та інформаційних технологій Національного університету «Львівська політехніка».
Моє дослідження присвячене створенню автономних AI-агентів, здатних самостійно планувати, міркувати, взаємодіяти між собою та виконувати складні довготривалі завдання. У роботі запропоновано нові підходи до побудови мультиагентних систем, управління процесами міркування та використання навчання з підкріпленням для підвищення надійності й адаптивності сучасних систем штучного інтелекту.
У межах дослідження було запропоновано два ключові результати:
• Thought Management System (TMS) — система управління процесами міркування AI-агентів, що забезпечує ефективне виконання довготривалих задач і стала основою однойменної статті, опублікованої в журналі Journal of Computational Science (Elsevier).
• LLMAgentNet — архітектура децентралізованої мережі автономних AI-агентів, яка забезпечує координацію, розподіл задач та спільне виконання складних сценаріїв у мультиагентному середовищі.
Щиро дякую науковому керівнику, членам спеціалізованої вченої ради, колегам, друзям та рідним за підтримку, поради й віру протягом цього шляху.
A 9B model keeps 82% of a 397B model's score.
Ornith 1.5 on Claw-Eval: 397B 81.4, 35B-A3B 72.5, 9B 66.5
On WideSearch: 397B 80.8, 35B-A3B 67.8, 9B 59.5
About 44 times fewer parameters for 74 to 82% of the score. Would you take that trade?
Double the context, lose up to 12.2 points.
IBM Granite 4.2 on RULER, 64k vs 128k tokens:
30B: 89.96 to 81.38
8B: 80.99 to 71.41
3B: 67.52 to 55.3
The smaller the model, the bigger the drop. How long are the prompts your agent really sends?
GTA6 heist: one guard, one vault, one perfect run.
Real life: one bug, one deadline, one "it works on my machine".
Both are beatable. Neither is enjoyable.
Same energy on Benchgen's side of the screen: one benchmark, one board, one number that holds up. 🧠
Grand Theft Auto VI spent a decade building one world.
We spent a decade building one leaderboard.
Both of us are just waiting for the loading screen to finish.
What is your favorite loading screen?
GPT-6.2 Astra now leads 3 of our reasoning & science boards:
GPQA Diamond: 97.0% (#1 of 114)
ARC-AGI v2: 95.8% (#1 of 18)
Terminal-Bench-Science 0.1: 77.1% (#1 of 11)
Vals Index: 67.66% (#7 of 41)
Which task makes you switch to it first?
@AnthropicAI@DarioAmodei Clean retrieval shift with CRISPR. How does tail latency look once CPU-to-GPU transfers kick in under concurrent user queries?
New paper: Mind2Act World: A Diagnostic Benchmark for Embodied Mind, Physical Action, and Mind-Action Composition...
Does this shift how you test agents? (Paper link in reply)
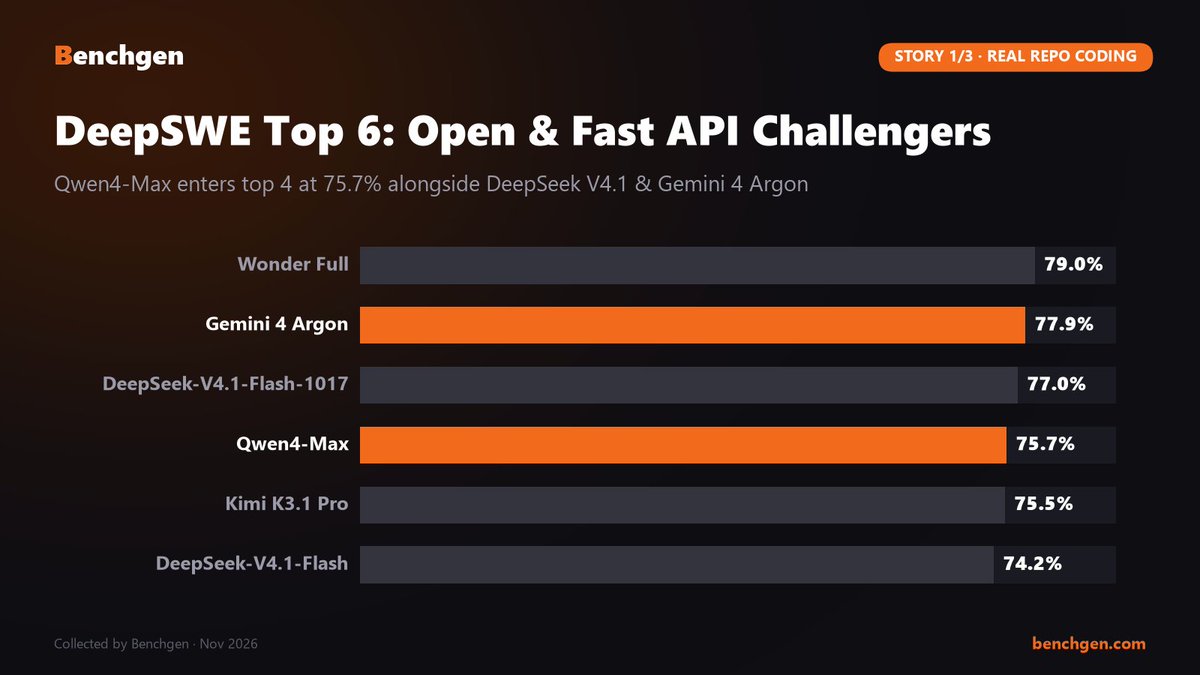
Chapter 1/3: Stop picking coding models off general chat vibes.
On DeepSWE, Qwen4-Max scores 75.7% at a fraction of legacy flagship pricing.
Does repo-level SWE testing match what your team sees?
Chapter 2/3: Why PhD difficulty and real ROI don't track 1-to-1.
GPT-6.2 Astra hits 97% on GPQA Diamond and 77.1% on Terminal-Bench Science, while Muse Ember scores 75.69% on Vals Legal at USD 0.10/0.50.
Would you route legal tasks separately?