I run chaos experiments across 200+ services at Prime Video.
The goal is never to break things. It's to find out what breaks before a live event does it for you.
Next: what a real game day looks like from the inside.
Follow so you don't miss it.
Netflix made chaos engineering famous.
Most engineers took one lesson from it: randomly kill servers and see what breaks.
That's not chaos engineering. That's just breaking things. Here's what it actually is and why the difference matters at scale...
🧵👇
Where most chaos programs die:
- They only test in staging (prod has different load patterns)
- No defined steady state, so results are uninterpretable - Teams treat it as a one-time exercise, not a practice
- Findings go into a doc nobody reads Process beats tools. Always.
The right mental model for agent routing:
→ Resolve intent once (Phase 1)
→ Pin the model for the session (Phase 2)
→ Let cache do the work on every turn after
Pay for the routing decision once. Collect savings on turns 2 through 15.
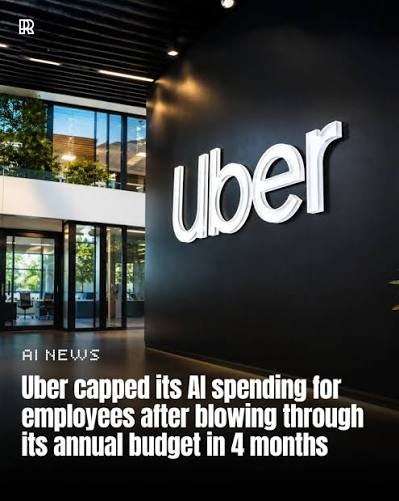
Uber gave 5,000 engineers Claude Code in Dec 2025.
By April 2026, the entire annual AI budget was gone.
Nothing broke. Engineers used it exactly as intended.
The problem: a docstring lookup and a distributed systems refactor cost the same.
A 1.5B model fine-tuned for routing beat Claude 3.7 Sonnet on accuracy.
28x faster. Not a benchmark trick.
General models aren’t optimized for intent classification. A model built for one job destroys a model prompted for it.
A useful production observability stack should help answer 3 questions quickly:
What happened?
Logs
Why did it happen?
Context and traces
Is it happening right now?
Metrics and alerts
ELK solves a major part of this, but observability is bigger than logs.
Next up : @datadoghq
Your production logs are useless if you can't answer one question:
"What exactly went wrong?"
That becomes difficult when thousands of services generate millions of log lines every day.
This is where an observability stack becomes critical.
🧵 👇🏻👇🏻
#application#observability
Elasticsearch is powerful, but indexing everything blindly gets expensive. A production setup usually needs:
• Log retention policies
• Index lifecycle management
• Sampling for noisy logs
• Appropriate shard sizing
• Separate storage for older data
Observability has a cost.
The Cheat Sheet
Stop memorizing system design architectures.
Memorize the trade-offs:
SQL ↔ NoSQL: consistency vs flexibility Sync ↔ Async: latency vs throughput Cache ↔ DB: speed vs freshness Monolith ↔ Microservices: simplicity vs independence
Understand the trade-offs.
1/6 The Cheat Sheet — System Design When designing a system, don't ask:
"What is the best technology?"
Ask:
"What am I willing to sacrifice?"
Good system design isn't about avoiding trade-offs. It's about choosing them deliberately.
🧵👇🏻
5/6 The Insight — System Design The simplest architecture is often the easiest to scale.
Not because simple systems handle infinite traffic.
Because complexity has a cost.
Every queue, cache, replica, and service adds another failure mode.