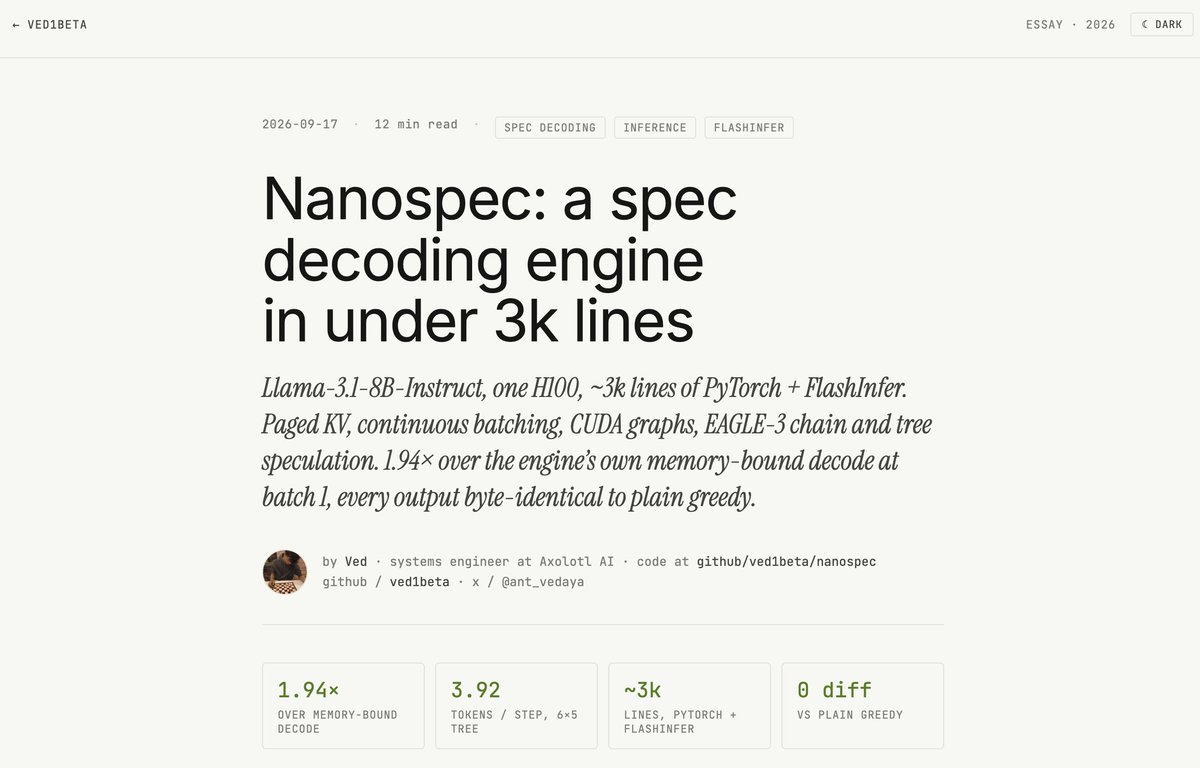
writing a speculative decoding engine from scratch in ~3k lines of PyTorch + FlashInfer. Paged KV, continuous batching, CUDA graphs, EAGLE-3 chain + tree. 1.94× at batch 1 on an H100, every output byte-identical to greedy. Blog coming soon
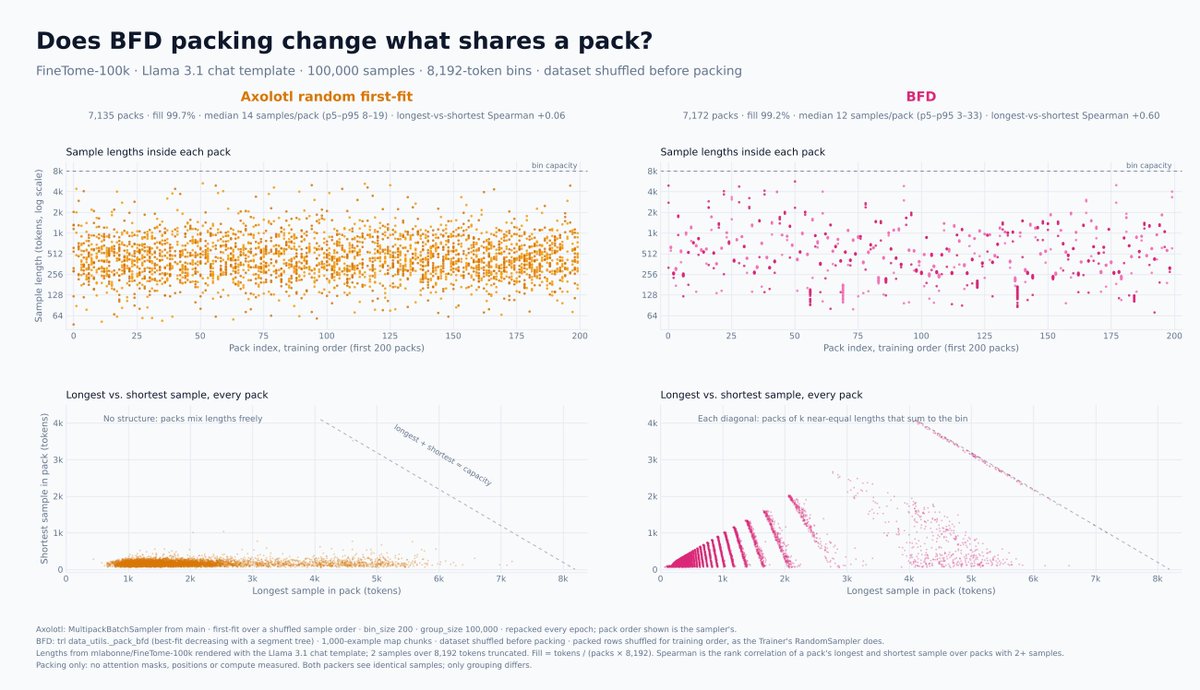
Using BFD, you end up with longer samples getting paired up with smaller samples. Depending on the correlation of tasks to sample lengths, this can lead to some pairing off of tasks within a batch (at smaller effective batch sizes).
coming up with a big release soon !
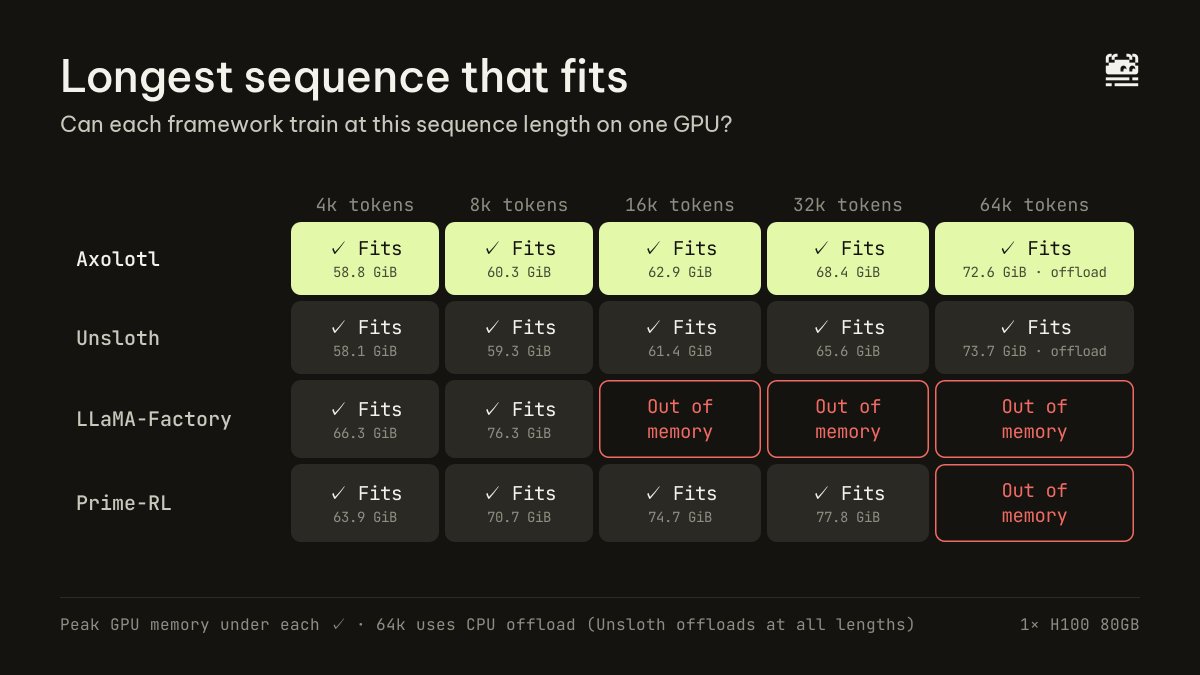
So benchmarked fine-tuning GLM-4.7-Flash on a single H100 against three other popular training frameworks.
Same model, same data, same 21M LoRA params, 32k tokens per step.
If you're curious why they only reported against TRL for their single GPU SFT on GLM Flash, it's because at that regime, they're still slower than Axolotl by about 5% (can't find any B300s, so using B200s). But hey, reporting benchmarks these days is just about cherry-picking data, right?
on to some personal research.
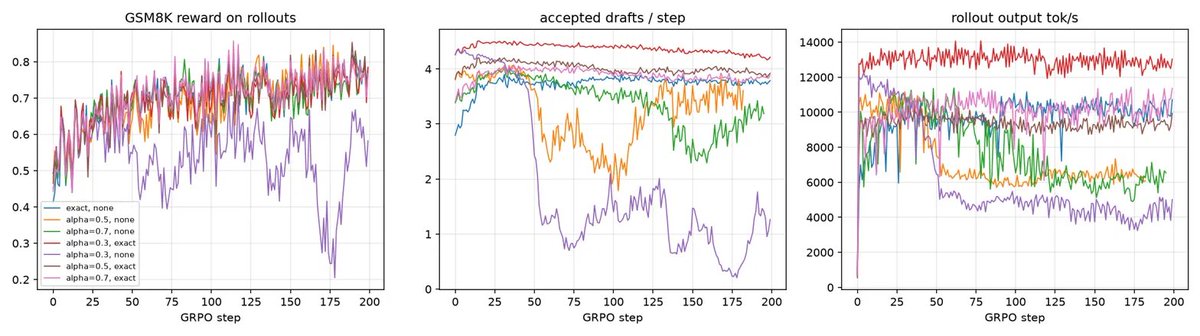
speculative decoding inside GRPO rollouts.
the Question: how lossy can you make draft acceptance before RL training breaks?
answer: very lossy, if the trainer knows what the sampler did.
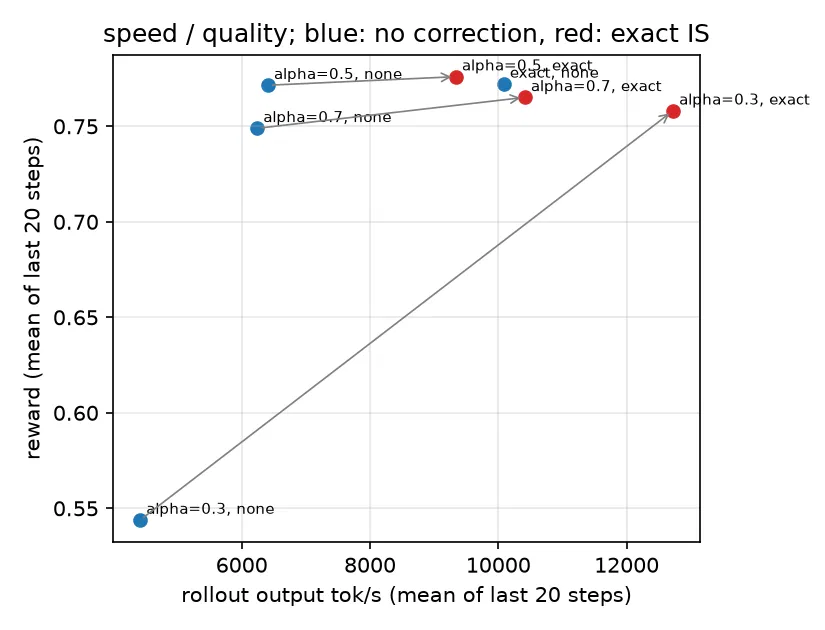
x axis is rollout throughput, y is reward after 200 steps. blue = lossy acceptance, no fix. red = same acceptance + the fix. the long arrow is the whole paper: 26% faster than lossless, same reward.
preprint sooon. rollout engine is nanospec, GRPO loop is ~400 lines, all on one H100 for under $50.
writing a speculative decoding engine from scratch in ~3k lines of PyTorch + FlashInfer. Paged KV, continuous batching, CUDA graphs, EAGLE-3 chain + tree. 1.94× at batch 1 on an H100, every output byte-identical to greedy. Blog coming soon
writing a speculative decoding engine from scratch in ~3k lines of PyTorch + FlashInfer. Paged KV, continuous batching, CUDA graphs, EAGLE-3 chain + tree. 1.94× at batch 1 on an H100, every output byte-identical to greedy. Blog coming soon
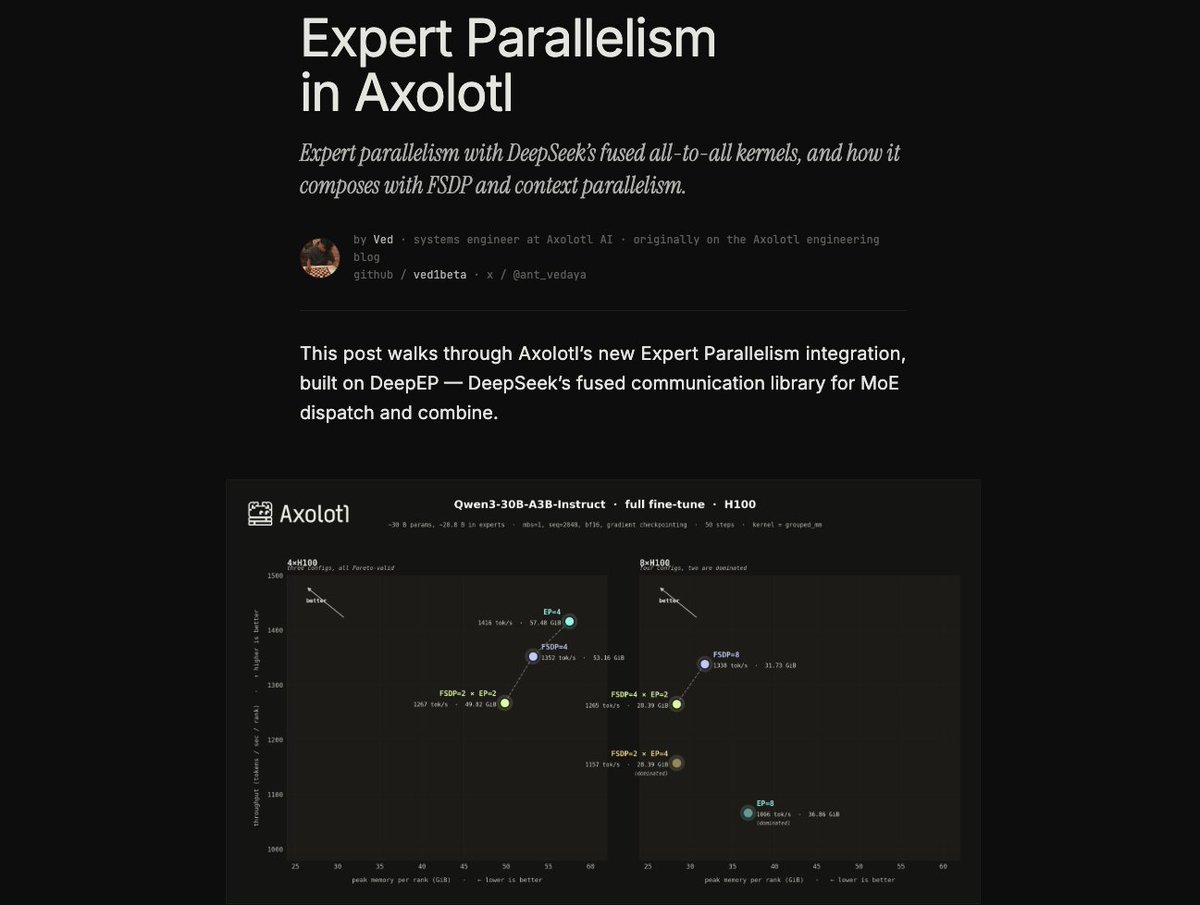
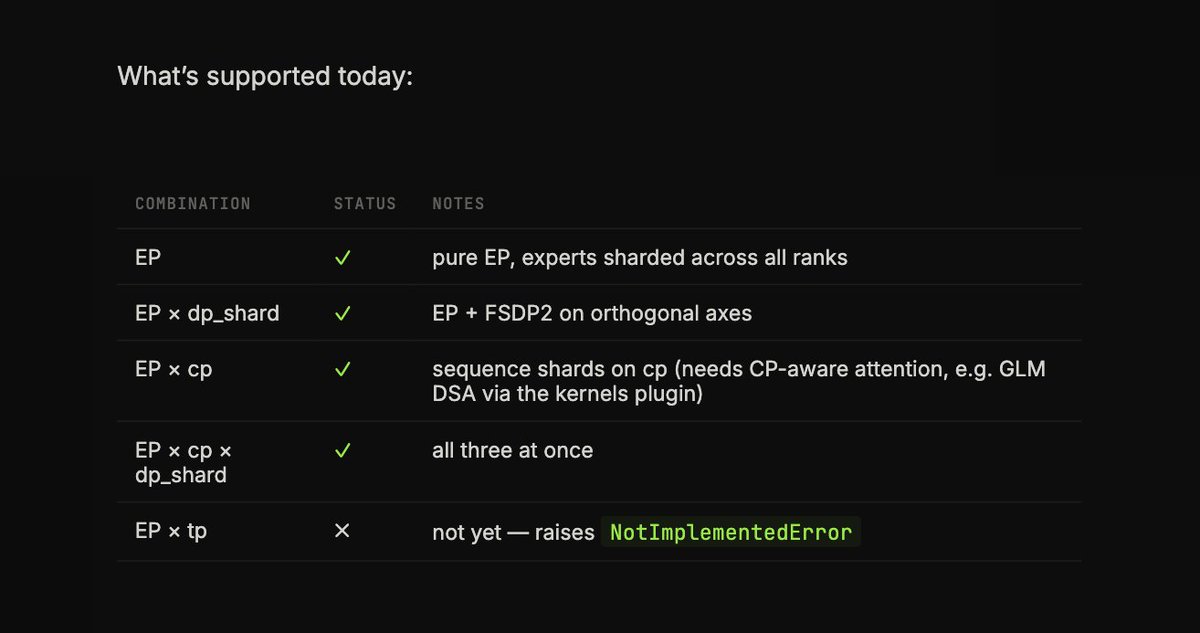
Is there another trainer that composes EP × CP × FSDP2 on unmodified HF transformers models? prime-rl and torchtitan do it with their own modeling code. Axolotl does it by patching the experts path in transformers. Curious what else exists.