Authors from Queensland Uni., RMIT, CSIRO, and Adelaide Uni. introduced a lightweight viewpoint-aware self-correction strategy that explicitly signals frame-of-reference changes and guides models to revise viewpoint-sensitive reasoning.
https://t.co/uhnBgROK16
#LMM@SpringerEng
Andrew Ng just released a free 2-hour course on complete Graph Engineering
How to go from one prompt to 100 agents running inside self-improving graphs:
09:14 - Build your first agent from scratch
33:11 - Master loop engineering
1:02:46 - Turn agent loops into graphs
1:30:15 - Build agents that rewrite themselves
1:49:05 - Run the full graph system without you
Prompts → Context → Workflows → Feedback → Loops → Graphs
Most graph tutorials stop at the diagram
This one has you running a real graph within the first 20 minutes
Most people are still prompting one agent at a time
Andrew Ng is already teaching the layer above:
Self-improving systems that build and run themselves
Watch this brilliant course and build the graph
Then read the full architecture below ↓
Andrej Karpathy’s 1-hour Stanford lecture on AI engineering is one of the best explanations I’ve seen of how AI systems actually work.
The progression is simple:
10% → LLM
30% → Prompt
50% → Agent
70% → Loop
100% → Graph
The key takeaway:
AI engineering isn’t just about writing better prompts.
It’s about building systems around models — giving them context, memory, tools, feedback loops, and data flows.
“Delete everything, keep Graph.”
Definitely worth watching if you’re building with AI agents.
Watch → Bookmark →
🔥Check out the first comprehensive review of multimodal composite retrieval, which is a timely complement of multimodal fusion to existing reviews.
🔗https://t.co/fCkQldBgtt
#Compositeretrieval#Multimodalfusion@SpringerEng
Now online! The authors created the Chinese audio-visual deepfake (CHAV-DF) dataset, which is the first dataset designed for the temporal forgery localization (TFL) in the Chinese context.
https://t.co/OBOltAsaKC
@SpringerEng#deepfake#Crosslingual#TFL
🚨Call for Papers: Special Issue on "Visual Intelligence in Holistic Healthcare"📊💡
Submit your work on new vision methodologies and their translational applications for the SI!
Deadline: 31 Oct. 2025
Details: https://t.co/jzToLuuYW9
@SpringerEng@SciOpenTUP
📢Call for Papers! The Special Issue "Controllable Artificial Intelligence Visual Content Generation" is still open for submissions. Don't forget to submit your paper!
🗓️Submission deadline: 31 August 2025
🔗https://t.co/S9jrLnuaIb
@SciOpenTUP
Call for papers: Australasian Joint Conference on Artificial Intelligence (#AJCAI2025)
Dates: 1-5 Dec 2025
Location: Canberra, Australia
Paper Submission: 15 July 2025 AoE
Website: https://t.co/GZfXVF57GB
Great opportunity to visit Australia and Australian Parliament House
Call for papers: Australasian Joint Conference on Artificial Intelligence (#AJCAI2025)
Dates: 1-5 December 2025
Location: Canberra, Australia
Paper Submission: 15 July 2025 AoE
Website: https://t.co/ALhUcKhYRD
A good opportunity to visit Australia!
We are pleased to announce the composition of its Human Rights Expert Group for the 2024-2027 term.
They will provide expertise, develop policy recommendations, and support WFD’s advocacy efforts to promote and protect the rights of deaf people worldwide.
I am so proud my research team has made great progress on AI empowered Auslan recognition and translation. Wish our developed algorithms and systems can facilitate the Deaf community in daily life! More importantly, thank our deaf friends for helping better scope our research!
I am very honored to be nominated as a finalist for the Most Outstanding Use of AI for Social Good as part of the Queensland AI Award 2024. @QldAIAwards @QLD_AI_Hub I would like to thank my amazing students. They work so hard with me on Auslan dataset creation for ML purposes.
Adobe presents SynCHMR!
A method that can reconstruct camera trajectory, human motion, and scene in one global coordinate from videos 🔥
https://t.co/b8W9AQkfHe
Diffusion4D: Fast Spatial-temporal Consistent 4D Generation via Video Diffusion Models
https://t.co/dODkUvXRFj
Project: https://t.co/7Kuv0jKbew
Video: https://t.co/h0Lm0UfQ3x
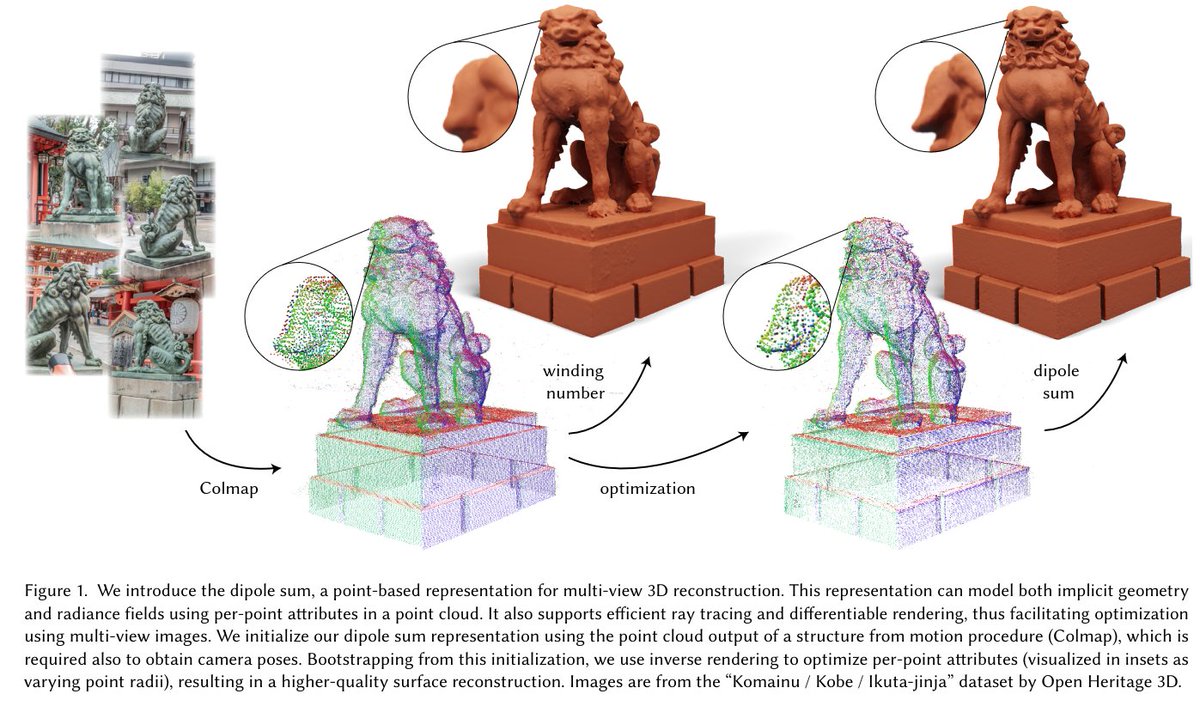
Another interesting paper I'd like to share takes a different approach to mesh reconstruction from images. On their website, you can compare their approach with Gaussian Surfels and NeuS2.
"3D Reconstruction with Fast Dipole Sums"
https://t.co/aMUcVm3SPe
https://t.co/35buCriUSB
Are you super excited for the 🛫 PERTH THINKING LAB? Us, too!
We've decided to open up the applications for an additional week ✨ so you have all the time you need you to prepare your application. It's super easy! Just fill out a few questions about yourself and why you want to
I believe in making academia a more inclusive part of society.
We can't label qualities like having formal education as a "degree of marginalization" - they're basic qualifications in an academic career.