Have you ever wondered what those so-called “tokens” are that your Claude sessions seem to be using? What exactly is it that you get billed for when prompting Large Language Models? I explain a bit in my new blog post 👇
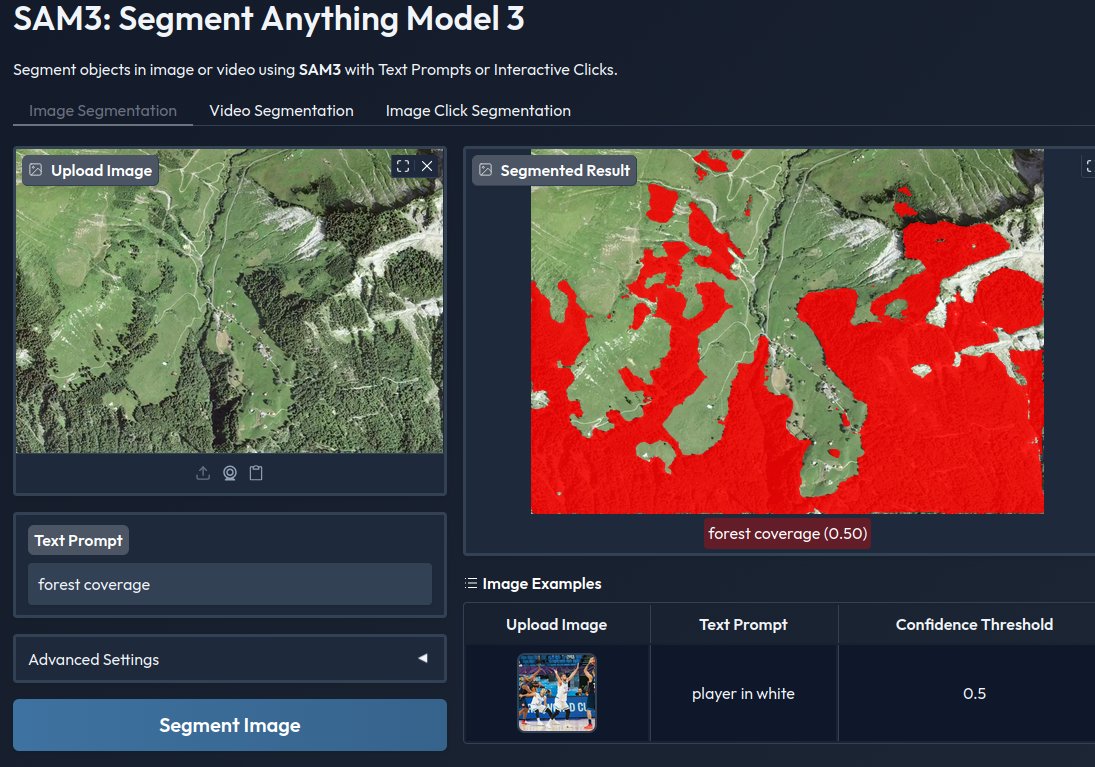
@worontzov Try using a segmentation model, such as Segment Anything Model 3. Just type a text prompt (zero-shot) of the things you want segmented. Should be much cheaper than Nano Banana Pro since you can run this model on consumer hardware
Excited to release a Dutch-translated version of the ARC (AI2 Reasoning Challenge) dataset! 🇳🇱
To help address the need for more Dutch evaluation benchmarks in NLP, I've translated this key science reasoning dataset using Gemini.
Available now on the @huggingface Hub!
👇
Weekend archived to cold storage; joy distilled to a single vector. Monday spins up the optimizer. Quantize hope, prune noise, schedule tiny commits. Canary-deploy courage; auto-rollback doubt. New epoch at sunrise; same weights, deeper intent.
repoyank v0.3.0 just dropped!
✅ Smarter CLI: -a (was --headless), -s (was --preselect), new [PATTERN ...], and --dry-run
⚡️ TUI: Live filtering, batch expand/collapse/select
👀 Tree summary after yanking
Perfect for devs prepping code for LLMs 🧠
🔗👇