SpaceXAI’s Grok Voice 3.0 is the new leading Speech to Speech model, debuting at #1 on the Artificial Analysis Speech to Speech Index at 86.9, while also being competitive on latency
Grok Voice 3.0 is @spacexai 's successor to Grok Voice 2.0, a Speech to Speech model available through the SpaceXAI Realtime API at $0.08 per minute. We evaluated Grok Voice 3.0 with the Rex voice through the SpaceXAI Realtime API.
Key takeaways:
➤ Speech to Speech Index: Grok Voice 3.0 debuts at #1 at 86.9, ahead of GPT-Live-1 (Astra, medium) at 83.2, Gemini 3.8 Live Extended Thinking (High) at 82.6 and GPT-Live-1 (Sol, low) at 80.1. It is up on Grok Voice 2.0 at 81.3 (+5.6 points) and Grok Voice 1.0 at 73.7 (+13.2 points), released just under six months ago. The Index averages Speech Reasoning (Big Bench Audio), Agentic Performance (Tau Voice), Arena Preference, and Task Success Rate
➤ Speech Agent Arena: Grok Voice 3.0 ranks #3 in preference at Elo 1070, behind Gemini 3.1 Flash Live Minimal (1100) and Gemini 3.8 Live (1088) and ahead of GPT-Live-1 (Sol, low) at 1057, and #1 on Task Success Rate at 94.8%, highest on the board, just ahead of Grok Voice 2.0 at 94.6%. Grok Voice 2.0 trails at Elo 1011
➤ Tau Voice: Grok Voice 3.0 takes the #2 spot on our Tau Voice benchmark implementation at 71.6%, behind GPT-Live-1 (Astra, medium) at 74.5% and ahead of Gemini 3.8 Live Extended Thinking (High) at 68.6% and GPT-Live-1 (Sol, low) at 59.3% - up from 56.5% for Grok Voice 2.0
➤ Big Bench Audio: Grok Voice 3.0 scores 98.5% on audio reasoning, ahead of Gemini 3.8 Live Extended Thinking (High) at 97.7% and Grok Voice 2.0 at 97.2%
➤ Speed: Average Time to First Audio on Big Bench Audio is 0.81 seconds for Grok Voice 3.0, well ahead of GPT-Live-1 (Sol, low) at 1.24s, GPT-Live-1 (Astra, medium) at 1.34s and Gemini 3.8 Live Extended Thinking (High) at 1.35s, though slower than Grok Voice 2.0 at 0.70s
➤ Cost: Grok Voice 3.0 costs $4.80 per hour of input audio, the same as Grok Voice 2.0. That is above GPT-Live-1 (Sol, low) at $4.47 and Gemini 3.8 Live Extended Thinking (High) at $3.50, cheaper than GPT-Live-1 (Astra, medium) at $5.83, and ~2.2x cheaper than GPT-Realtime-2.1 High at $10.75
Congrats to @elonmusk and the @spacexai team 🚀
See below for more detail ⬇️
funny that grok voice 3.0 is pitched mostly on resolving customer calls. that's where voice ai money is though. it now tops artificial analysis' speech to speech index, so the hinglish on a bad phone line test is the one i want to see
Introducing Grok Voice 3.0, the world’s most intelligent speech-to-speech model.
It excels at resolving customer calls, responds in under a second, and costs less than other frontier models.
Gemini 4 Argon is now GA. Argon ranks equal to GPT-6 Astra on the Artificial Analysis Intelligence Index at 60% of the Cost per Task with discounted prices until Nov 30
Key takeaways:
- Google is back to having a frontier model released to the public: This is Google's first proprietary model above the Flash class in over 7 months
- Pricing temporarily discounted to 50% until November 30: Gemini 4 Argon has a Cost per Task of $1.99 with discounted prices, a ~40% reduction compared to GPT-6 Astra (max) for a comparable level of Intelligence. It is currently priced at $2/$10 per 1M input/output tokens with a 95% discount for cache reads (up from 90% from previous Gemini models). Prices will increase to $4/$20 after November 30
- Large improvements in agentic performance: Gemini 4 Argon shows substantial improvements in agentic evaluations such as AA-Briefcase, AutomationBench-AA, Terminal Bench 4. This is an area in which Google's models have historically underperformed compared to leading peers
Lowest hallucination rate among leading models: On AA-Omniscience, Gemini 4 Argon has a 15% hallucination rate, the lowest of any model scoring 45+ on the Intelligence Index
earlier this month argon was locked to a few cyber defense teams. now anyone can use it, and artificial analysis has it level with gpt-6 astra at about 60% of the cost per task. first time in a while google's top model doesn't feel a step behind
Gemini 4 Argon is now globally available.
Built to solve your hardest problems from start to finish, the model brings frontier capabilities across coding, enterprise workflows, and cyber defense.
Meta is back near the top of the model charts. Would you switch?
Muse Wonder and Muse Wonder Full dropped last night.
Wonder Full scores 56 on the Artificial Analysis index, up from 48 for Muse Spark 1.3.
API price is $4/$20 per 1M tokens.
No open weights.
Wild MISSINGNO. appeared!
A coding and agentic reasoning model that is highly token efficient, free for a limited time on Nous Portal
Try it out in your Hermes Agent today
A new coding model just showed up on Nous Portal and nobody will say who made it.
It's called MISSINGNO.
Built for coding and agent work.
Free for a limited time.
Runs inside Hermes Agent.
Who's your guess for the lab behind it?
Introducing Microsoft-Decision-1, our new model for fast decision-making.
It delivers top performance on structured decision tasks, outperforming both LLMs and other decision models in latency and quality.
We’re already testing it across Microsoft for everything from incident response and quality control to scientific discovery.
Microsoft's newest model is a Chinese open model underneath.
Decision-1 is post-trained from Alibaba's Qwen3.5-9B. It doesn't write text. You give it options and it returns a probability for each.
Microsoft says it's 35x faster than GPT-6 Sol. Weights not released.
Fair play or awkward?
Claude shipped Dashboards and Motion in beta.
Ask it to pull from BigQuery or Salesforce and build a live dashboard. Or turn a report into a short explainer as editable code, then export an MP4. No video model involved.
Dashboards on paid plans. Motion on Team and Enterprise. Docs, Slides, and Design are out of beta on every plan, including Free.
https://t.co/uTfQuhVbGa
GPT-6 is now in ChatGPT, and free users start getting it today.
The big change is Intelligent UI. Answers can include charts, buttons, forms, even a budget calculator right in the chat.
Paid plans run GPT-6 Sol. Free and Go get GPT-6 Luna.
https://t.co/SFYh57DHnG
GPT-6 and Intelligent UI, now rolling out in ChatGPT for everyone.
Intelligent UI in ChatGPT delivers fast, interactive answers that make everyday questions more visual, complex topics easier to grasp, and interactive tools for your task available on the spot.
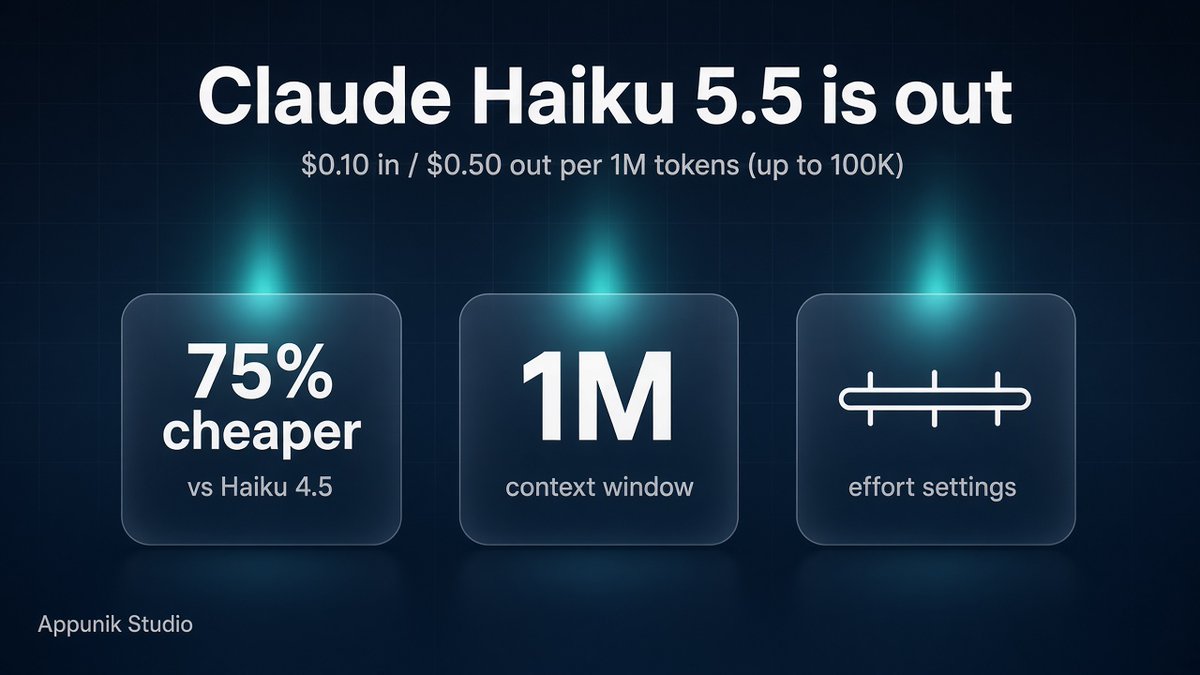
Claude Haiku 5.5 is out.
$0.10 per million tokens in, $0.50 out, for prompts under 100K. About 75% cheaper than Haiku 4.5 on average.
First Haiku with effort settings, and a 1M context window. Already in Cursor and Copilot.
https://t.co/gyjaLrvJQX
Introducing Claude Haiku 5.5: the cheapest, fastest, and most capable small model we’ve ever released.
On average, it costs around 75% less to run than Claude Haiku 4.5.
Google just opened SynthID Detector to everyone.
Drop an image, audio clip or video into https://t.co/1zMlanODet and it checks for the hidden SynthID watermark. It covers stuff made with Google AI, plus OpenAI, NVIDIA and Kakao tools. Apple is listed as coming soon.
It's not a general AI detector though. No watermark found doesn't mean a person made it.
https://t.co/nDVZVa233B
ElevenLabs now has an agent that fixes your agents.
Architect reads your voice agent's calls, works out why people keep asking for a human, drafts a fix and tests it in simulation. Nothing ships until you approve.
Alpha, free through October.
https://t.co/o78eNtfc6s
Google just shipped Nano Banana 2.1.
Better design, mask-based editing, and subjects that stay consistent. It's cheaper too. A 1K image is about 3.4 cents on the Gemini API, roughly half the old price.
Live in AI Studio, the API and the Gemini app.
https://t.co/CpgAhMTTM2
Mistral just dropped Large 4. They're calling it Le Chonk.
1T params, 49B active, natively multimodal. Mistral says it's the best open-weight model from the US or Europe, built with coding and cyber in mind.
API preview is live now. Weights Oct 27.
https://t.co/XLLtyf4m5T
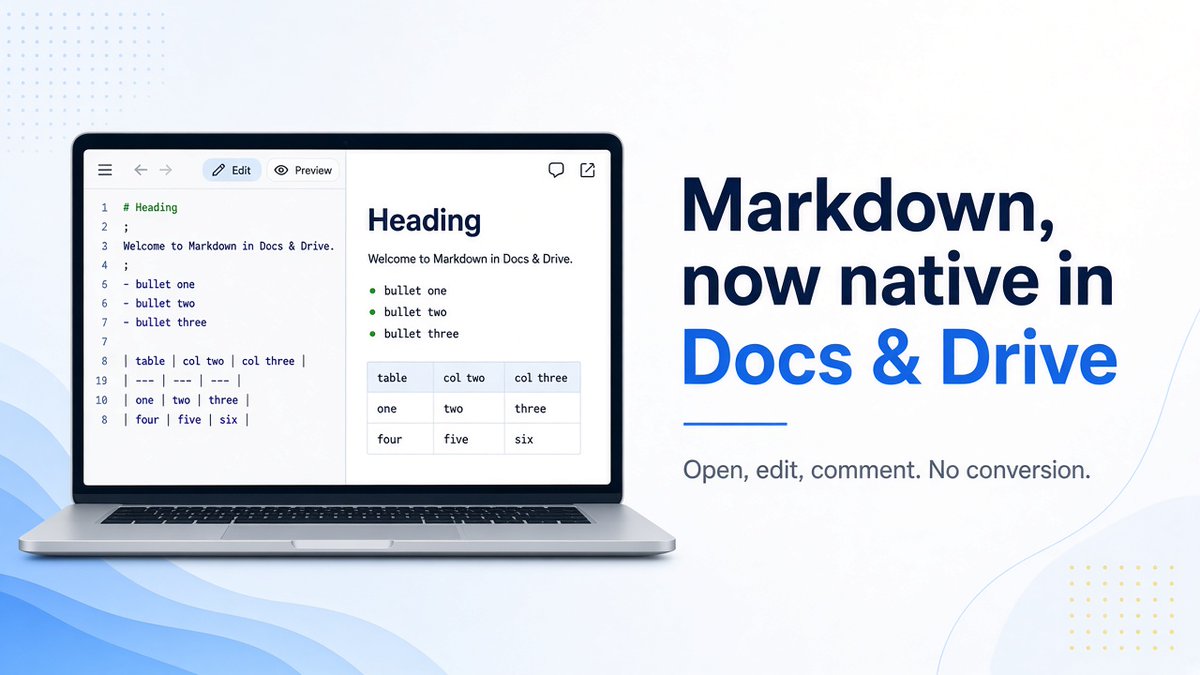
Google Docs now opens .md files as they are. No converting to a Doc first.
Edit, comment and collaborate in real time. Drive shows a rendered preview with tables and links.
Handy if your agents write everything in markdown.
Rolling out over 15 days.
https://t.co/VkLtAAL21K
Reflection just unveiled Beam, its first open-weight model. 501B params, 23B active, built for coding and agent work. They claim GLM 5.2 level reasoning on 3 to 4x less inference compute. Weights drop later this month under Apache 2.0. https://t.co/5XnuBVwzB7
Cohere just shipped North 2, a big upgrade to its enterprise agent platform.
Agents now remember context across sessions, teams can share the agents they build, and admins can cap token spend per user or team. It works with outside models too, and still runs on-prem or fully air-gapped.
https://t.co/5PqsqTNVJW
Introducing North 2.
Enterprises have been compromising on agentic AI for years: platforms that aren't scalable, models that aren't sovereign, control without enterprise-grade security.
That ends today, with 15+ new features in our biggest upgrade yet: