Day 6 ended with a new idea: instead of sharing keys and values, change which words a head is even allowed to look at. The first attempt at this was in 2019, and it worked, but it didn't catch on the way you'd expect. Day 7.
Day 5 ended with a question: how do you shrink that cache without losing what made attention work so well? I wrote and implemented all three from scratch myself, MHA, MQA, and GQA, and checked the results on my own. The cache numbers match quite well. Day 6.
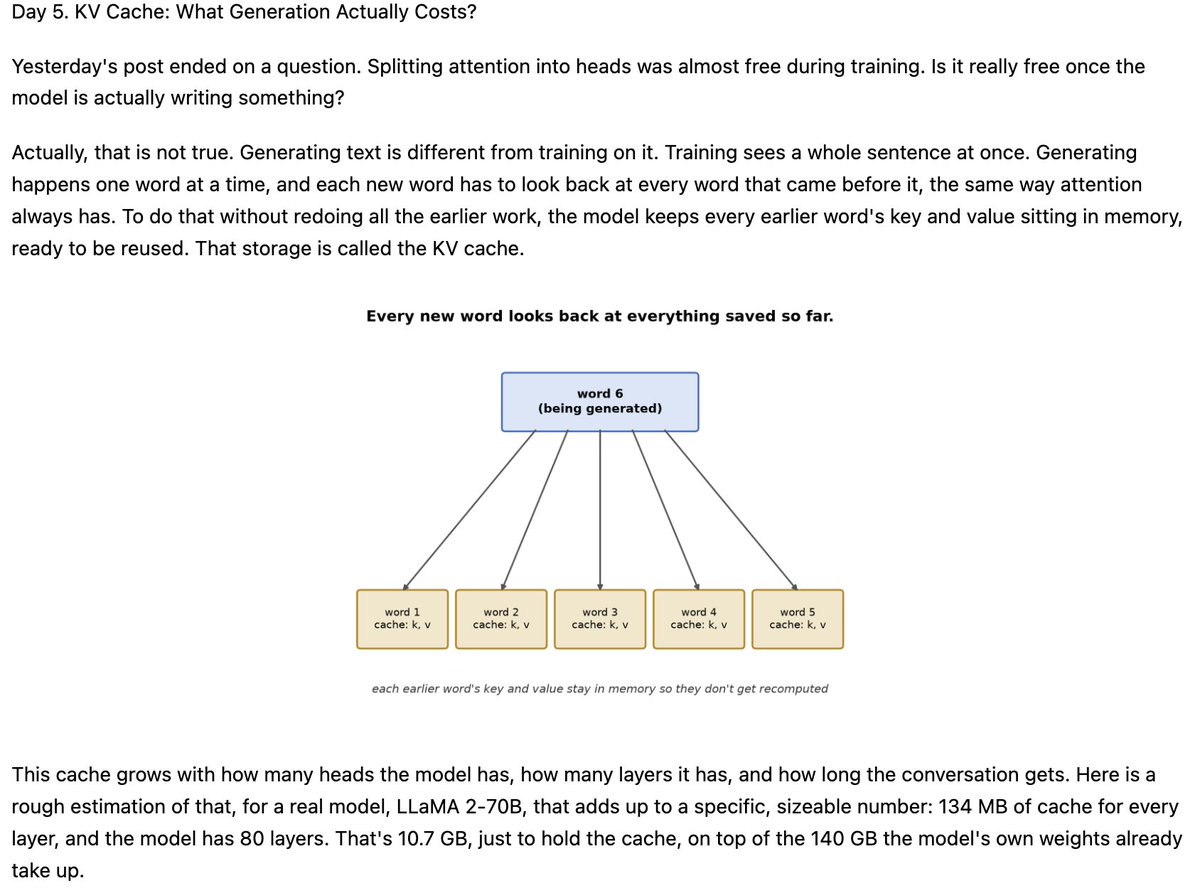
Day 4 ended with a question: generating text means holding on to every word already looked at. What does that memory cost, and why does it become the real bottleneck? For example, for LLaMA 2-70B, the number is 10.7 GB. Here is the breakdown of that on Day 5:
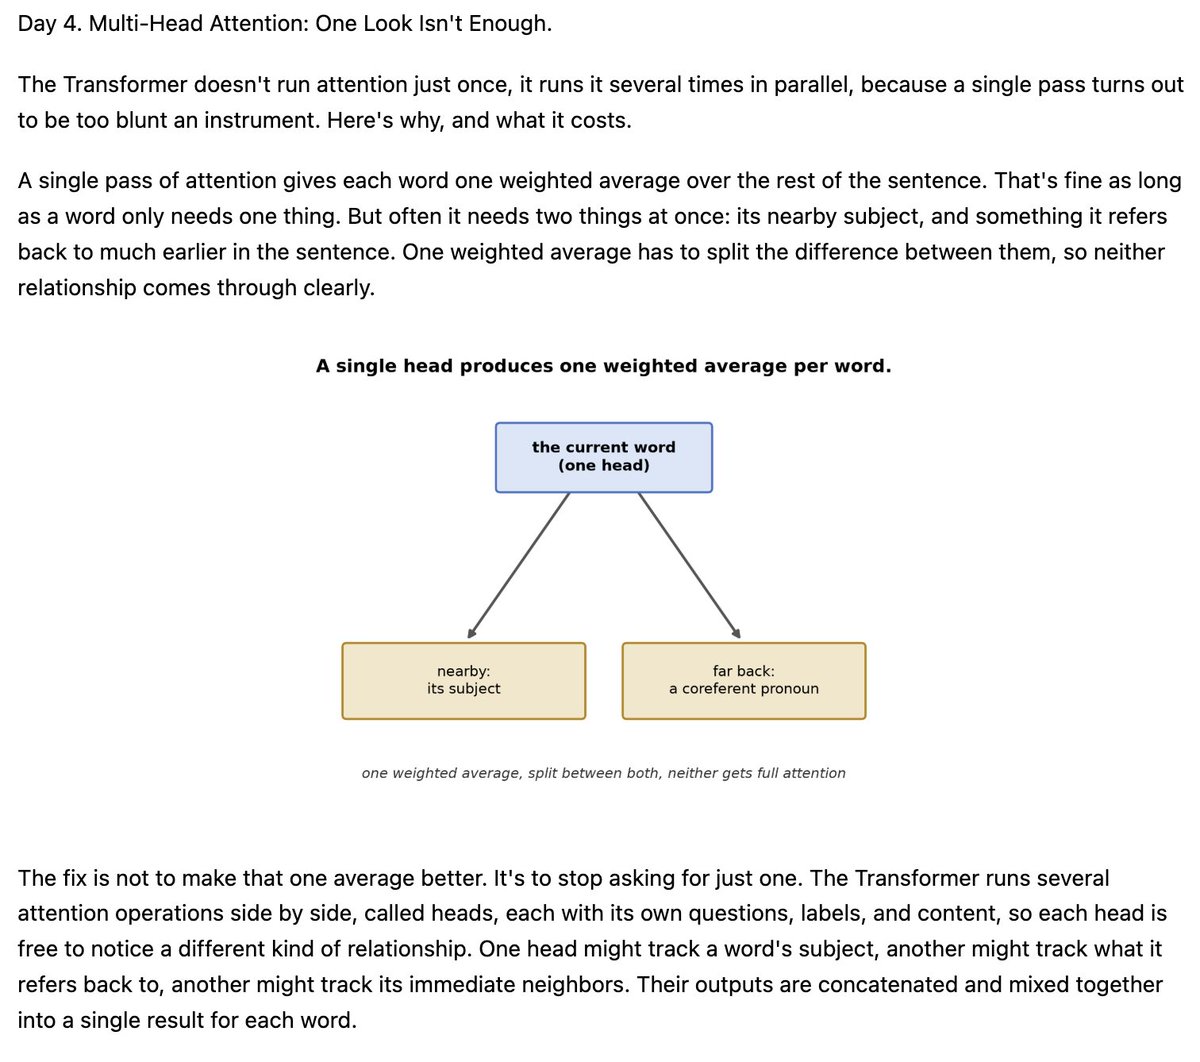
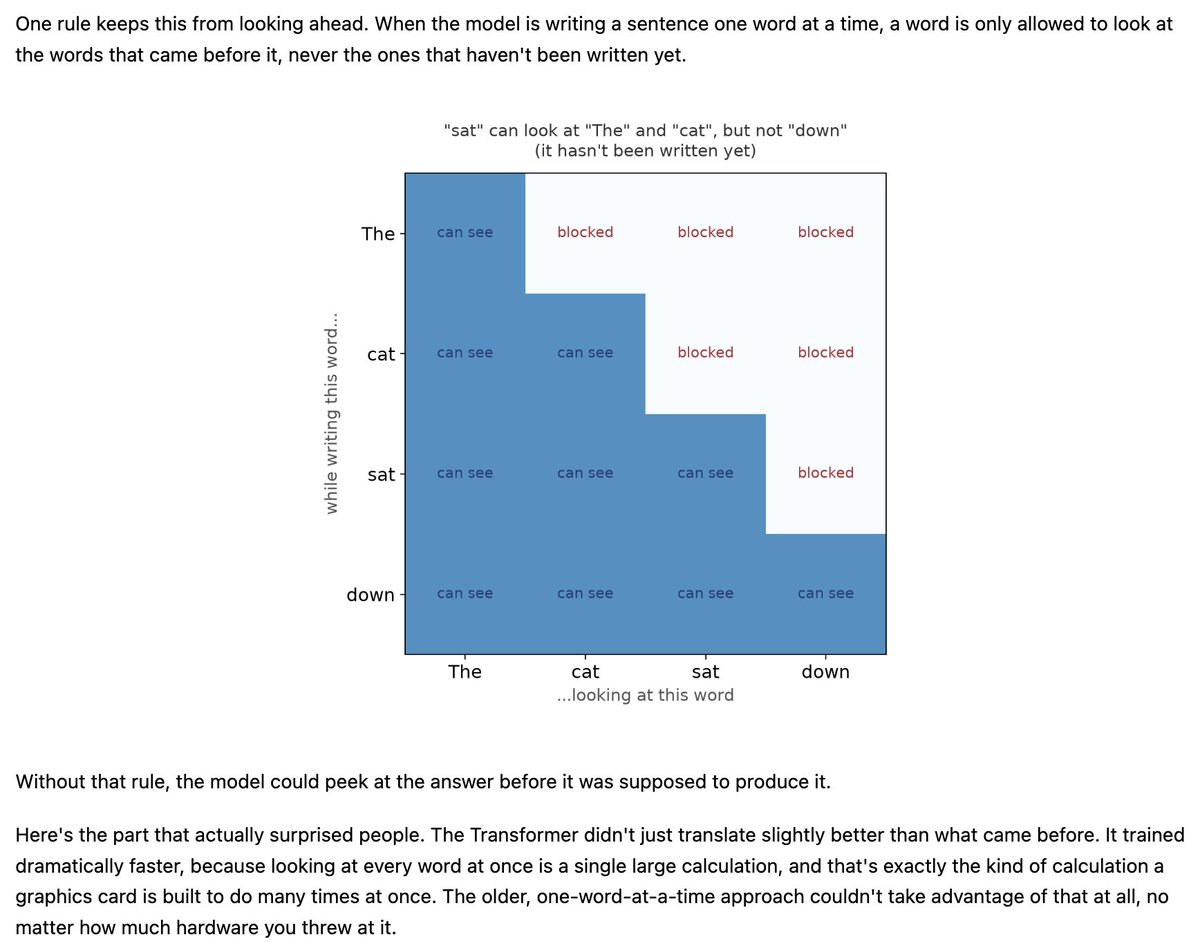
Day 3 ended with a question, what next after transformer & attention? A transformer doesn't run attention just once; it runs it several times in parallel. Why one pass isn't enough, and why running several costs almost nothing extra. Day 4.
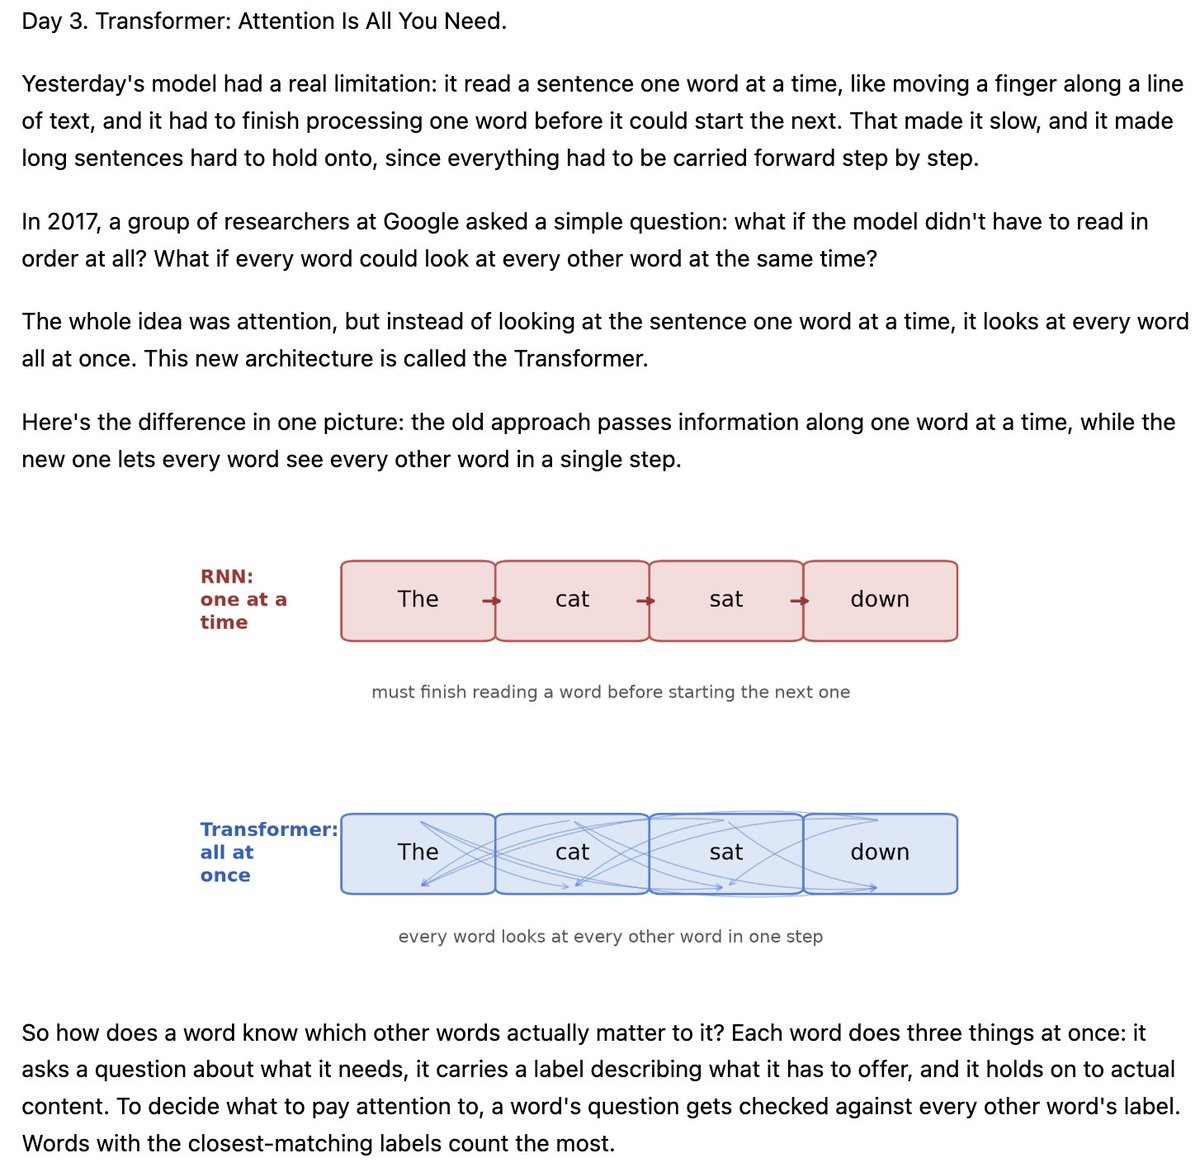
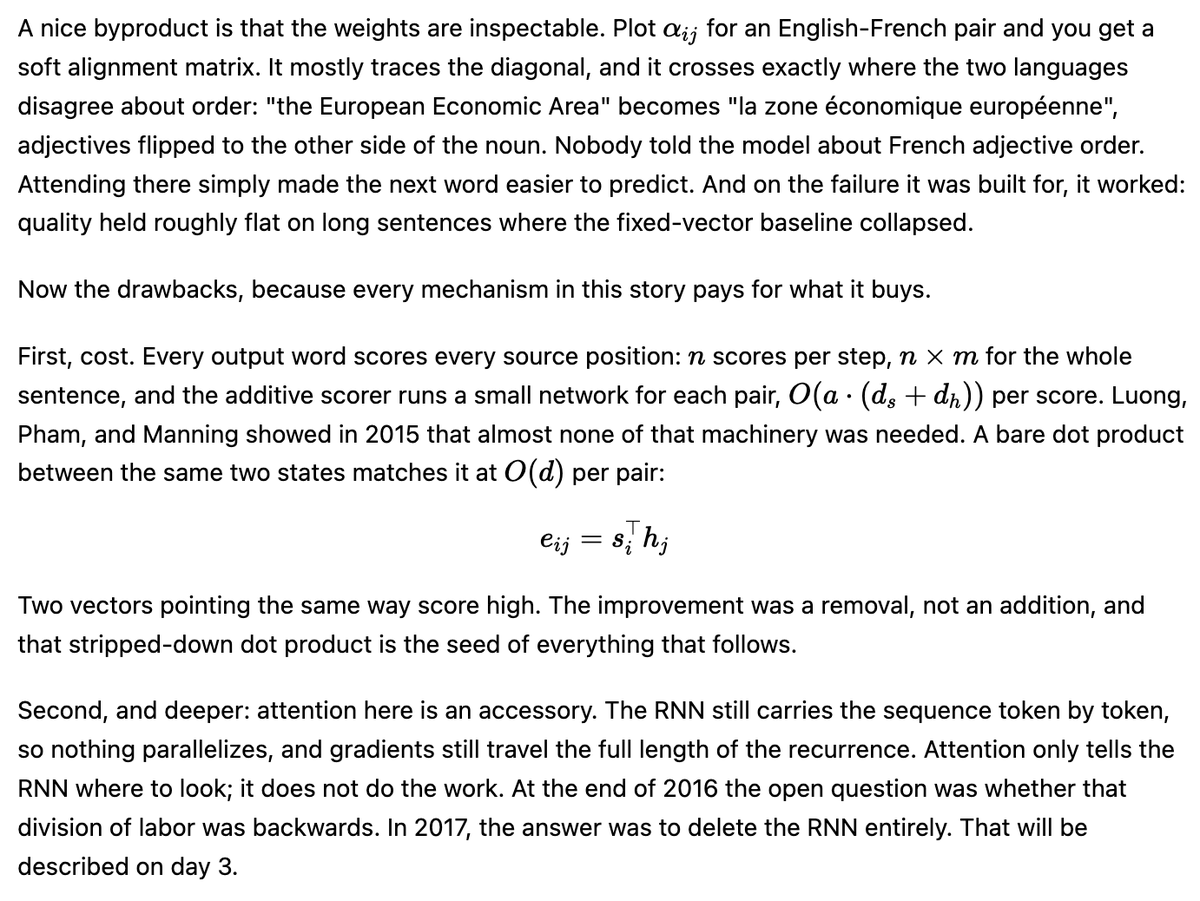
From where we left off on Day 2: an RNN reads one word at a time, so parallelization was the problem, and it struggled to remember the start of a long sentence. In 2017, a new design let every word look at every other word at once instead. Day 3: how it actually works.
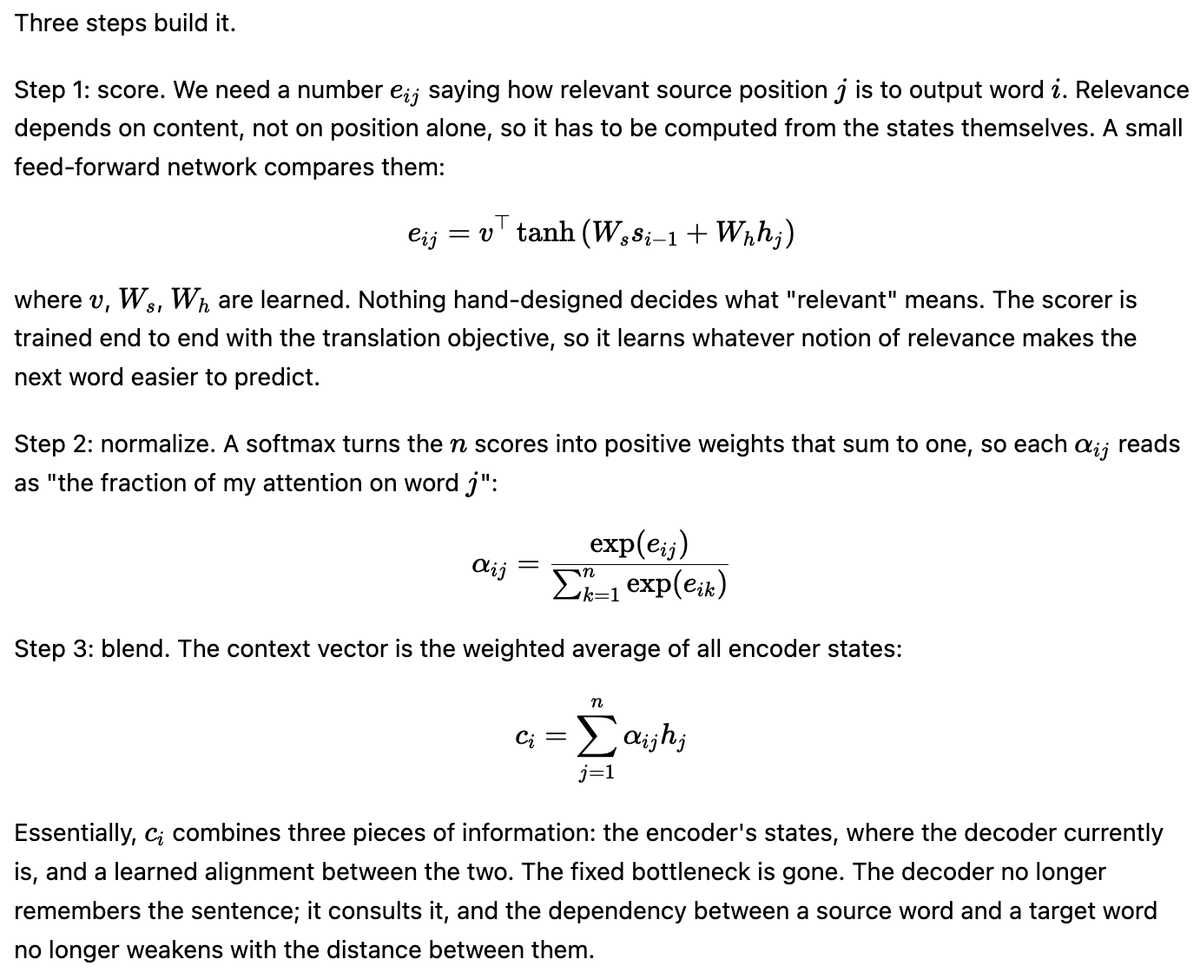
Day 2: Where we left off: sequence-to-sequence models squeezed a whole sentence into one fixed-size vector, and long sentences got forgotten. In 2014, Bahdanau, Cho, and Bengio fixed that bottleneck by letting the decoder look back at every encoder state instead. How it works:
New Things:
I spent several years doing physics research on active matter: polymers that propel themselves, systems that never reach equilibrium. Months ago I started learning language models.
Physics leaves you with one habit. You don't get to use an equation you can't derive.
I'll share the journey here as I go. My purpose here is not to teach you, just to share the learning process. I'm learning in public, and writing it down is how I test whether I actually understand it.
@WestsideStores@Westside@jagograhakjago@DPIITGoI@PMOIndia I’ve submitted all required details—photos, invoice, product names—three times. Months later, support is still asking for the same info. First they said the order was cancelled, then they claimed it was delivered. Please check the valid Order ID: 2023007 and process my refund.