We’ve been experiencing a few caching issues when using OpenAI Responses → Anthropic Messages.
These issues will be fixed in v0.4.4, which is expected to be released at 4:30 PM UTC+2.
Requests to Claude from Chat Completions and Responses apps like Codex now use prompt caching. The tool list, system prompt and conversation are cached, so repeated turns cost less input.
Shipped Kaeso v0.4.2
Organizations can now add their own custom providers (self-hosted vLLM, Ollama, internal proxies, etc.) on any API format Kaeso speaks. API keys rotate in one step (old key stays valid for a grace period you choose), hard budgets refuse even single over-limit requests, finished streams are logged as successes, and Codex / ChatGPT desktop can use Claude, Grok and Mistral models.
Also adds request overhead timing, a new bench tool, and lots of docs + UI polish.
Full notes: https://t.co/4li8YCAGGY
or https://t.co/UUlzhw9cTF
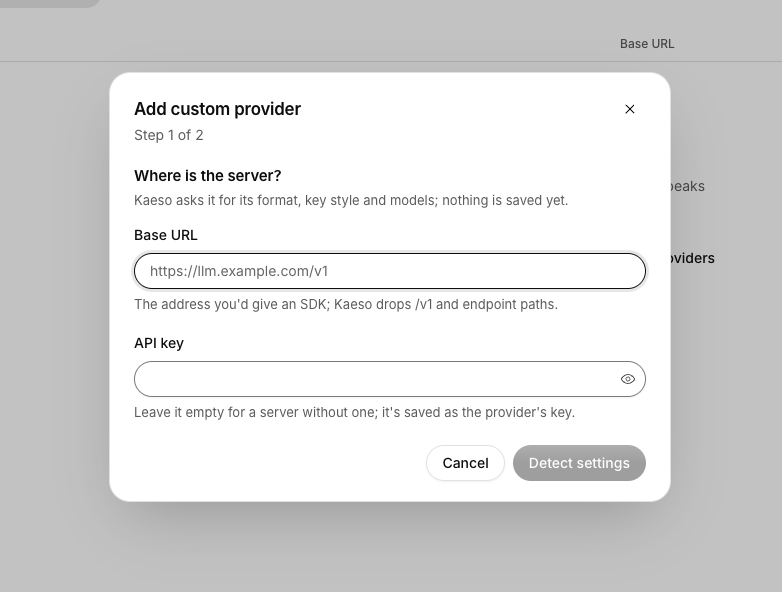
Adding a custom provider is now a two-step flow.
Paste the base URL you'd give an SDK and an optional API key. Kaeso asks the server for its format, key style and models, and nothing is saved until you confirm.
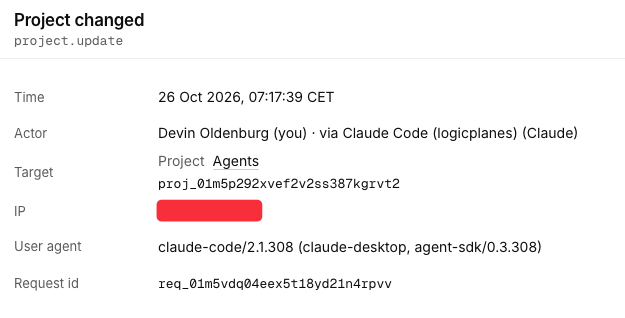
You can view your Agents’ activity, edit their permissions, or revoke their access at any time.
In every audit log, actions taken by Agents are clearly marked as such.