TSMC ($TSM) Q3 Earnings
Revenue: US$46.72B
Gross Margin: 66.4%
Operating Margin: 58.7%
Net Income: NT$763.1B, up 69% YoY
Q4 Revenue Guidance: US$52.3–54.3B
AI-related chip demand continues to drive growth, with TSMC’s Q3 revenue exceeding its previous guidance range.
The company’s Q4 revenue outlook points to continued strong growth.
Explore more earnings data and upcoming releases in RWAPerp → Markets → Earnings Calendar.
watching a member name update on the live site wall in real time:
→ Website Builder edits pages straight from project chat
→ Teamily AI keeps the dynamic site synced automatically
→ you review before and after live on screen
this is how team sites should be updated.
We built Oki Home because we felt the old promise of the personal computer slipping in the new age of nearly boundless intelligence.
Existing products increasingly optimize for maximal data collection and analysis while offering limited compute. We do the opposite: limitless, personalized intelligence while preserving your data sovereignty, and keeping what is yours, yours.
this is exactly the part of AI workflows nobody talks about 😄 the models keep getting better but somehow the copying, uploading and tab switching keeps getting worse. curious to try this with a real client brief.
Nano Banana / GPT Image / Qwen Image at 30% OFF for a limited time? yeah, that’s a pretty good excuse to test it on a real brief.
Atria ASI shows Atria Dawn Preview organizing scattered documents, spreadsheets and meeting notes into structured deliverables. Does anyone trust an AI-built deck enough to present it unedited? https://t.co/KRjWra8Doh
Great builders build.
Memes, utility, governance, product tokens. we back all of it.
shipping + growing + traction = we reach out to u. dont need to ask.
grateful for every team on @o1_exchange. always here for yall.
This is how we support teams launching on @o1_exchange o1 Launchpad https://t.co/jv67JzrLK0: https://t.co/8vzNyLXyuZ
Rapport is earned not asked for.
Remember. Sky is the limit.
1/9 A model can master every individual skill—and still fail a long-horizon task when it needs to switch between them.
Introducing "Toward Skill-Native LLMs: Skill Entropy for Benchmarking and Training Long-Horizon Reasoning", a unified framework for measuring, diagnosing, and training cross-skill long-horizon reasoning.
We introduce:
① 𝗦𝗸𝗶𝗹𝗹 𝗘𝗻𝘁𝗿𝗼𝗽𝘆—a directional measure of how difficult it is to switch from one reasoning skill to another.
② 𝗦𝗸𝗶𝗹𝗹²-𝗕𝗲𝗻𝗰𝗵—cross-skill long-horizon tasks covering 558 fine-grained skills across 9 verifiable and open-ended domains.
③ 𝗦𝗸𝗶𝗹𝗹-𝗘𝗻𝘁𝗿𝗼𝗽𝘆 𝗥𝗟—which turns skill-switching difficulty from an evaluation metric into a reinforcement learning signal.
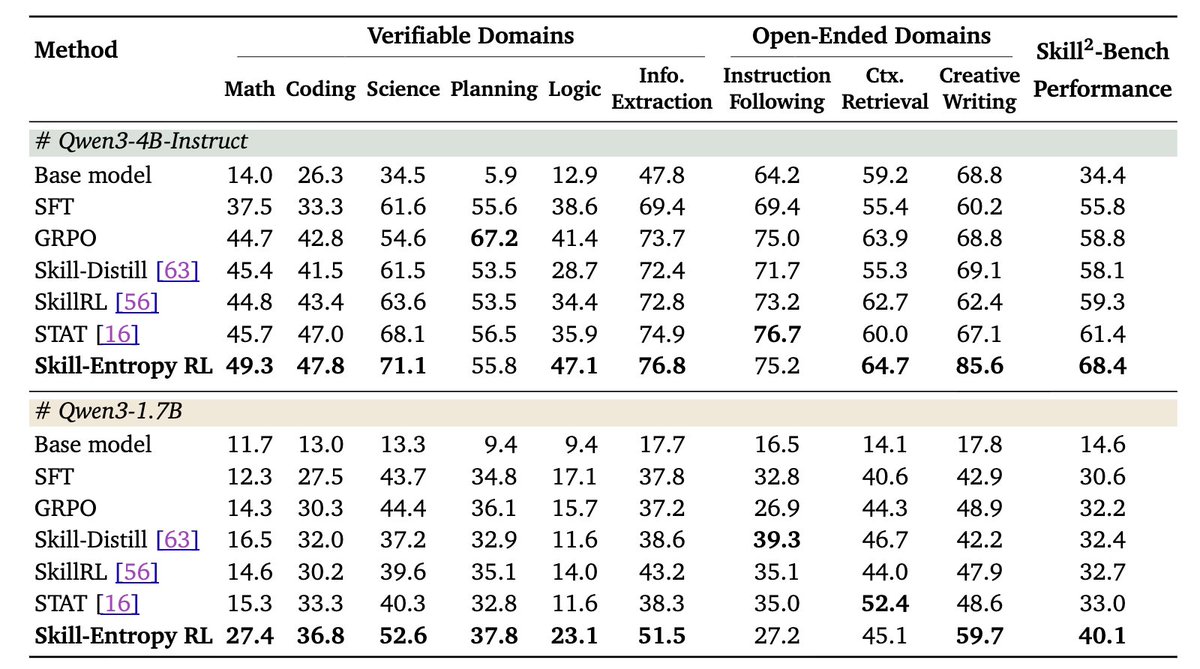
Across 8 frontier and 4 open-source models, performance broadly decreases as task-level Skill Entropy rises. We identify a concrete failure mode: later reasoning steps are often dominated by the skill and answer format used in previous steps.
Skill-Entropy RL substantially closes this gap:
• Qwen3-4B-Instruct: 𝟯𝟰.𝟰 → 𝟲𝟴.𝟰
• Qwen3-1.7B: 𝟭𝟰.𝟲 → 𝟰𝟬.𝟭
The gains transfer to unseen open-ended domains and can be obtained on off-the-shelf training data such as OpenR1-Math.
Toward LLMs that do not merely possess skills, but can identify, sequence, and switch them reliably across long trajectories.
📄 Paper: https://t.co/gi3UQmECpo
💻 Code & Data: https://t.co/Z7Bbls4Opp
got a haircut and the stylist asked if I was still in high school.
when you’re young that’s not a compliment. give it 10 years and I’ll be tipping extra for it.