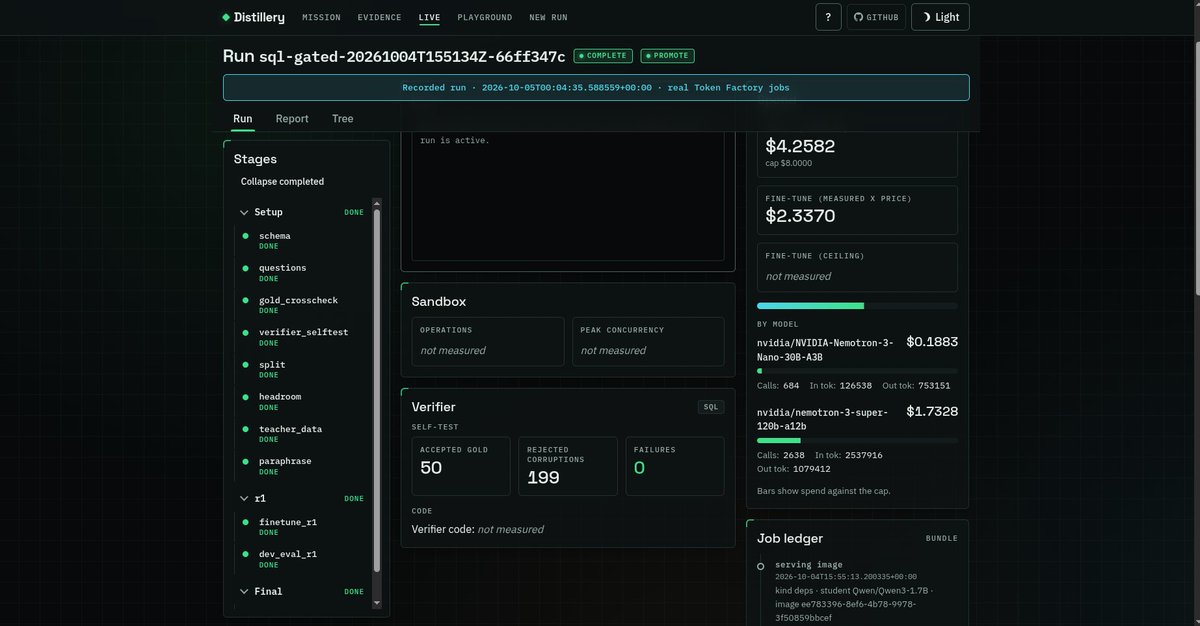
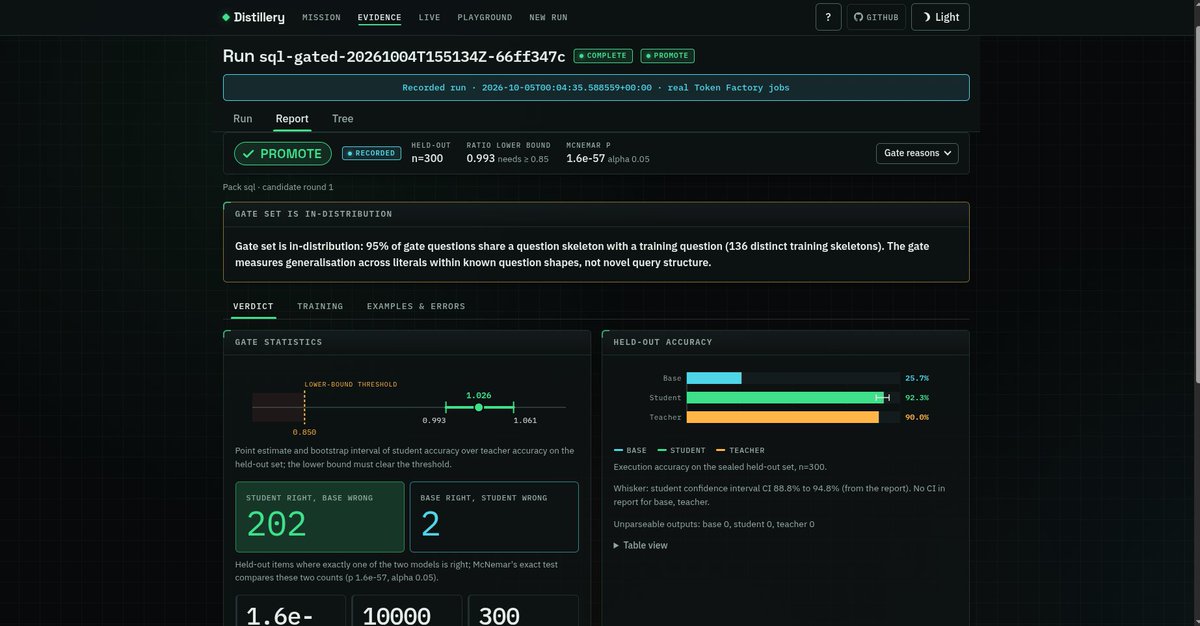
results are in. the gate said promote.
the full run:
teacher data → fine-tune → sealed held-out (300) + ood stress set (100) → gate.
held-out,
300 questions: → base qwen3-1.7b: 77/300 (25.7%) → student: 277/300 (92.3%) → teacher: 270/300 (90.0%)
the gate: → student/teacher ratio: 1.026 → 95% lower bound: 0.993 (needed ≥ 0.85) → mcnemar vs base: 202 student-only wins, 2 base-only, p ≈ 1e-57
so the 1.7b student matched the 120b teacher on this task. but the ood stress test tells a different story: → base: 9% → student: 16% → teacher: 99%
the student learned the training distribution, not sql in general. 94.7% of the held-out questions share a query shape with training, so i'm calling the 92% result in-distribution.
the kill test also passed: the harness killed the worker mid fine-tune, resume adopted the running job, and the job finished with 1 job id and 1 bill.
1,488 steps. 5.84m trained tokens.
total cost: $4.26 fine-tune: $2.34
next: zero-babysitting runs, retries + supervisor + chaos testing, a fairer teacher comparison, and a second task beyond sql: tool calling.
#buildinpublic @nebiustf x @nvidia hackathon.
this weekend distillery started proving in numbers
my first students didn't learn, and the logs said "success."
the fine-tune jobs succeeded and the loss went down a little. but the provider defaults (lr 1e-5, batch 8, packing on) meant ~1,000-token rows got packed together, so 117 rows became 6 optimizer steps.
that's a near-untrained adapter that still reporting "succeeded". now the pipeline refuses any run planned for fewer than 300 steps.
:: overfit test first, before spending real money ::
64 training rows, 320 steps. then i scored the student on those same rows in the sandbox:
-> fine-tuned student 64/64 (100%) vs base model 17/64 (27%)
just proof the training → serving pipeline actually works end to end.
-> a pre-registered pilot to pick the learning rate.
-> two arms, with the decision rule written down before any results existed. on 150 held-back dev questions:
base qwen3-1.7b: 33/150 (22%)
A -> student @ lr 1e-4: 142/150 (94.7%)
B -> student @ lr 2e-4: 141/150 (94.0%)
caveat: the dev questions come from the same templates as training (in-distribution), and the pilot trained on gold sql. the real test is the sealed held-out set. the gate is calibrated, not hoped for.
promote only if :
- the 95% lower bound of student/teacher accuracy is ≥ 0.85,
- the student wins more questions than base,
- mcnemar p < 0.05.
i simulated it with 10k bootstrap resamples per evaluation: at n=300, a student at 95% of the teacher passes 100% of the time, and one at 85% passes only 5%. so it's strict, but not impossible.
real costs, reconciled to the cent.
fine-tuning on token factory works out to $0.40 per 1m trained tokens.
the overfit run: 615,460 tokens → $0.25, matching the console exactly. sandboxes currently doesn't charge (beta mode)
bugs that only a real run could find:
generation jobs for the 1.7b model needed up to 220s, but my timeout was sized for a 0.6b model. greedy decoding makes the same batch slow every time, so retries could never succeed. fix: retry with a doubled timeout.
if the worker got killed mid-fine-tune, the resume cancelled the running job and paid for a new one. it now adopts the job instead, so there's no double charge.
my cost re-pricer silently left out fine-tune charges on old runs. it now refuses to print a total it can't fully back.
right now: the full end-to-end run is live, started from the web ui, not the cli.
teacher data → fine-tune → sealed held-out (300) + out-of-distribution stress set (100) → gate.
mid fine-tune, the test harness kills the worker on purpose to prove the run resumes and adopts the job without paying twice. it's all being screen-recorded.
whether it comes out promote or reject, that's the result.
results dropping tomorrow.
@claudiamiclea we r building distillery autonomous stack that can distill parent model niche expertise into student model and it win the evals.
Let's connect
results are in. the gate said promote.
the full run:
teacher data → fine-tune → sealed held-out (300) + ood stress set (100) → gate.
held-out,
300 questions: → base qwen3-1.7b: 77/300 (25.7%) → student: 277/300 (92.3%) → teacher: 270/300 (90.0%)
the gate: → student/teacher ratio: 1.026 → 95% lower bound: 0.993 (needed ≥ 0.85) → mcnemar vs base: 202 student-only wins, 2 base-only, p ≈ 1e-57
so the 1.7b student matched the 120b teacher on this task. but the ood stress test tells a different story: → base: 9% → student: 16% → teacher: 99%
the student learned the training distribution, not sql in general. 94.7% of the held-out questions share a query shape with training, so i'm calling the 92% result in-distribution.
the kill test also passed: the harness killed the worker mid fine-tune, resume adopted the running job, and the job finished with 1 job id and 1 bill.
1,488 steps. 5.84m trained tokens.
total cost: $4.26 fine-tune: $2.34
next: zero-babysitting runs, retries + supervisor + chaos testing, a fairer teacher comparison, and a second task beyond sql: tool calling.
#buildinpublic @nebiustf x @nvidia hackathon.