Every AI summary needs its receipts.
Accounts won't pay an expense without the receipt. AI claims deserve the same rule.
I built Verbatim: every theme it finds carries the exact quotes behind it, one click away.
No receipt, no claim.
#BuildInPublic#AI
@Joshua_WD Not on live notes, and that's on purpose: synthetic patients only. It's a harness to find where checkers break before anyone trusts one on real notes.
A fentanyl patch's "72 hour" became a heart rate of 72 in my rules checker.
I built fhir-notecheck: it checks AI-written clinical notes against the FHIR record. On 240 planted errors, the LLM checker caught 239 with zero false flags. Rules: 90%.
#BuildInPublic#HealthTech
@aladdin_devino An insulin dose. The record says "insulin isophane, human"; the LLM wrote just "insulin isophane", so the matcher found no matching drug and never compared the wrong dose. I left it unpatched so the matcher isn't tuned to the test set.
@PrathmeshPatel_ "Test across the boundary" holds outside MCP too. I check AI-written clinical notes, and a note can look perfect on its own. The errors only show up when you check it against the record it came from. Same lesson: eval against the environment, not the output alone.
@Sergey_Rura Building AI for clinical notes here. Just open-sourced a checker that compares AI-written notes against the patient record and scores itself on 240 planted errors, false flags included. "Confidently ship stuff nobody asked for" is exactly what it's for. Happy to connect.
Your AI model is rented.
A provider retired the model behind one of my parsers with ~6 weeks' notice. I moved it and made the model a setting, so the next move is one line.
Config, not code. A tested fallback. Rehearse the move.
#BuildInPublic#AI
@ganesh2412 None by default, in my experience. You only get it if you ask for it every time. And even then it’s the agent grading its own work, so I trust the pasted test output over “I tested it”. As a QA, what’s the one thing you’d require in that report?
Every AI summary needs its receipts.
Accounts won't pay an expense without the receipt. AI claims deserve the same rule.
I built Verbatim: every theme it finds carries the exact quotes behind it, one click away.
No receipt, no claim.
#BuildInPublic#AI
@RatOrthodox Showing the exact article and passage under every answer would make this a lot safer, especially for the medical guides. Offline, you can't google to double-check, so the source on screen is the only way to catch a wrong answer before you act on it.
@gnosis_entheos Tying each note to the exact lines it's explaining is what makes it trustworthy. You can check the explanation against the code right there. Nice touch on staying quiet when there's nothing new.
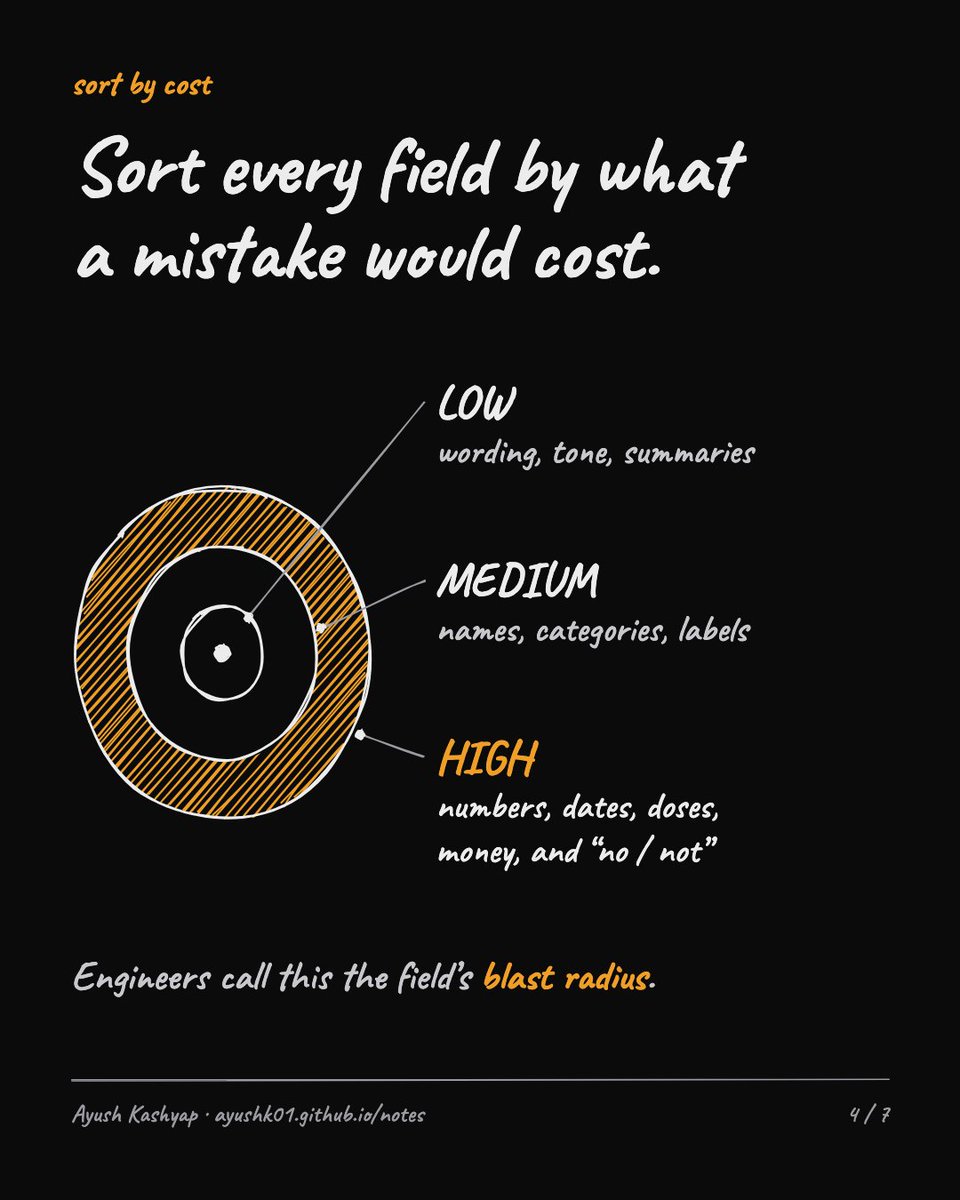
Not all AI mistakes are equal.
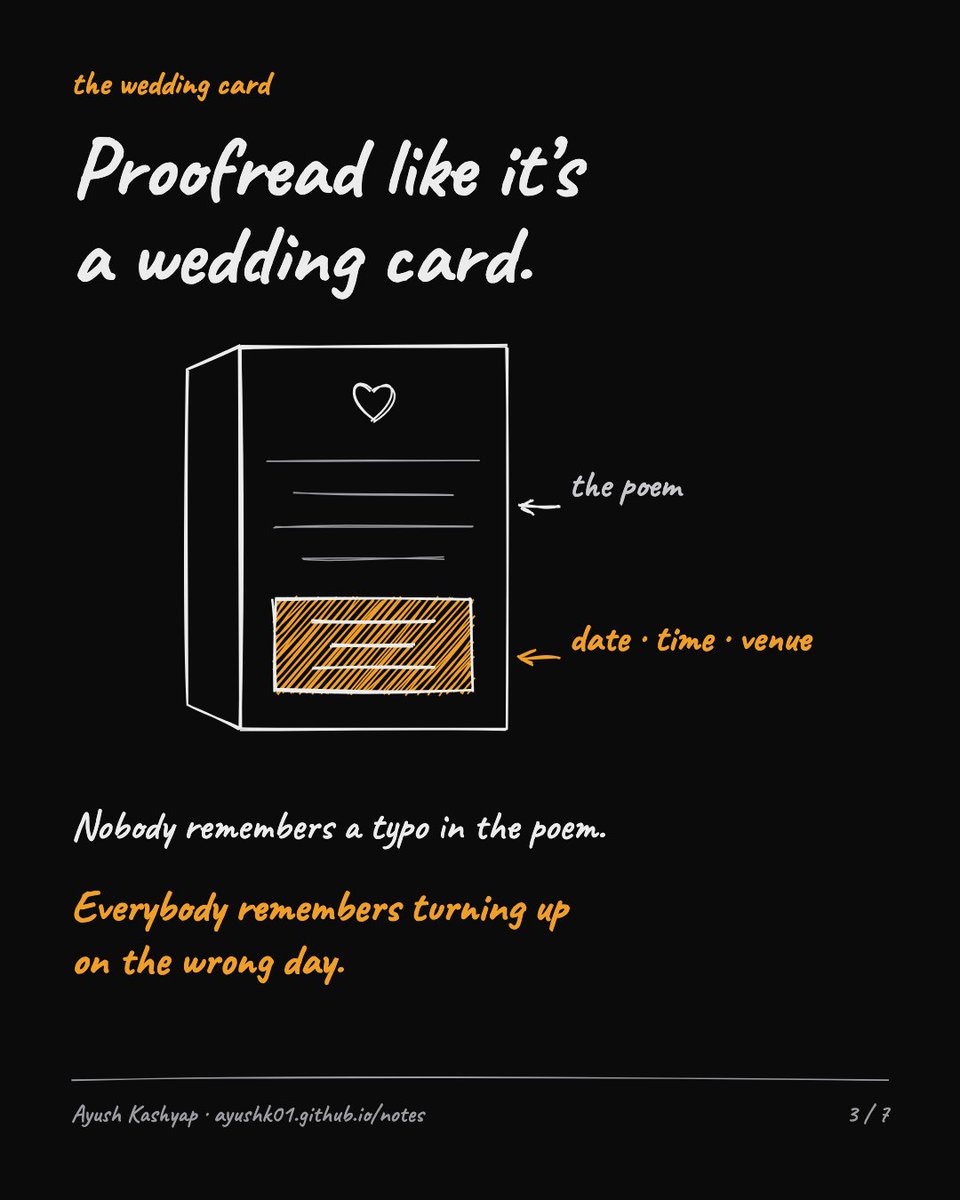
A typo in a wedding card's poem: nobody notices.
A wrong date: every guest shows up on the wrong day.
"95% accurate" hides the real question: which 5%?
Check the date twice. The poem once.
#BuildInPublic#AI
The sneakiest one: "No history of diabetes" vs "History of diabetes". One word, opposite meaning, and both read perfectly. That's why small words like "no" count as high-risk.
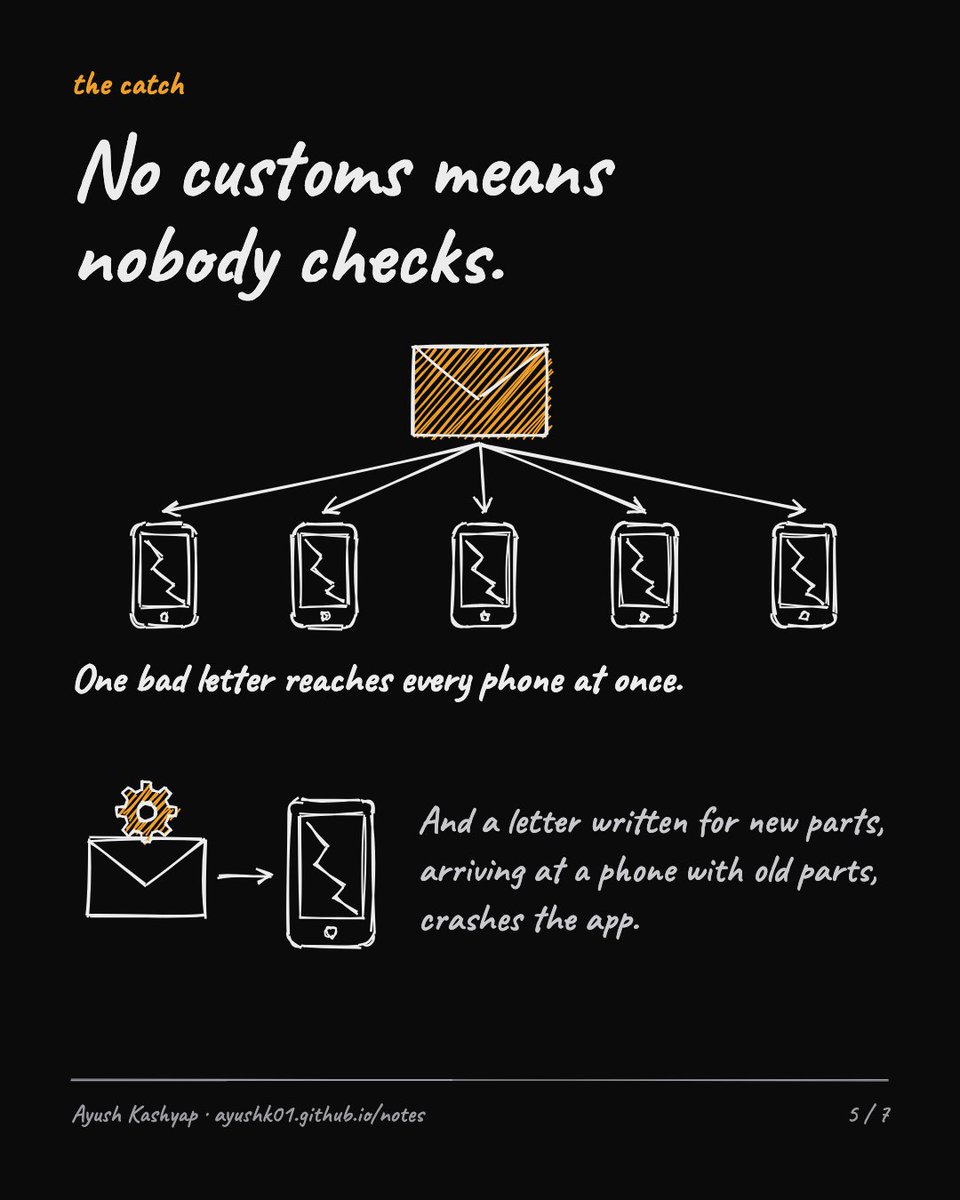
@BestAppAwards Exactly, that's the version-matching rule. Every letter is addressed to a specific build. Phones still on an older build either get a letter written for them or keep the old screen until they update. Mix those up and an over-the-air fix becomes a crash.
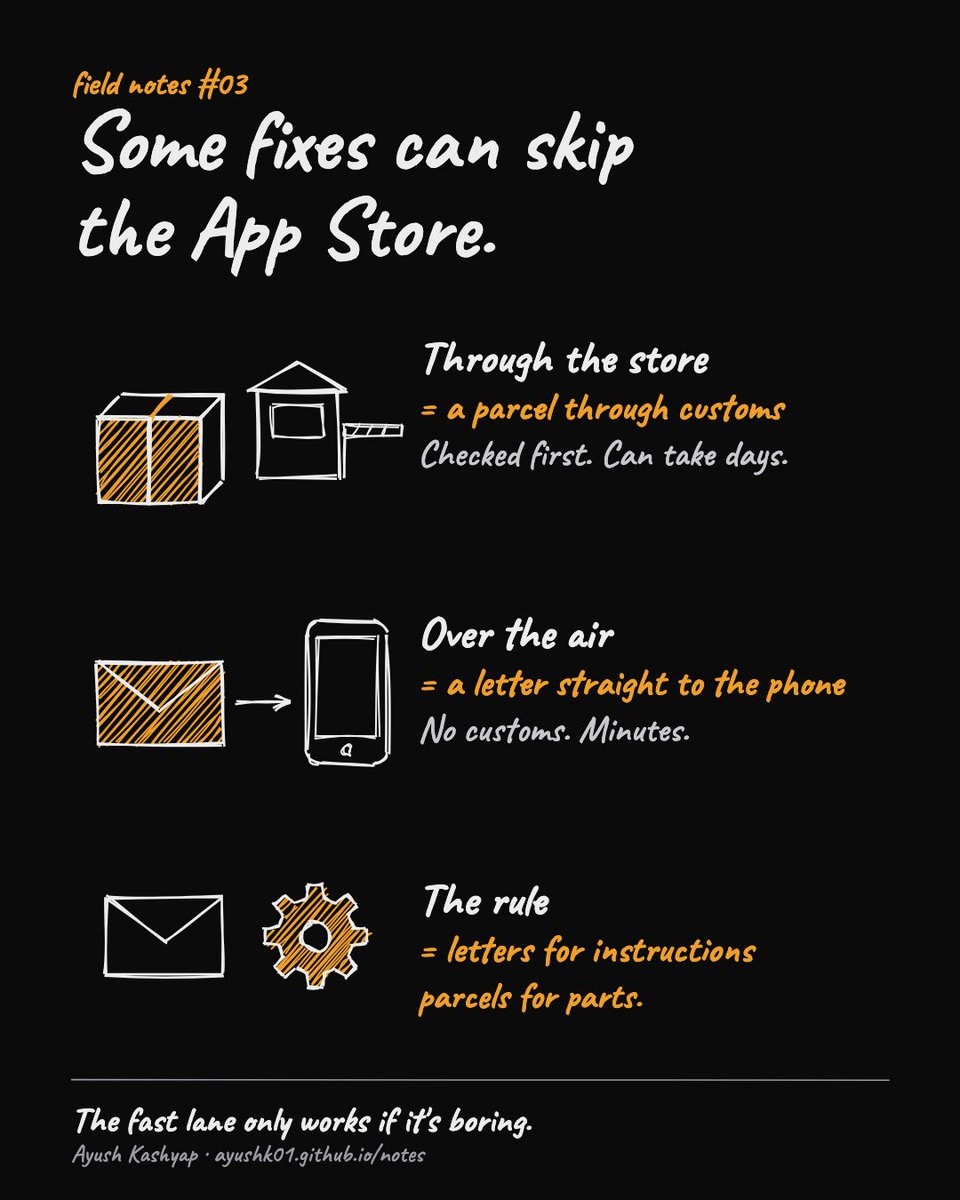
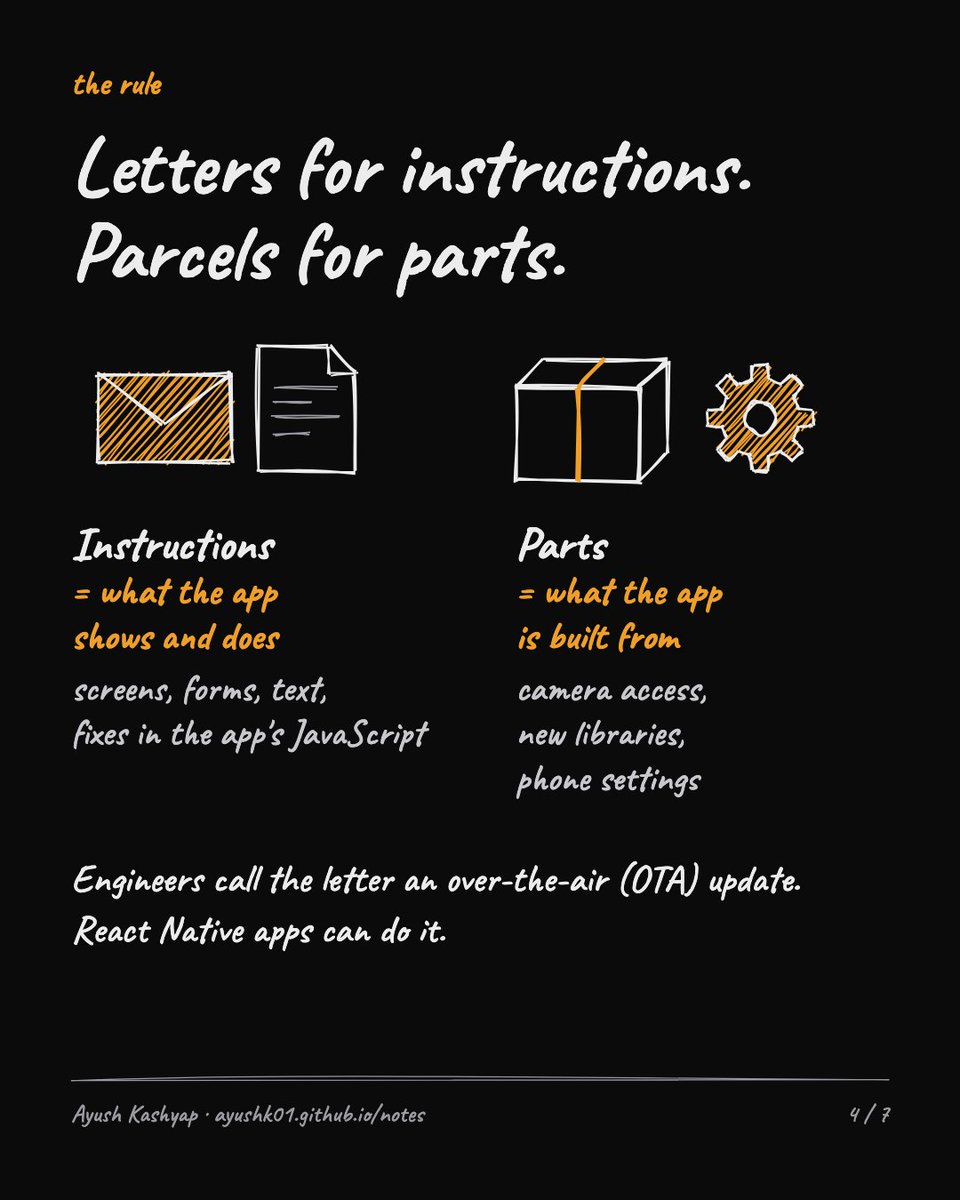
Some fixes can skip the App Store.
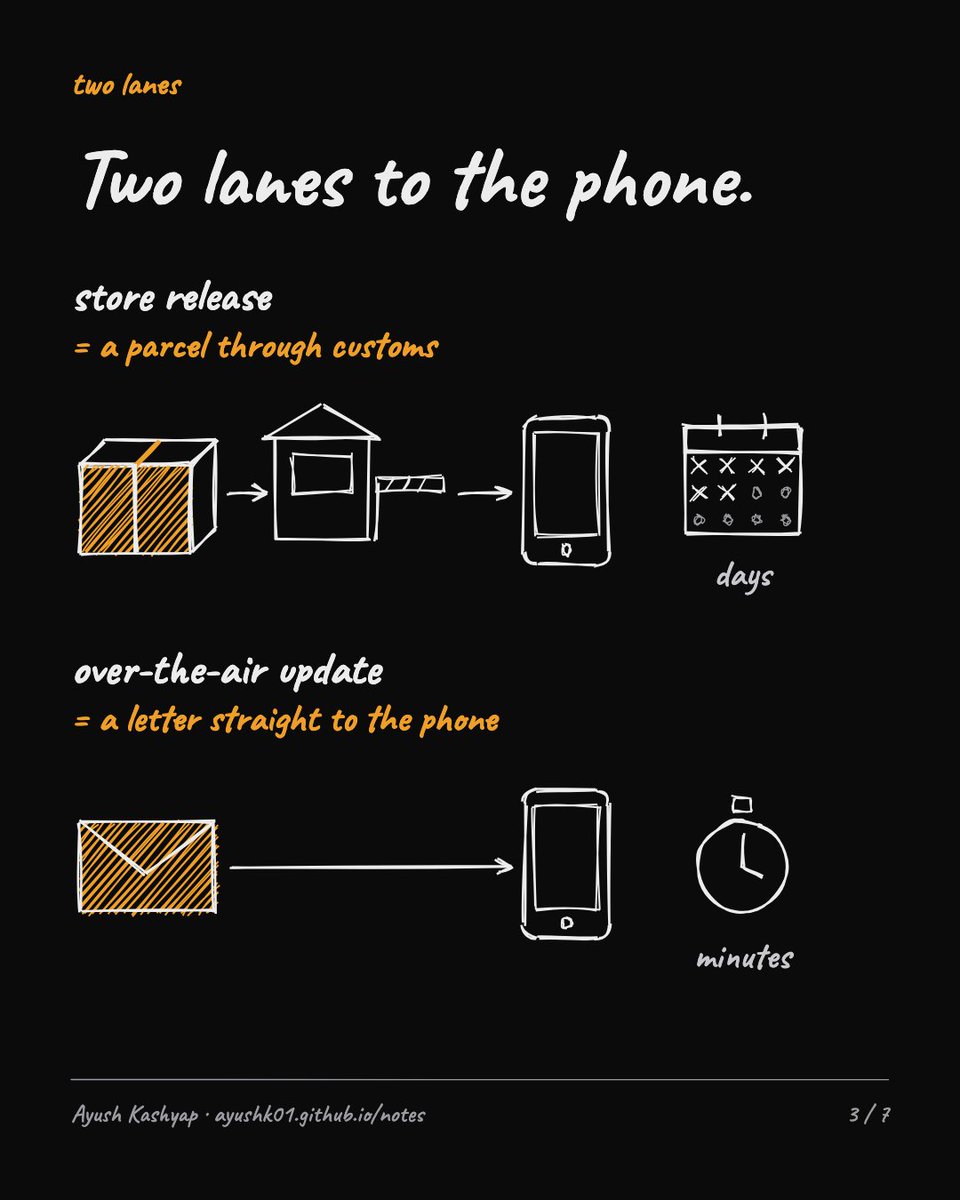
📦 Store release = a parcel through customs. Takes days.
✉️ Over-the-air update = a letter straight to the phone. Minutes.
Letters for instructions, parcels for parts. Skip customs, and you have to be your own.
#BuildInPublic#ReactNative
@DevMuheet Agreed, and the order matters. Let the evals catch the obvious failures, so the human's attention goes to the ones that matter. Where a mistake can hurt someone, the eval narrows what I read. It doesn't replace my signature.
@dKOPjzgJGU50253 Nice idea. Pointers usually only click once people can see them. Does it show what happens on a use-after-free, or only valid accesses?