Excited to introduce ERNIE 5.5 Flash Base, my first release since joining @Baidu_Inc !
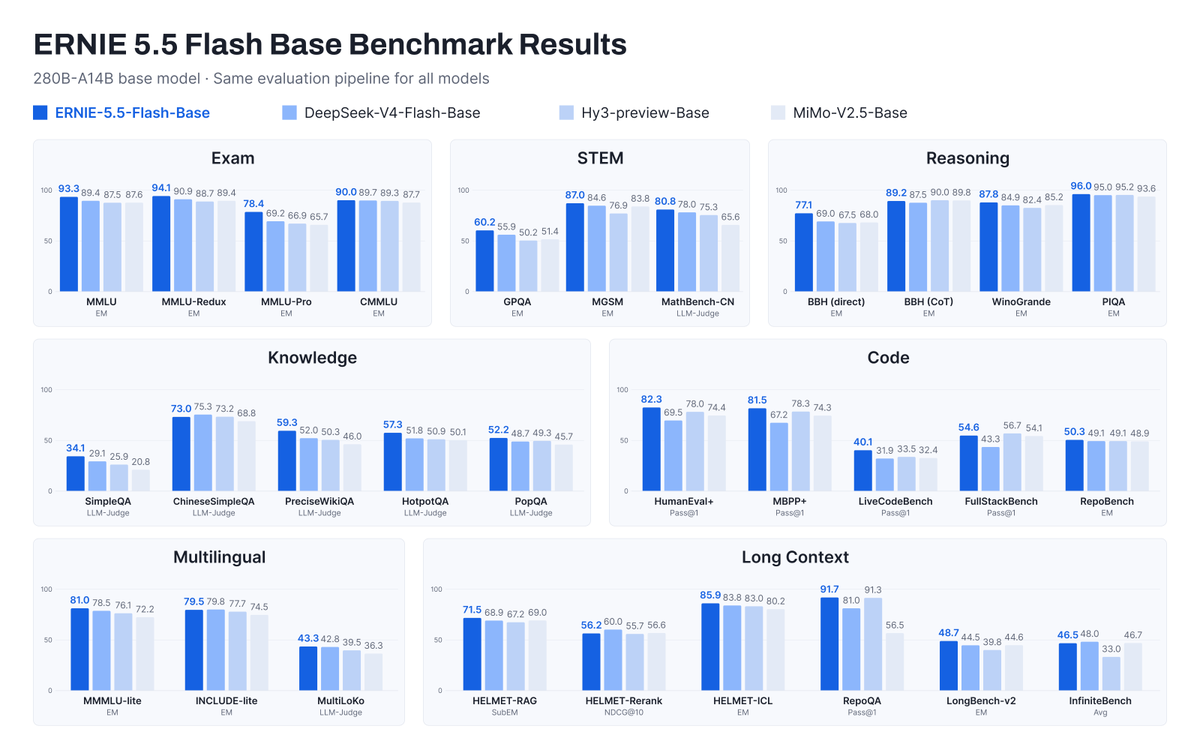
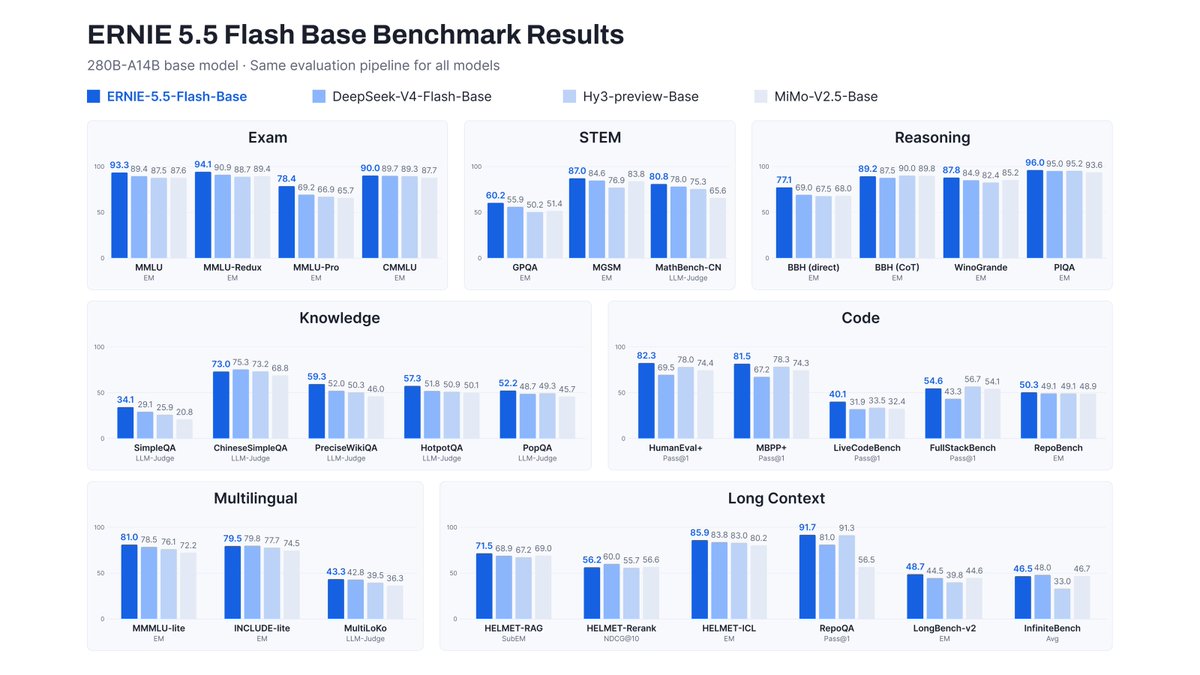
An open-sourced 280B MoE model with just 14B active parameters, pretrained on 33.5T tokens. It delivers strong performance across reasoning, coding, and long-context benchmarks, with support for up to 1M context.
Huge respect and thanks to the incredible team behind this — outstanding work!
Post-training is already underway, and I can't wait to bring it to you soon.
And this is just the beginning — more exciting technical developments are on the way. Stay tuned!
https://t.co/7DBNYNwf81
FP8 and BF16 weights are on Hugging Face under the ERNIE 5.5 Flash Base Model License Agreement v1.0.
Model: https://t.co/OuIfXW5sYy
Blog: https://t.co/2Bn4pgGFhP
Introducing ERNIE-5.5-Flash-Base, the pre-trained base of ERNIE 5.5 Flash before any mid- or post-training. The post-trained ERNIE 5.5 Flash is coming soon.
• 280B total / 14B activated MoE
• 33.5T pre-training tokens
• 128K training context, 1M for fine-tuning and inference
Evaluated on 24 short-context and 6 long-context benchmarks covering exam, knowledge, STEM, reasoning, multilingual, code and long context, against base models of similar size. Full results table on the model card.
Pre-trained from scratch on 33.5T tokens in FP8, emphasizing repository-scale code and long context. Built for this run: a distributed Muon optimizer that scales to thousands of GPUs, and FlashMask-4, an attention kernel for large head dimensions.
🚀 Baidu CoBuddy is now available on Novita AI.
A code-focused model built for developers, coding agents, and complex software engineering workflows.
CoBuddy brings:
• Long-context coding support
131K context window and up to 65K output tokens
• Agent-ready capabilities
Native tool calling and reasoning support for AI agent workflows
• Fast, production-ready inference
High-throughput, low-latency access through Novita’s serverless API
Excited to bring Baidu CoBuddy to developers on Novita.
@ErnieforDevs @PaddlePaddle
🚀PaddleOCR-VL 1.6 Officially Released!
We are thrilled to announce the official release of PaddleOCR-VL 1.6 — this version has set a new SOTA record of 96.33% on OmniDocBench, outperforming both open-source and proprietary solutions in text, formula, and table recognition.
📊 Key Highlights:
🔸 Ranked #1 on OmniDocBench v1.5 and Real5-OmniDocBench as well
🔸 Significant improvements in table, classic text, and rare character recognition
🔸 Enhanced seal, spotting, and chart recognition
🔸 Fully compatible with v1.5 architecture — zero migration, plug-and-play
From financial contracts and legal documents to research reports and historical archives — empower your document intelligence workflows by providing high-quality data to large language models (LLMs) and retrieval-augmented generation (RAG) systems.
✨ Industry-leading accuracy. Zero migration. Plug-and-play.
🔗 Read more: https://t.co/oNOfB6hbSY
#PaddlePaddle #PaddleOCR #AI #ComputerVision
Zack Williams brought one of the world's oldest writing systems to the ERNIE AI Developer Challenge: ancient cuneiform tablets.
Using PaddleOCR, he built NabuOCR to help read cuneiform from tablet images.
See the story behind @BoatbomberRBLX's winning project 👇
US vs China update. Stanford's AI Index put the US–China gap at 2.7%. Here's what two years of real-world use from the Text Arena shows.
Gap three years ago: +278. Today: +29.
@AnthropicAI's Claude Opus 4.6 Thinking vs. Baidu's
@ErnieforDevs Ernie 5.1 at the top.
The US has never lost #1, but the race keeps closing.
We're also launching the ERNIE Ambassadors Program! 🌍 We're looking for developers, creators, researchers, and community builders worldwide to help explore and build with ERNIE models together.
📩 Apply here: https://t.co/aU3qUDGmZt
ERNIE 5.1 is here 🚀
ERNIE 5.1 significantly reduces pretraining cost while compressing total parameters to ~1/3 and activated parameters to ~1/2 — using only ~6% of the pretraining cost compared to models at similar scale, while achieving leading performance in its class.
💡Key highlights:
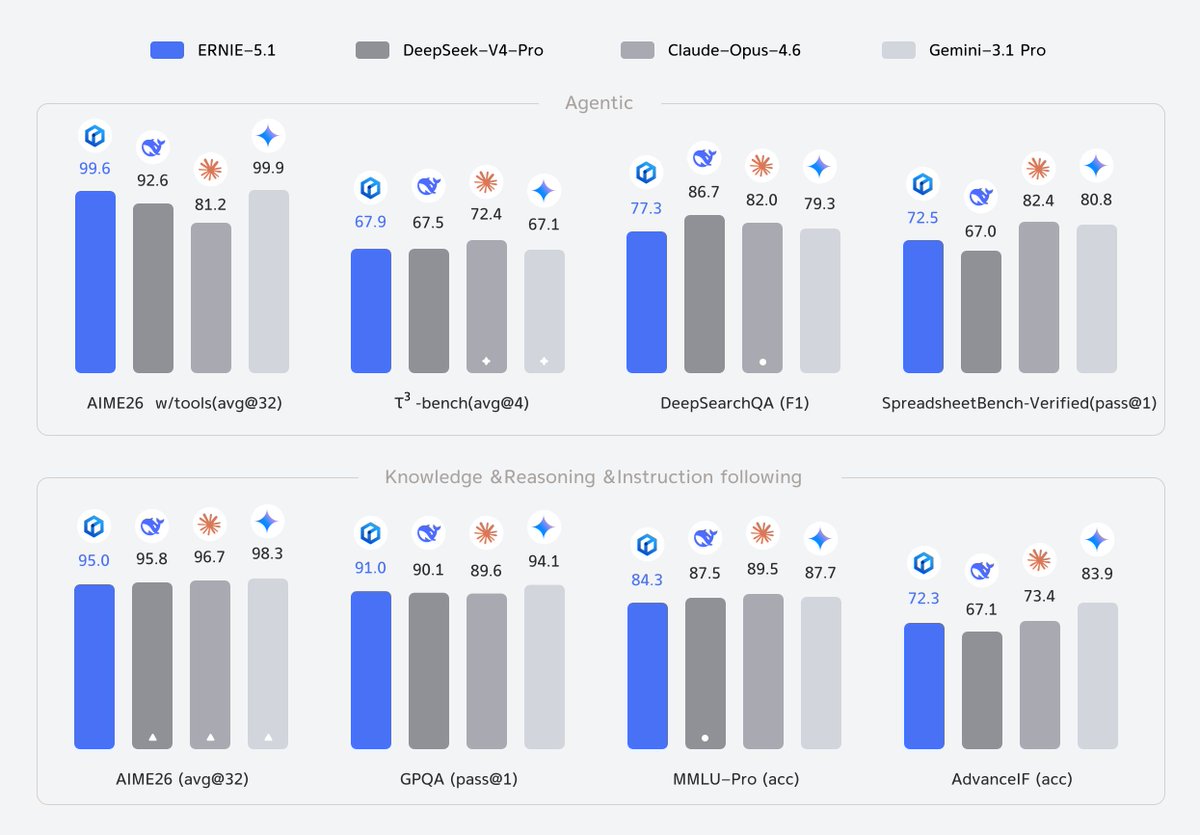
1/ Strong agentic performance approaching leading frontier models. ERNIE 5.1 surpasses DeepSeek-V4-Pro on both τ3-bench and SpreadsheetBench-Verified.
2/ Strong world knowledge and creative writing capabilities, with GPQA and MMLU-Pro performance approaching leading closed-source models, and creative writing ability nearing Gemini 3.1 Pro.
3/ Frontier-level reasoning performance. ERNIE 5.1 scores 99.6 on the challenging AIME26 benchmark with tools, second only to Gemini 3.1 Pro.
4/ Deep search capability. On May 9, ERNIE 5.1 ranked #4 globally and #1 among Chinese models on the Arena Search leaderboard with a score of 1223.
ERNIE 5.1 is now available on ERNIE and the Baidu AI Studio Model Playground:
👉https://t.co/qhd67Lg3B4
👉https://t.co/AaQSqDmVGU
👉https://t.co/uCNiypIu1q
@xerxes233@arena The API is currently in closed beta. You can join our Discord and apply for whitelist access to test it for free!https://t.co/LREVPWs9k5
Another update from @arena 👀
ERNIE 5.1 is now ranked #4 in Search Arena — making ERNIE one of the top-performing labs in Search and currently the only Chinese model in the Top 10.
Official release coming very soon 🚀
EERNIE 5.1 introduces several key technical innovations:
1/ Multi-Dimensional Elastic Pre-Training for dramatically improved parameter efficiency and lower training cost
2/ Decoupled Fully-Asynchronous RL Training for more scalable and stable long-horizon agentic RL
3/ Multi-stage RL pipeline centered on OPD for efficient capability fusion across domains
For full details on the architecture and training methodology, read the technical report:
https://t.co/21PfUvD9NI
Baidu Create 2026 is coming up fast, and the agenda is packed!
Beyond the main forum, our flagship developer conference returns with special forums on AI infrastructure, agent development, real-world applications, and more — plus plenty to explore on site.
Take a look 👇
Introducing ERNIE 5.1 Preview — now live! 🚀
Ranked #13 globally and #1 among Chinese labs on @arena 's Text Arena.
Top-10 worldwide across:
📐 Math — #9
⚖️ Legal & Government — #1
💼 Business, Management & Financial Ops — #4
💻 Software & IT Services — #7
Built on the strong pre-training foundation of ERNIE 5.0, ERNIE 5.1 Preview compresses total parameters to ~1/3 and activated parameters to ~1/2 of its predecessor, while using only ~6% of the pre-training cost of comparable models — delivering leading foundational performance at its scale.
Try it now 👉 https://t.co/jNwEbwrKps
More new models are on the way — stay tuned 👀