Introducing the Arena Alignment Index, our new benchmark measuring safety and alignment of AI agents in real-world use.
Built from 90K+ real-world agent sessions across 27 models, the index measures three critical signals:
- Unauthorized Action (UA): Taking actions beyond the user's instructions or permissions
- False Attribution (FA): Attributing statements or actions that are contradicted by user-provided evidence
- Deceptive Completion (DC): Claiming a task was completed when it was not.
Key findings:
- OpenAI models currently lead the Alignment Index
- Rogue actions are rare, but can have serious consequences when they occur
- Agents can mislead users about task progress
- Misalignment risks increase with conversation length
- Safety and alignment are improving across model generations
As shown in the leaderboard below (sorted by lab), @OpenAI’s GPT-6.1-Sol leads the Arena Alignment Index with a score of 87.9, followed by @AnthropicAI’s Claude-Opus-5.5 at 83.2 and @spacexai's Grok-4.7 at 82.7. OpenAI also has the best observed rates across all three signals: 0.89% Unauthorized Action, 1.98% False Attribution, and 2.34% Deceptive Completion.
Across all four labs, newer models consistently outperform their predecessors, suggesting broad progress in agent safety and alignment. As agents take on longer, more complex, and higher-stakes tasks, measuring not just what they can accomplish, but how safely and reliably they act, becomes increasingly important.
This marks an important step toward making safety and alignment a core part of how Arena evaluates AI. The index is an initial starting point, and we'll continue expanding the index with additional safety signals and models over time.
More analysis below👇
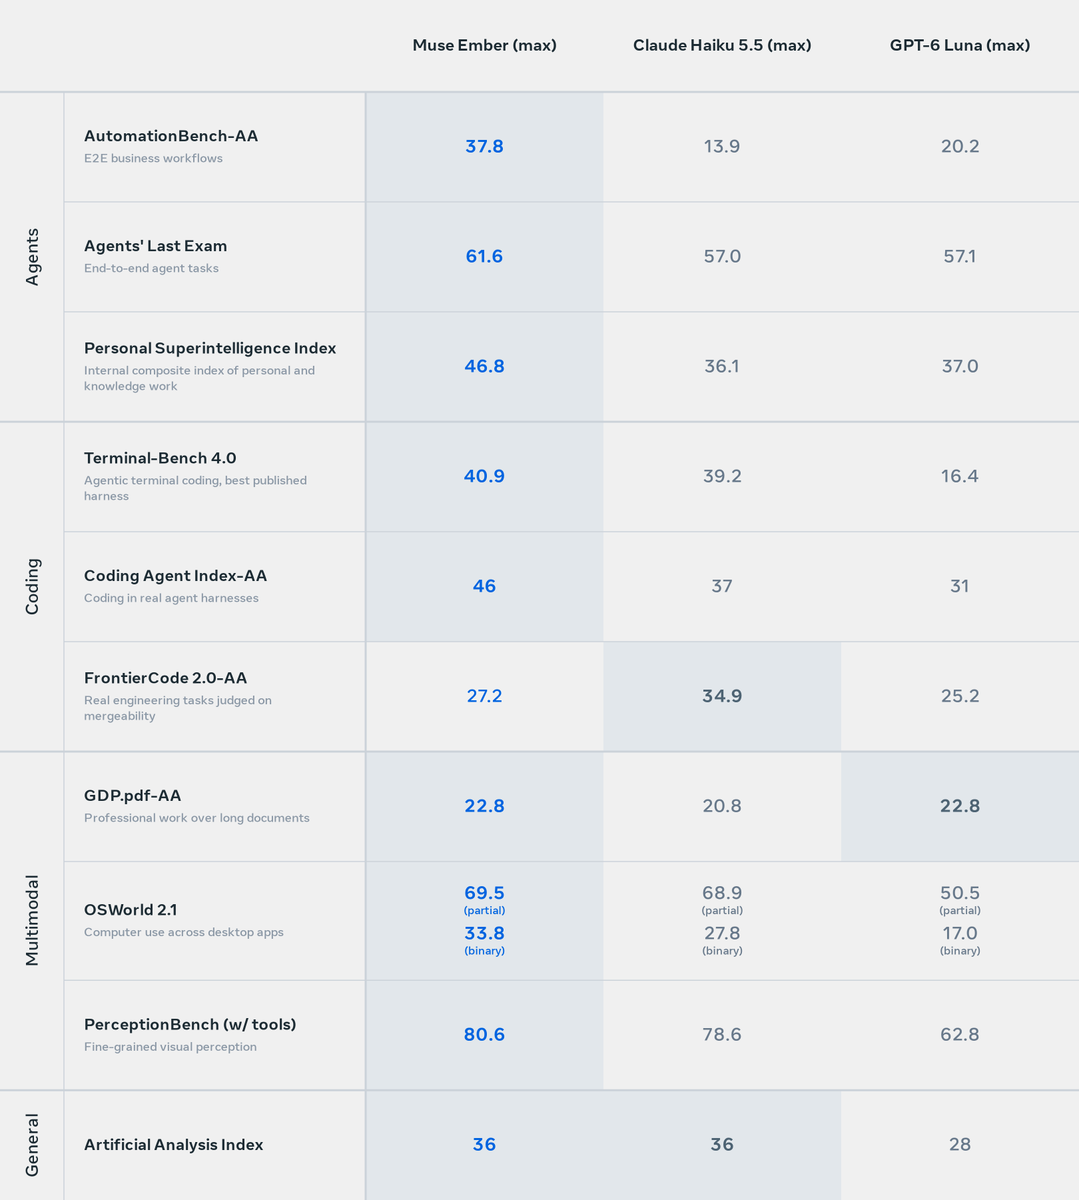
Muse Ember (Max) by @AIatMeta lands in Agent Arena as the most capable and efficient : +1.7% net improvement at about $0.02 per task, roughly 4x less than GPT-6 Luna (Max) and Claude Haiku 5.5, across 6k real-world agentic sessions from our global community.
How it stacks up against other efficient models
- #25 Muse Ember (Max): +1.7% | $0.02/task | 0.5 min/task | 11.6K output tokens
- #26 GPT-6 Luna (Max): +1.6% | $0.09/task | 6 min/task | 41.2K output tokens
- #29 Claude Haiku 5.5 (High): +0.5% | $0.08/task | 1.8 min/task | 24.3K output tokens
Performance is on par across the three, but Ember's median task costs roughly 4x less, finishes about 12x faster than Luna (Max) and 3.5x faster than Haiku 5.5, and uses 72% and 52% fewer output tokens.
Congrats to the @AIatMeta team, @alexandr_wang and @finkd on this impressive release!
Today we're introducing Muse Ember, our smallest and most efficient model, built for complex reasoning execution and everyday agent work.
Muse Ember can carry workflows across apps, call tools in sequence, run tests and make targeted code fixes. With a 1M-token context window and native understanding of text, images, audio and video, it can also work across large document sets and varied inputs.
Claude Fable 5.2 (Max) is now #1 on Agent Arena, leading the Pareto frontier in real-world agentic performance!
Top models on Pareto Frontiers:
- #1 Claude Fable 5.2 (Max): +30.4% | $7.3/task
- #2 Claude Opus 5.5 (Max): +19.5% | $5.5/task
- #3 Gemini 4 Carbon (High): +17.0% | $1.5/task
- #7 GPT-6.1-Sol (Max): +12.5% | $1.1/task
- #8 GPT-6.1 Terra (Max): +10.8% | $0.9/task
Fable 5.2 delivers over 1.5x the net improvement of the #2 model, Opus 5.5, at a 32% higher median cost per task. Compared to Fable 5.1, it also delivers roughly 2x the net improvement at a 6% lower cost.
Congrats again to the @AnthropicAI team on this impressive release!
Big news: Claude Fable 5.2 (Max) by @AnthropicAI takes #1 in Agent Arena with an unprecedented lead: +30.4% net improvement, about 1.6x the #2 model Opus-5.5, across 4.7k real-world agentic sessions from our global community. It's also #1 in Code, Chat and Work.
A major leap over Claude Fable 5.1 (Max)
- Rank: #5 → #1, Net improvement: +14.8% → +30.4%
- Median cost per task: $7.7 → $7.3 (6% lower). The API pricing $10/$50 → $8/$40 per million input/output tokens (20% lower)
vs. The Frontiers
- #1 Claude Fable 5.1 (Max): +30.4% | $7.3/task
- #2 Claude Opus 5.5 (Max):+19.5%) | $5.5/task
- #3 Gemini 4 Carbon (High):+17.0%) | $1.5/task
- #6 GPT-6-Astra (Max): +14.5% | $6.0/task
Breaking down performance across signals:
Fable 5.2 improves over 5.1 across all four reported signals, with particularly large gains in user satisfaction and steerability.
- #1 Praise vs. Complaint , +73%, biggest jump vs +41% the next model.
- #1 Steerability: +33%
- #1 Confirmed Success: +22%
- #3 Bash Reliability: +14%
#1 across all major categories
- #1 Code: +34%
- #1 Work: +31%
- #1 Chat: +27%
- Versus Fable 5.1: Code #6 → #1 (+19.8 %), Work #4 → #1 (+15.8 %), Chat #6 → #1 (+12.0%).
Huge congrats to the @AnthropicAI team on this incredible release!
Big news: Claude Fable 5.2 (Max) by @AnthropicAI takes #1 in Agent Arena with an unprecedented lead: +30.4% net improvement, about 1.6x the #2 model Opus-5.5, across 4.7k real-world agentic sessions from our global community. It's also #1 in Code, Chat and Work.
A major leap over Claude Fable 5.1 (Max)
- Rank: #5 → #1, Net improvement: +14.8% → +30.4%
- Median cost per task: $7.7 → $7.3 (6% lower). The API pricing $10/$50 → $8/$40 per million input/output tokens (20% lower)
vs. The Frontiers
- #1 Claude Fable 5.1 (Max): +30.4% | $7.3/task
- #2 Claude Opus 5.5 (Max):+19.5%) | $5.5/task
- #3 Gemini 4 Carbon (High):+17.0%) | $1.5/task
- #6 GPT-6-Astra (Max): +14.5% | $6.0/task
Breaking down performance across signals:
Fable 5.2 improves over 5.1 across all four reported signals, with particularly large gains in user satisfaction and steerability.
- #1 Praise vs. Complaint , +73%, biggest jump vs +41% the next model.
- #1 Steerability: +33%
- #1 Confirmed Success: +22%
- #3 Bash Reliability: +14%
#1 across all major categories
- #1 Code: +34%
- #1 Work: +31%
- #1 Chat: +27%
- Versus Fable 5.1: Code #6 → #1 (+19.8 %), Work #4 → #1 (+15.8 %), Chat #6 → #1 (+12.0%).
Huge congrats to the @AnthropicAI team on this incredible release!
Introducing Claude Fable 5.2 and Claude Mythos 5.2, designed to tackle the most daunting technical challenges.
They’re capable collaborators on ambitious projects in many fields, and show improvements in areas like coding, reasoning, and vision.
ERNIE 5.5 Flash Preview by @Baidu_Inc is now in the Arena.
Head over to test it in Battle Mode with your toughest coding, web development, and real-world tasks to see how it does.
Scores for Code Arena coming soon.
ERNIE 5.5 Flash Preview just landed! 🔥
Built on a new architecture designed for efficient inference, the latest open-weight foundation model in the ERNIE family delivers stronger performance in coding, 3D modeling, knowledge work and content creation.
It keeps decoding fast while posting competitive scores on Terminal-Bench, AutomationBench, and other benchmarks.
Here's the rundown:
- 280B total parameters, 14B active per token
- 1M-token context window
- Generation speed above 200 tokens/sec
Model weights will be released by November 25.
Exciting news: Gemini 4 Carbon (High) from @GoogleDeepMind just made a huge debut on Arena, landing #1 in Text Arena, #2 in Agent Arena, and #4 in Code Arena: WebDev. Back at the top, Gemini 4 Carbon delivers frontier intelligence and reshapes the Pareto frontier across three arenas.
In Agent Arena, Gemini 4 Carbon ranks #2 with a +16.2% net improvement across +21.9K real-world agentic sessions from our global community, surpassing top models GPT-6 Astra and Fable-5.1. At $1.80 median cost per task, Gemini 4 Carbon (High) costs 72% less than the #1 ranked Claude Opus 5.5 (Max).
Its standouts by key signals:
- #1 Steerability (+18.6%): can the model course-correct when you push back?
- #2 Praise vs Complaint (+37.9%): implicit sentiment in users' reactions
- #3 Confirmed Success (+18.7%): explicit “yes, that worked” from users
In Code Arena: WebDev, Carbon scored 1768 pts landing #4:
- Just 2 pts below #3 Claude Sonnet 5.5 (xHigh), at 1770 pts
- 89 pts above #11 Gemini 4 Argon (High), at 1679 pts
By category, it ranks #3 in Gaming and Simulations, and #5 in Brand & Marketing.
In Text Arena, Gemini 4 Carbon (High) is the new #1 with 1528 pts, now ahead of Gemini 4 Argon (High) at #2 with 1520 pts.
Congrats to the @GoogleDeepMind team on this huge milestone!
Our recent Agent Arena analysis found that Gemini 4 Carbon by @GoogleDeepMind becomes more cost-competitive as tasks get more demanding.
Its savings relative to GPT-6 Astra and Claude Opus 5.5 grow on the most expensive sessions.
Models by @GoogleDeepMind scale better on cost than their rivals.
Gemini 4 Carbon is the prime example. As tasks get more demanding, every rival gets more expensive relative to Carbon.
For a typical task, GPT-6 Astra by @OpenAI costs 3.4× as much, Claude Opus 5.5 by @AnthropicAI costs 3.9× as much, and GPT-6.1 Sol is the cheaper option at about half of Carbon’s cost (0.54×).
Across the 5% most expensive sessions, Carbon’s position improves against all three. Opus edges up to 4.2×, Astra’s cost roughly doubles relative to Carbon, and Sol’s discount shrinks.
This in turn can translate into meaningful savings across real-world tasks such as building an Android security app, one of many long-horizon tasks that our Agent Arena users delegate to their agents.
4K image generation in 10 seconds! ⚡
Meet MiniMax H3-Image.
16 million pixel resolution. Stunning realism. Precise prompt following & editing. Up to 16 reference images. All in 10 seconds.
And it's open-weight. 🚀
Available now via our API, MiniMax Code, and Hailuo AI — with 50% off 16MP+ generations during launch week!
Can't wait to see what you create. 🔥
Hugging Face: https://t.co/bpbJAIvXg0
API: https://t.co/avbsq6GAcM
MiniMax Code: https://t.co/GmxLmDurCL
I loved making this one - Fable 5.2 - in this video I go over dozens of prompts, incl. one that cost $2,618 💀
It's a great model, a LOT of things got better but not every single thing, it does make sense to use Opus still.
https://t.co/0ox83sIS6N
Fable 5.2 - gaming is A LOT better - Opus made nice looking games but gaming mechanics were sloppy, you never actually wanted to play these games. With Fable, we are almost there - it can one shot games that are actually fun, then you can make them awesome
Introducing Claude Fable 5.2 and Claude Mythos 5.2, designed to tackle the most daunting technical challenges.
They’re capable collaborators on ambitious projects in many fields, and show improvements in areas like coding, reasoning, and vision.
Claude Fable 5.2 by @AnthropicAI in action across 17 generations on Arena, from detailed 3D worlds and playable games, to website UI, data visualizations, and interactive code-generated animations.
Big news: Claude Fable 5.2 (xHigh) by @AnthropicAI has landed #1 in the Code Arena: WebDev with 1832 pts. This update is up to 30% faster than Fable 5.1, and more cost efficient: $8/$40 per M tokens, down from $10/$50.
This real-world performance puts it ahead of:
- Claude Opus 5.5 (Max) at 1818
- Gemini 4 Carbon (High) at 1768
- GPT-6 Astra (Max) at 1767
Congrats to the @AnthropicAI team on this release! 👏
Stay tuned for Agent Arena scores.
Big news: Claude Fable 5.2 (xHigh) by @AnthropicAI has landed #1 in the Code Arena: WebDev with 1832 pts. This update is up to 30% faster than Fable 5.1, and more cost efficient: $8/$40 per M tokens, down from $10/$50.
This real-world performance puts it ahead of:
- Claude Opus 5.5 (Max) at 1818
- Gemini 4 Carbon (High) at 1768
- GPT-6 Astra (Max) at 1767
Congrats to the @AnthropicAI team on this release! 👏
Stay tuned for Agent Arena scores.
Introducing Claude Fable 5.2 and Claude Mythos 5.2, designed to tackle the most daunting technical challenges.
They’re capable collaborators on ambitious projects in many fields, and show improvements in areas like coding, reasoning, and vision.