Fast Byte Latent Transformer is accepted to ICML 2026! ⚡🥪
Byte-level LMs promise to free us from subword tokenizers, but decoding one byte at a time is super slow.
We make BLT generation more efficient with BLT-D: text diffusion for parallel byte decoding. 1/
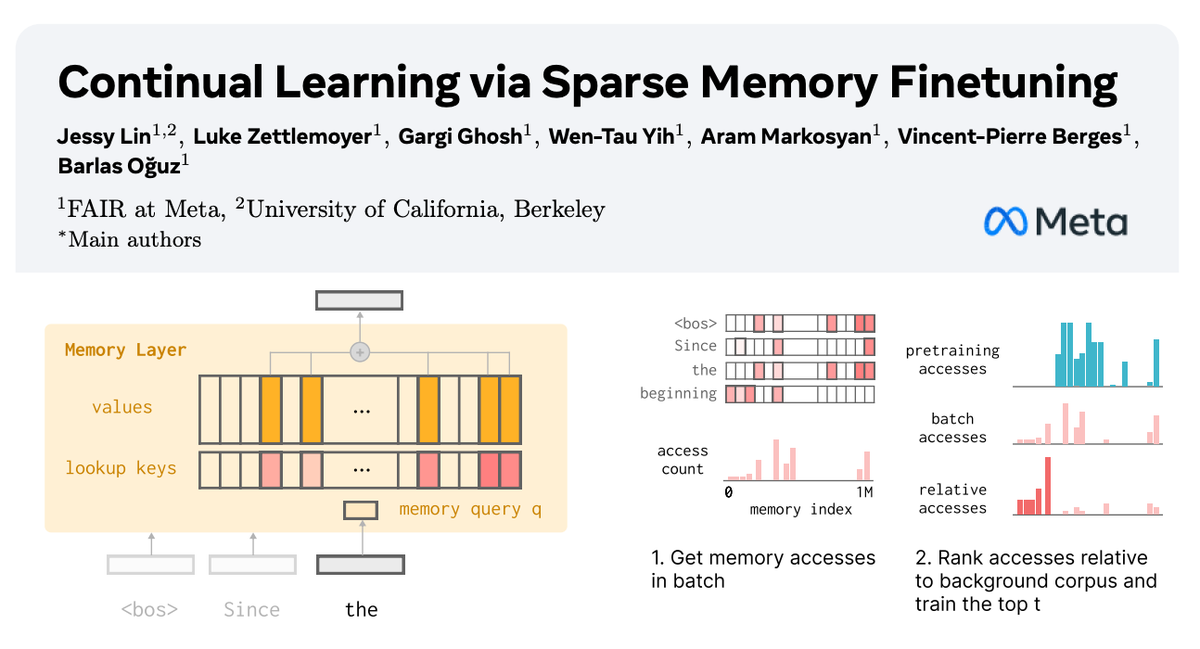
🧠 How can we equip LLMs with memory that allows them to continually learn new things?
In our new paper with @AIatMeta, we show how sparsely finetuning memory layers enables targeted updates for continual learning, w/ minimal interference with existing knowledge.
While full finetuning and LoRA see drastic drops in held-out task performance (📉-89% FT, -71% LoRA on fact learning tasks), memory layers learn the same amount with far less forgetting (-11%).
🧵:
🚀 Introducing the Latent Speech-Text Transformer (LST) — a speech-text model that organizes speech tokens into latent patches for better text→speech transfer, enabling steeper scaling laws and more efficient multimodal training ⚡️
Paper 📄 https://t.co/4nUsbC1YKF
🔍 How do we teach an LLM to 𝘮𝘢𝘴𝘵𝘦𝘳 a body of knowledge?
In new work with @AIatMeta, we propose Active Reading 📙: a way for models to teach themselves new things by self-studying their training data. Results:
* 𝟔𝟔% on SimpleQA w/ an 8B model by studying the wikipedia docs (+𝟑𝟏𝟑% vs plain finetuning)
* a domain-specific expert model: 𝟏𝟔𝟎% vs FT on FinanceBench knowledge
* an 8B wikipedia expert competitive w/ 405B on factuality (💥open-sourced!)
🧵[1/n]
And understanding how to teach models new things is increasingly impt – not just for training capable specialized models (e.g. AR as a practical technique for training personalized/expert models), but looking towards a continual learning paradigm where models keep acquiring new skills/knowledge through interaction with the world.
Retrieval / text-based memory works fine today, but to have models that keep getting smarter over time - we need to figure out parametric methods for memory.
When an agent encounters a new piece of experience, how can it update on it effectively to build up its knowledge/skills over time - like humans do? (maybe the first step: active reading!)
🧵 [9/n]
...is today a good day for new paper posts?
🤖Learning to Reason for Factuality 🤖
📝: https://t.co/1j3624uDjl
- New reward func for GRPO training of long CoTs for *factuality*
- Design stops reward hacking by favoring precision, detail AND quality
- Improves base model across all axes
🧵1/3
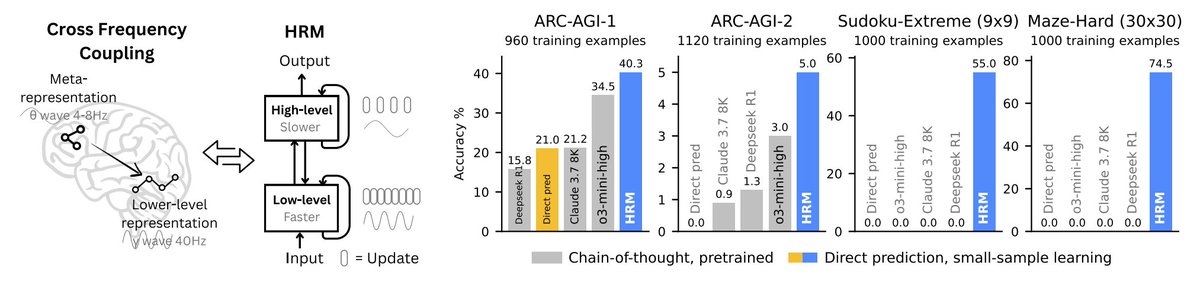
🚀Introducing Hierarchical Reasoning Model🧠🤖
Inspired by brain's hierarchical processing, HRM delivers unprecedented reasoning power on complex tasks like ARC-AGI and expert-level Sudoku using just 1k examples, no pretraining or CoT!
Unlock next AI breakthrough with neuroscience. 🌟
📄Paper: https://t.co/Sxprojsv0c
💻Code: https://t.co/k15cUS2wlf
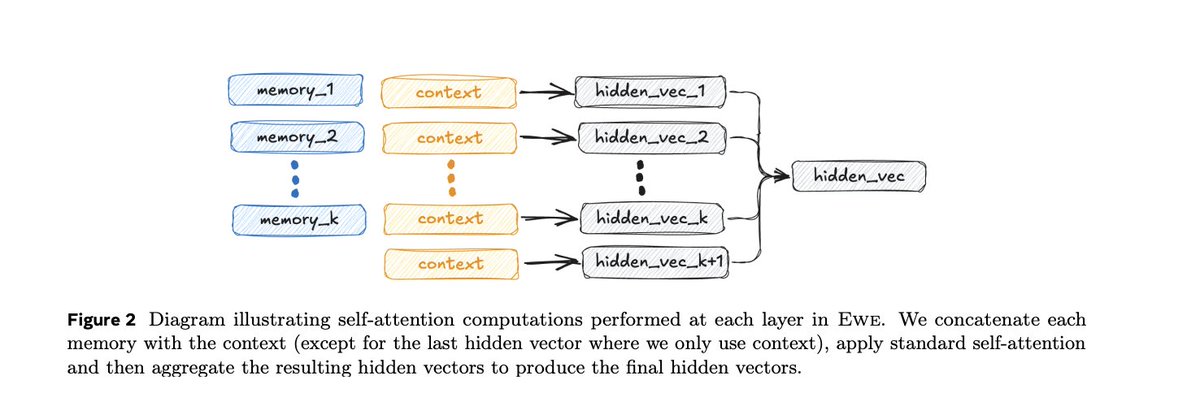
Last one of the year - EWE: https://t.co/D5y53ahtyX
Ewe (Explicit Working Memory), enhances factuality in long-form text generation by integrating a working memory that receives real-time feedback from external resources.
New research from Meta FAIR — Meta Memory Layers at Scale. This work takes memory layers beyond proof-of-concept, proving their utility at contemporary scale ➡️ https://t.co/0E952C2fJB