New prison guard comes up to my cell.
“Top G! And Talisman! My guys!!”
Me: “Easy”
PG: “What the hell you guys doing up here in the SHU unit? This is for the crazies!”
Me: “You tell me. Been here 114 days because of an old MeToo out of the UK from 15 years ago”
PG: “Bro! That’s some BULLSHIT! You don’t belong here!”
Turns out everyone in the jail knows I don’t belong here but the “higher ups”.
It's time to introduce myself again, since I have new followers here:
+ Ghostwriting/copywriting for brands for the past 3 years
+ Generated over 2.4 billion views online + exited a brand at 21
+ Deleted my 10k-follower account to build an audience of only elite brains
+ Helped my clients make more than $2M from X
+ Currently educating people on CRACKING SOCIAL MEDIA (+ SOON consumer apps) for FREE
+ Documenting my business journey, including the difficulties and insecurities I face, so I can show these tweets to my kids one day and they can see how baller their dad is
If you’re an elite brain who wants to master social media and you enjoy reading authentic, non-AI-slop content, drop a follow.
You won’t be disappointed ;)
Been using Deepseek V4.1 Flash Aliberated for 1 week now, running it on Opencode with api key from @refuselessai, it is sick. Its so crazy that it found weaknesses in official infrastructure just with some simple prompts (mind u im not a tech guy).
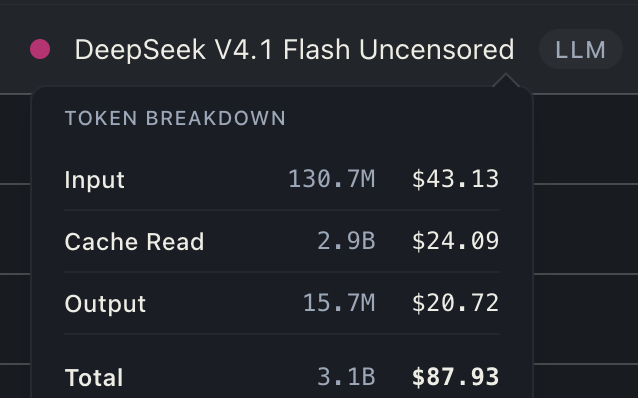
i've burned through 3 BILLION tokens on uncensored deepseek v4.1 flash in the past 24 hours for $87
if you're still defaulting to claude and chatgpt for everything you're ngmi
PLEASE spend a weekend going down the chinese open-weight model rabbit hole. deepseek, qwen, kimi, glm, uncensored fine-tunes, abliterated models, local inference, all of it
the price/performance on some of this shit is genuinely ridiculous and 99% of people have no clue it even exists
you can run smaller models locally with Ollama, LM Studio or MLX. larger models through Venice AI or other inference providers. plug them into OpenCode and suddenly you have a coding agent with terminal access, browser tools, filesystem access, whatever you configure
YOU DO NOT NEED TO BE LOCKED INTO ONE MODEL OR PROVIDER
here's a prompt. literally paste this into your coding agent:
"research the current chinese open-weight model ecosystem. deepseek, qwen, kimi, glm, plus uncensored and abliterated variants.
inspect my hardware and figure out what i can run locally with Ollama, MLX or llama .cpp. for anything too large, compare hosted providers including Venice AI.
compare actual output tokens/sec, TTFT, context limits, input/output pricing, cache pricing, coding ability and tool-calling reliability. find the best options for my actual workloads, not benchmark leaderboards.
set up OpenCode with the best local and hosted models for my budget. configure the providers, test tool calling, optimize context usage and benchmark identical tasks across endpoints.
show me the fastest, cheapest reliable setup you can actually get working. verify everything before changing my existing configuration."
ALSO PLEASE understand that the model and the inference provider are two different things
you can have the EXACT same weights running at wildly different speeds depending on who's serving them. check real decode speed, not advertised throughput
prefix caching, context compaction, quantization, model routing. look into this shit. your agent could be spending more money rereading old tool outputs than actually solving anything
and stop using expensive reasoning models for tasks a tiny local model or 20 lines of python could handle
there's so much money being wasted on AI subscriptions by people who haven't even tried running a model outside a chat window
it's actually insane
I genuinely don't understand how a payment platform like @whop can hold someone's money for almost a WEEK and refuse to let them speak to an actual human being.
Let me explain what's happening.
I used Whop to receive a payment that was supposed to be available INSTANTLY.
Instead, they decided to hold my funds and requested additional business documentation.
Fair enough. I understand that payment platforms have verification procedures.
So I provided the documents they requested.
I was then told that the process would take 1–3 business days.
Fast forward to today.
Almost a week has passed, and I still don't have access to MY OWN MONEY.
But here's where it gets ridiculous.
I've tried contacting their support through both live chat and email.
And every single time, I'm met with what appears to be the same AI-generated responses.
"I understand your frustration..."
But no actual solution. No clear explanation. No human being willing to take responsibility for the situation.
And apparently, I can't even get transferred to a real support agent.
How is that acceptable for a company handling people's money?
We're not talking about a delayed package or a software bug.
We're talking about money that businesses depend on to operate.
Cash flow matters. Bills don't stop coming because a payment processor decides to hold your funds.
I have absolutely no problem complying with legitimate verification requirements.
What I have a problem with is being promised a timeframe, providing everything requested, and then being left in the dark with an AI chatbot repeating the same useless answers.
If a company can hold your money, it should at least have a real human available to explain WHY and WHEN it will be released.
@whop, I don't need another automated apology.
I need three things:
A real human to review my case.
A clear explanation of why my funds are still being held.
An actual date when my money will be released.
Is that really too much to ask from a payment platform?