@livingdevops That’s true. Even after exploring multiple options for the IaC, still feels Terraform feels better(as of). Also we are criticising k8s for its complexity but still I am running and troubleshooting 1000’s pods even today.
Again finOps issue popped up on my slack today.
Honestly, the best cost optimizations I have ever seen were not fancy, it is just consistent habits:
visibility, ownership, and automation.
Once teams start treating cost like a metric (same as latency), things change fast.
This is so true. In my experience deploying LLM workloads, Linux is where things stay predictable drivers, containers, CUDA libs, orchestration process and everything aligns better. Windows can work for experiments, but for production-grade stability and repeatable deployments, Linux saves a lot of hidden effort.
@mischavdburg True. If you can babysit nodes, tame autoscalers, and survive multi-cluster networking… doing it from home is the easy part, Kubernetes was remote before we were.
The “DevOps Hero” is the biggest risk to your reliability.
If only one person can deploy, fix prod, or run pipelines means you don’t have DevOps.
You have a single-point-of-failure problem.
A healthy team should a bus factor of 3+.
Agree or disagree?
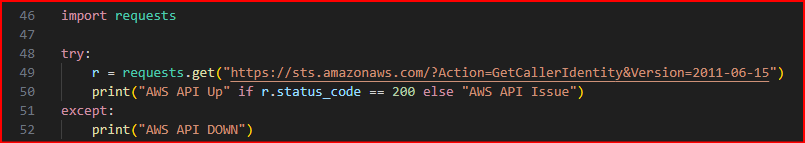
This 5-line Python script checks if your cloud provider's API is truly down, bypassing status pages. Saved my weekend two times last month.
#Python#Cloud
@codewithpri by honest both have their own challenges but as a DevOps engineer, I have seen one thing: everything gets harder when Dev + Ops aren’t aligned. Frontend, backend, or DevOps… the best outcomes happen when all three work together instead of comparing difficulty.
@govardhana_mk Absolutely true. In my experience, strong fundamentals + daily hands-on practice + real problem-solving matter far more than any tool or cert. Once your basics are solid, every new DevOps skill feels natural. This is exactly how I grew in my career.
@NaveenS16 Absolutely agree. I have used Workload Identity Federation in a few real setups, and it’s a game-changer.
No more worrying about service account key rotation or someone accidentally exposing a JSON file in a repo.
Most developers think monitoring means Grafana dashboards. They are 100% wrong. Monitoring must be predictive, not reactive.
I track queue backlog velocity, not the size.
What's the one non-standard metric you track that saves you time? Reply with your metric!
#Monitoring#SRE
Check out the latest article in my newsletter: How U.S. Tariffs Are Impacting the AI Industry: A Deep Dive Into Economic, Technological, and Global Implications
https://t.co/reZA23P30Z via @LinkedIn#AI#USA#India#GlobalEconomy
Check out my latest article: Kubernetes DNS (CoreDNS, Custom DNS Configurations, Debugging DNS Failures) – A Deep Dive
https://t.co/xyAvT7hyvt via @LinkedIn
Check out the latest article in my newsletter: AI Agents in the Real World: Breaking Myths and Unlocking Potential
https://t.co/fhR0Ga0eVi via @LinkedIn