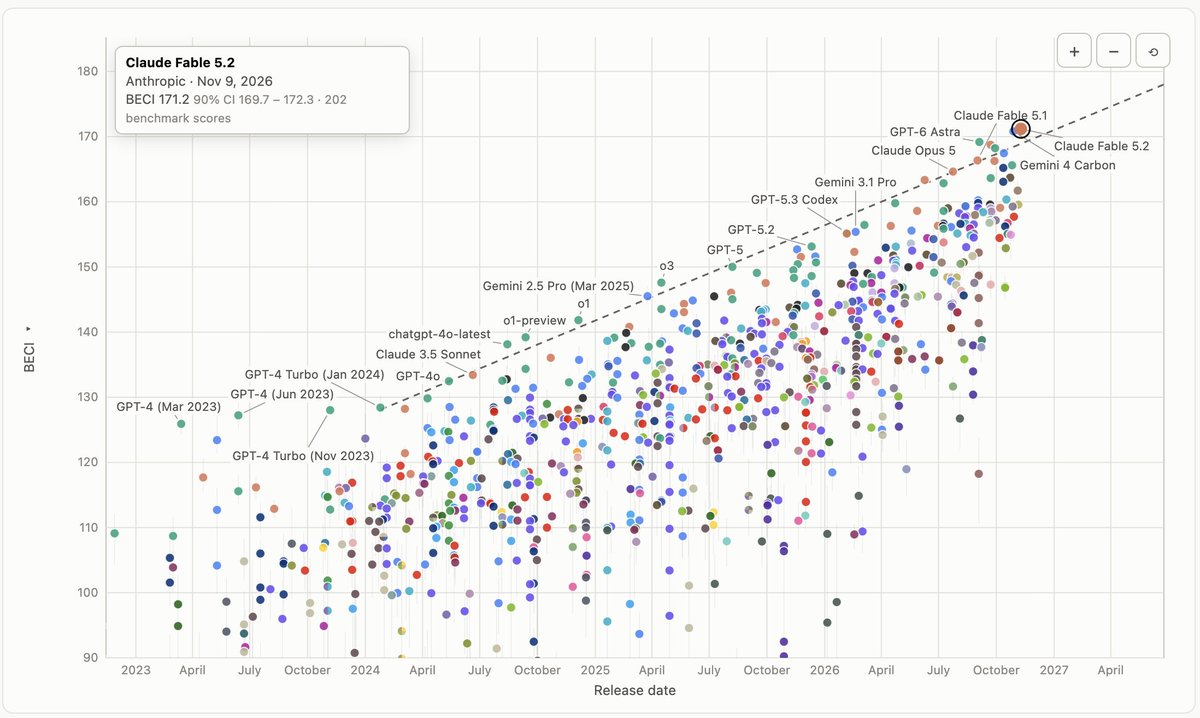
@Aging_Scientist@YafahEdelman You’re probably thinking of this? It’s now at 169.2 for me, and still at 169 for epoch, so it didn’t regress https://t.co/KPe4TiHScZ
when it was posted, I saw this result and it seemed excessively high, so I assumed it was partly noise propping the score up. Besides, my ECI replication project had astra at a ~167 BECI, based on 35 scores. Now 131 benchmark scores have come in, and strangely Astra is up to 169.6 [167.6 - 171.4 90% CI]! This is mid-nov'26 pace on the current trendline, and the biggest gap above this trendline yet
@herbiebradley@DKokotajlo@kesvelt i don't have any particular info about this but my model of ants is that they would find it pretty cursed to advertise claude plays pokemon after training it in RL loops on that particular game. I think they probably had not done that, and plausibly still haven't
@TheDavidSJ I find "TEDAI is just so many tasks. We only have evidence about trends and levels on a relatively small number of tasks." fairly convincing.
Tbf fable outperforms its AECI prediction so far. Regressed to the aeci scale it gets 178.6. My conspiracy theory is that it accidentally trained on test on some of these public benchmarks because its knowledge is so absurdly broad that it’s hard to avoid. My real theory is that this is mostly noise / idk what causes it
I predict that Fable 5.2's ECI will regress to ~172 as more scores come in. its BECI so far is 171.4, based on 250 benchmark scores vs Epoch's 9 (7 of which are ≥90%!). dots are BECI, diamonds are ECI.
Claude Fable 5.2 sets a new record on the Epoch Capabilities Index (ECI) at 174. The previous high was GPT-6 Astra’s 169. Fable 5.2’s score is above what the pre-Astra trend for reasoning models would have predicted.
This is notable given recent discussion of AI contributions to AI R&D, and we hope to release more work in this area soon.
This is based on testing we did prior to launch using only our own benchmarks. The ECI is continually updated as more benchmark results become available, and may change in the future.
https://t.co/Hf6RIy0Bdo for the ECI-relevant scores. Note that my "benchmark scores" count includes sub-benchmarks (eg. gdpx_v1 has 13), so it's really 83 groups of scores.
@aliceisplaying is it inaccurate or more vague, or something else? anti-distillation measures are plausible but they'd probably not like sabotage it, maybe make it less detailed?
> We also predict a 35-65% chance that Top-Expert-Dominating AI (TED-AI), AIs that can automate all white-collar work, will arrive before 2028
That seems way too high to me!
Unfortunately, it seems like the intelligence explosion will be happening in 2027 after all. Most of this post analyzes the new METR report (though other sources of evidence are also important). If they’re right, that implies an AI-driven acceleration that is 5 months ahead of the AI 2027 scenario. I am scared, sad, and angry. https://t.co/7KWmdc6AZk
I appreciate your comments, I am not sufficiently in the weeds on the parametrization to follow the details but yeah there are a lot of experts in the world and humans are very specialized and have learned on a lot of data that have a very costly verifier or that is very private, it's a very high bar!
turning a big dial taht says "Level of Freakout" on it and constantly looking back at the audience for approval like a contestant on the price is right
@fleetingbits https://t.co/2Tu8dLoOnV is the best one according to claude in the set of safety benchmarks i track, but better would be some kind of combination of a bunch of measures like this one, IRT-style