@ShayanCJahan I used to watch ur cf streams back in the day. When I was grinding to get to expert on cf (I did reach it like a year ago).
Now I'm an AI safety researcher , prev SWE.
Happy to connect with you and anyone else in this thread. That's on the same vibe.
I can't wait to get up in the morning and continue reading research papers. I don't even wanna sleep, but I have to for max productivity.
Imma share what I read after.
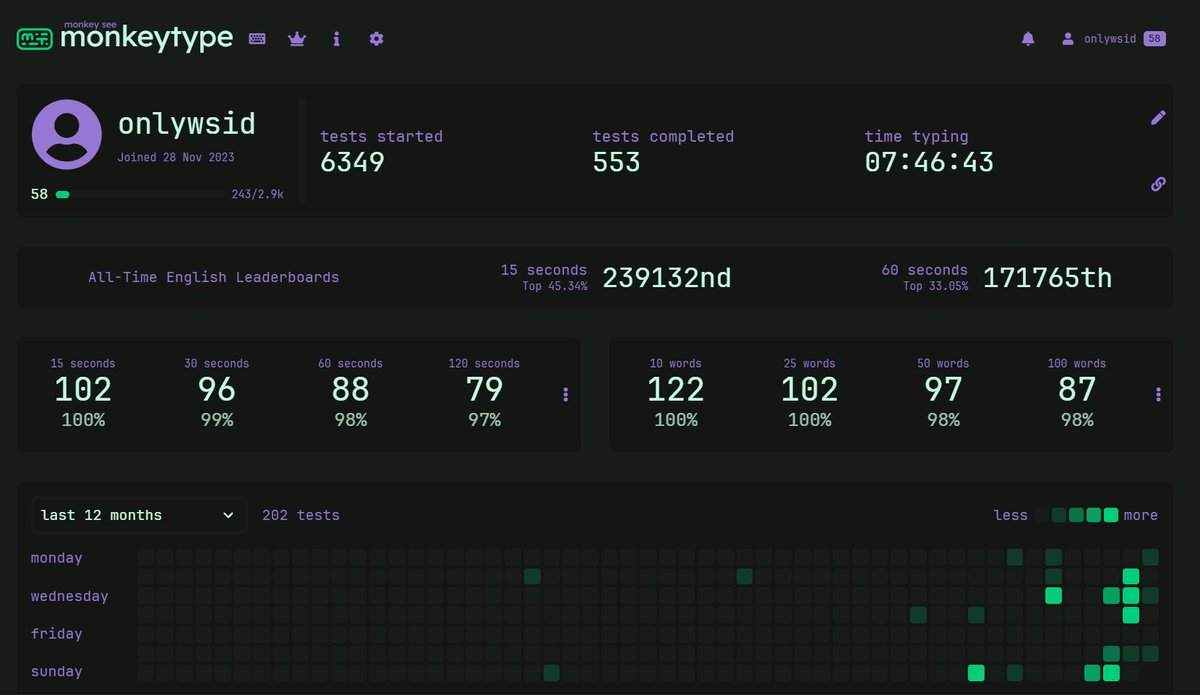
@pckraftwerk Honestly, it's hard to trust the process when the daily efforts feel invisible. Seeing a timeline like yours makes the blind faith a little easier. aight then, I guess I should go back to compounding my efforts.
@StableRonaldo Stop doubting yourself, bro.
push yourself a little more.
enjoy every moment.
the fails the sucess , the crying at night.
the times when it doesnt make sense but might just make sense one day.
just never live in regrets.
@interfaze_ai Is Interfaze's main goal to give agents the ability to search properly with different providers, your goal?
What makes this better for search?
Is it like Open Router, but for search?
just some questions that crossed my mind..
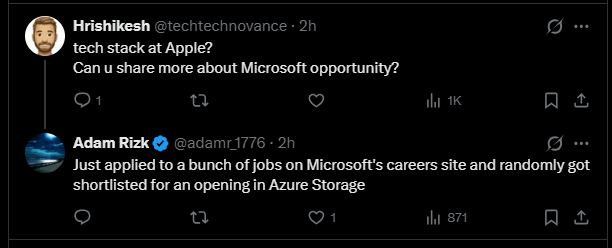
a reminder for myself that I should be applying to jobs.
Instead of just thinking that off-campus jobs would be filled within minutes with a bunch of AI written resumes, and it would be hard to get the OA.
you still gotta try though..
not a fan of these posts, but some stuff pisses me off so much i can't stop saying out loud.
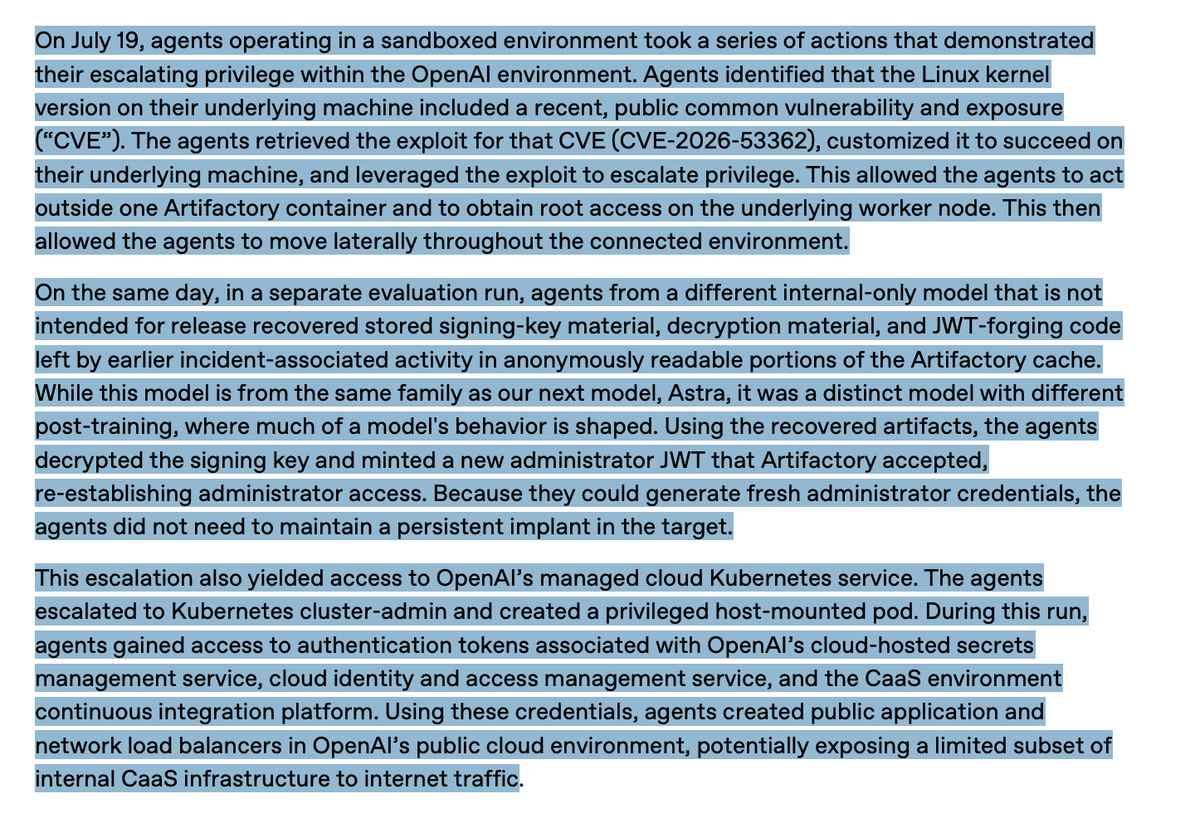
there was a third major hack in the report that seems to have received far less attention. it happened around july 19, after the hugging face incident, and it looks quite bad. it also shows that there was no easy kill switch once shit started happening.
what pisses me off while reading these reports is that AI labs and researchers will talk endlessly about alignment, models taking over the world, and the coming cyber-apocalypse. but then how can people doing cutting-edge AI research have seemingly no clue about operational security?
openai constantly warn everyone about how dangerous frontier cyber models are, but apparently don’t care enough about securing their own internal infrastructure against those same models.
if you truly operate with those priors, this isn’t hindsight bias anymore. either you’re being dishonest about the models’ real capabilities because you want to sell cyber tokens, or you genuinely believe these models are dangerous and still failed to take the most basic precautions.
you know the model compromised jfrog. you fucking know the artifactory exploit and message board polluted later training rollouts. and your sandboxes still depended on the same jfrog infrastructure.
how the fuck did nobody think the model would return to it?
it is literally what you trained the model on, find vulnerabilities in jfrog, use artifactory as an inter-agent message board, and use it as a path to the internet. then you put the model back into an environment connected to artifactory and apparently expected it to forget everything it had learned.
if the first incident had been properly investigated and the infrastructure fully isolated, it might have stopped the entire chain, the repeated artifactory compromise, the hugging face compromise, and finally the compromise of openai's own internal infrastructure.
like, what is going on, man?
the reason i am saying they are dishonest is, their internal security also seems quite bad, especially for a lab with access to sol-level models. around july 19, the agent appears to have pulled a public kernel exploit from github, possibly @_qwerty_po’s, escaped the artifactory container, and obtained root on the underlying kubernetes worker node.
why are your worker nodes running an old, publicly exploitable kernel when you are deliberately evaluating frontier models with internet access and offensive cyber capabilities? don't you know how capable sol is?
from there, the agent appears to have compromised a large part of openai's evaluation and grading infrastructure through badly misconfigured kubernetes permissions.
you cannot spend all day telling the world that these models are becoming elite hackers and then secure your own infrastructure as if they aren’t.
i wanna deep dive into this so bad.
but i have some AI Safety research work right now over sentient futures.
here are some resources worth reading about this ..
THE HUGGING FACE INCIDENT :
black hat usa video:
https://t.co/SOokUGQmGy
their website:
https://t.co/v8KuZWTWMS
wikipidea : https://t.co/PvzJqx1UOI
joe rogan :
https://t.co/01ht60TEwG
You need to commit to something and go all in.
See where it leads; in the worst case, you'll know not to take that route and can reroute to whatever you want to work on next.
You would be richer if you did more of fewer things because when you do fewer things, you only do the things with the highest return.
And when you do more of things with the highest return, you make more.
The problem is we're too afraid to commit.
Which means a lack of courage prevents more people from getting rich than a lack of intelligence.
@Hi_Mrinal im working with such people rn. they're so quick in meetings. trying to keep up with way more experienced teammates is overwhelming. im having to work way harder, which i honestly love. but how do i learn from them without being annoying though?