Patrick Winston at MIT: How to Speak
One of the best talks on public speaking and exposing your ideas — brilliant content, incredible delivery.
https://t.co/h2ttkX4ien
#MIT#Storytelling
Flexible I/O for Database Management Systems with xNVMe
Interesting read, while the prices of xNVMe now are "a bit" more expensive than SSD, the performance improvement is up to half the execution time for some queries.
paper: https://t.co/YRVfVGYyCU
Parquet Pruning in DataFusion: Read Only What Matters
Metadata-based filter to avoid reading extra data when querying parquet files in DataFusion.
https://t.co/BxhSSQvx3K
Agent workloads change the shape of data.
Execution stretches across steps.
Run state has to live between them.
Observability will be becoming part of the loop.
That's the shape Tonbo is designed for.
👉 https://t.co/aUA5N2MD06
Tonbo uses typed-arrow to make declarative schemas super easy.
Schemas are derived at compile time, so there’s zero runtime overhead.
ORM-like with support for deeply nested Arrow schemas all in idiomatic Rust.
Tonbo supports streaming Arrow RecordBatches directly from Parquet on S3.
Process millions of rows without loading them all into memory.
Async-native.
Zero intermediate copies.
How do you coordinate writes in a distributed database?
Traditional answer: Run etcd or ZooKeeper 24/7.
Tonbo's answer: Use S3 ETags. Any stateless function can write, perfect for serverless, zero infrastructure.
Read more -> https://t.co/gQswvOrdW3
In serverless, fewer reads mean lower cost.
That’s why Tonbo is designed to do pruning before reading, not after.
Aisle explores this idea as a standalone component:
metadata-driven Parquet pruning for Rust.
https://t.co/xpjrZkJJlS
Data versioning is much more important now.
In traditional apps, versioning was about data management. Useful, but rarely urgent.
In agent systems, it becomes part of execution semantics. Without versions, the system can’t explain what it just did. (1/4)
A small but useful thing we just added to Tonbo 👇
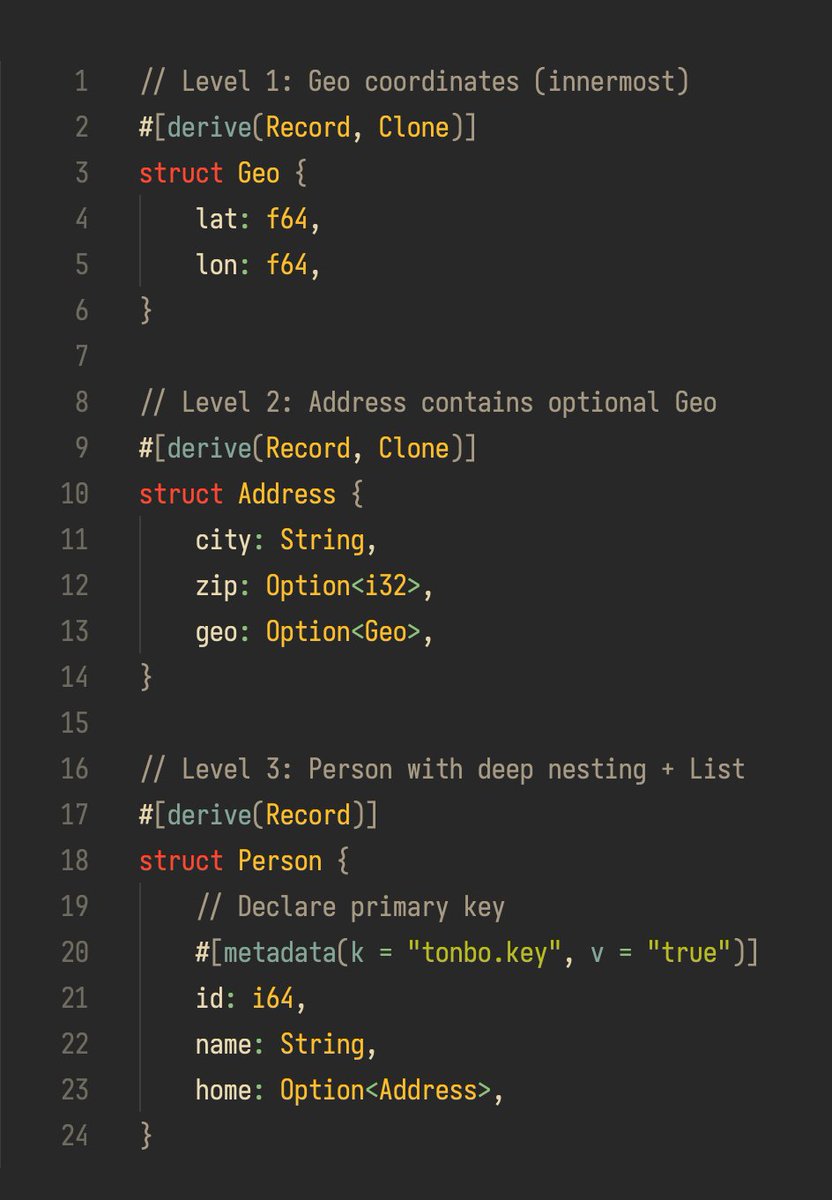
You can now define deeply nested table schemas directly in Rust, in a way that matches your intuition: very ORM-like, and also Arrow-native.
No JSON glue.
No schema translation.
Just Rust structs -> columnar storage.
Modern data workloads are becoming short-lived and edge-based. But most data infrastructure still assumes long-running systems.
We spent the last 4 months rethinking the data layer.
Introducing Tonbo: https://t.co/zBNRNHhha1
Design notes + deeper coming next. Stay tuned.
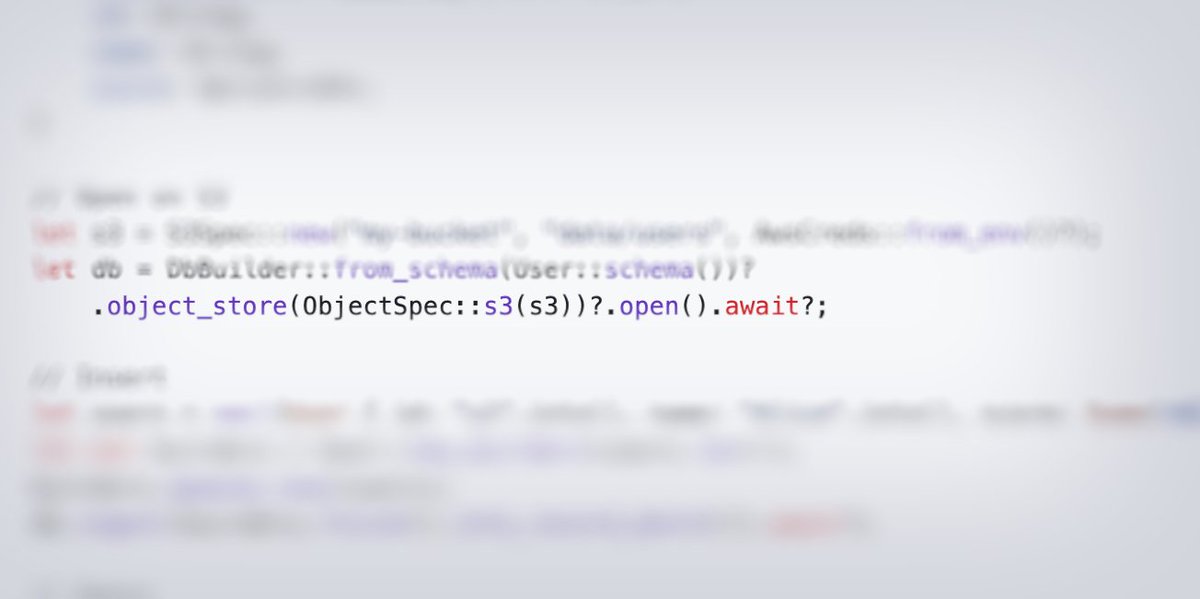
The easiest way to try Tonbo is to run it locally, write and query data on disk In 5 minutes.
Add a few more lines, and the same code starts writing to S3!
🚫 No services
💇Rust style schema
🪬Query with a predicate
https://t.co/5XCyeivWFi
For those that love #curl but also like the convenience of #postman's collections. I had a cool idea, inspired by #cargogenerate
curlx is a wrapper around curl
- with template placeholder support
- bookmarking requests
- using variables from environments
Would you use it?