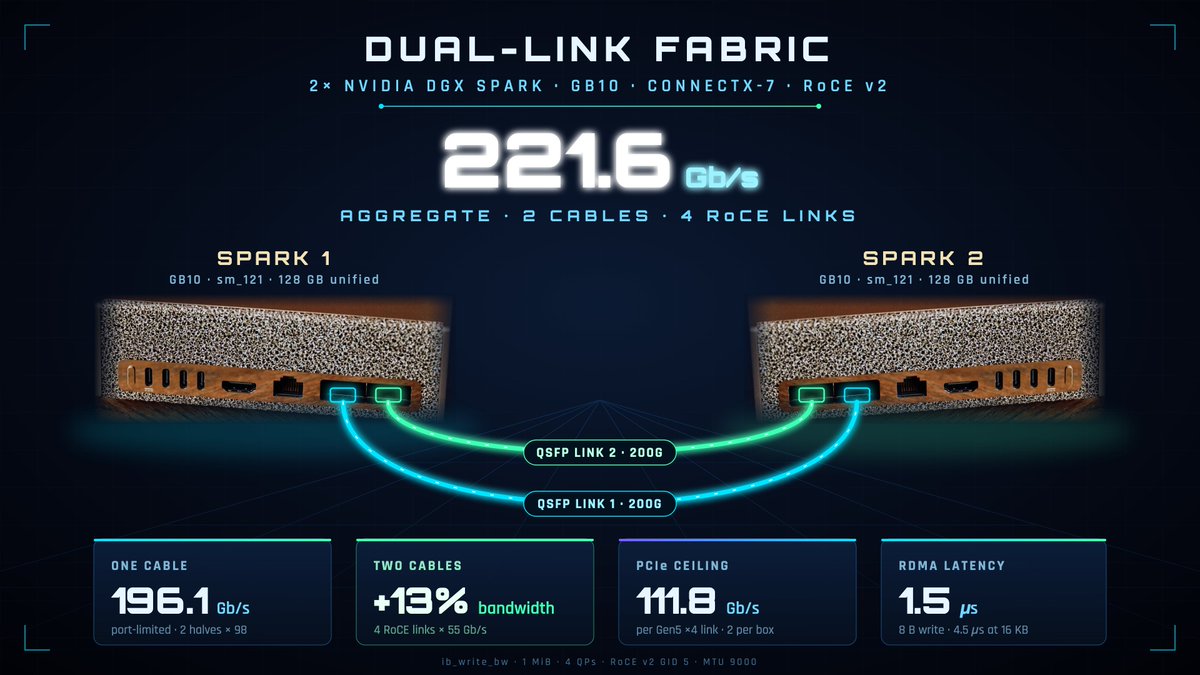
Two DGX Sparks, one model 🔗
Qwen3.8-27B (EXL3 4-bit) on TensorFold native, tensor-parallel across both Sparks:
62 → 92.6 tok/s on code (+49%), 128K ctx ⚡
Still testing 🧪
PR coming soon for a faster long-prompt kernel (128K prompt: 41 min → 3.7 min)
@ashxhart
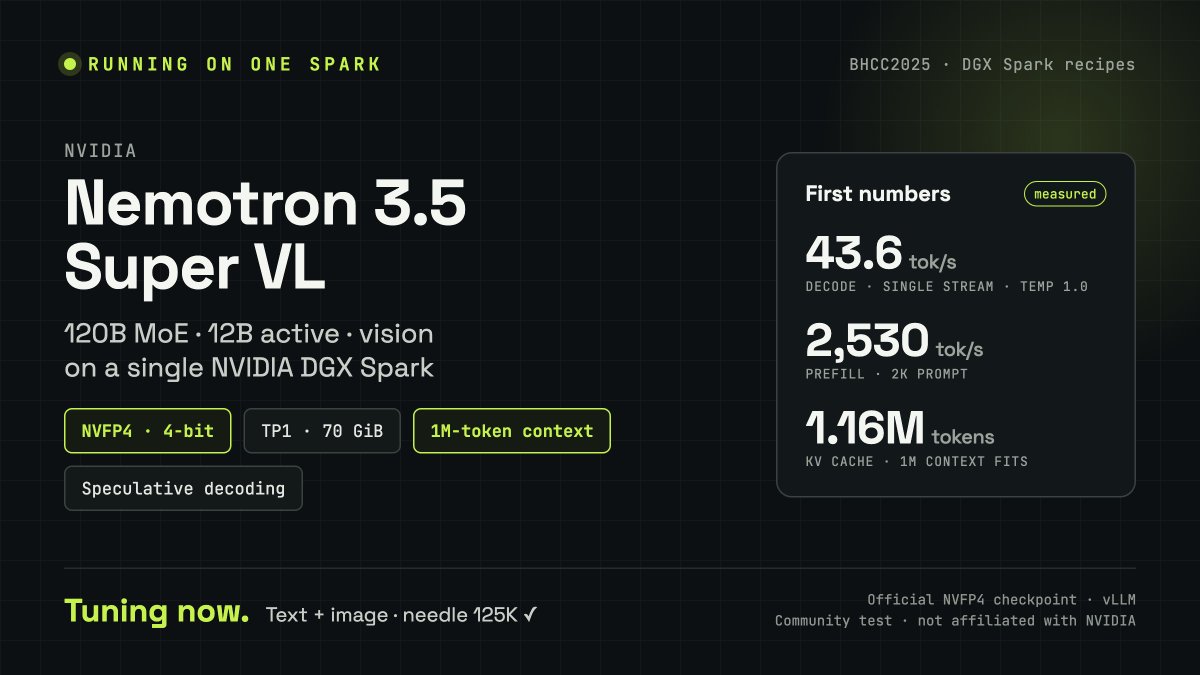
Nemotron 3.5 Super VL (120B MoE, 12B active, vision) running on a single DGX Spark. Official NVFP4 checkpoint, vLLM + speculative decoding.
First numbers: 43.6 tok/s decode, 2.5K tok/s prefill, 1M-token context fits.
Concurrency and tuning next, recipe to follow.
I’m gonna give this a try. Claude was arguing with me about this that it wasn’t gonna make any difference until I showed him this post.
And then he said “oh that’s real data… and I should correct something I said earlier…”
That’s why I push back on these models - it’s what keeps them going forward!
Meet NVIDIA Nemotron 3.5 Super VL
Our new open model combines reasoning and tool use with text, image, document, and video understanding for long-running AI agents.
120B total parameters with 12B active 🧵
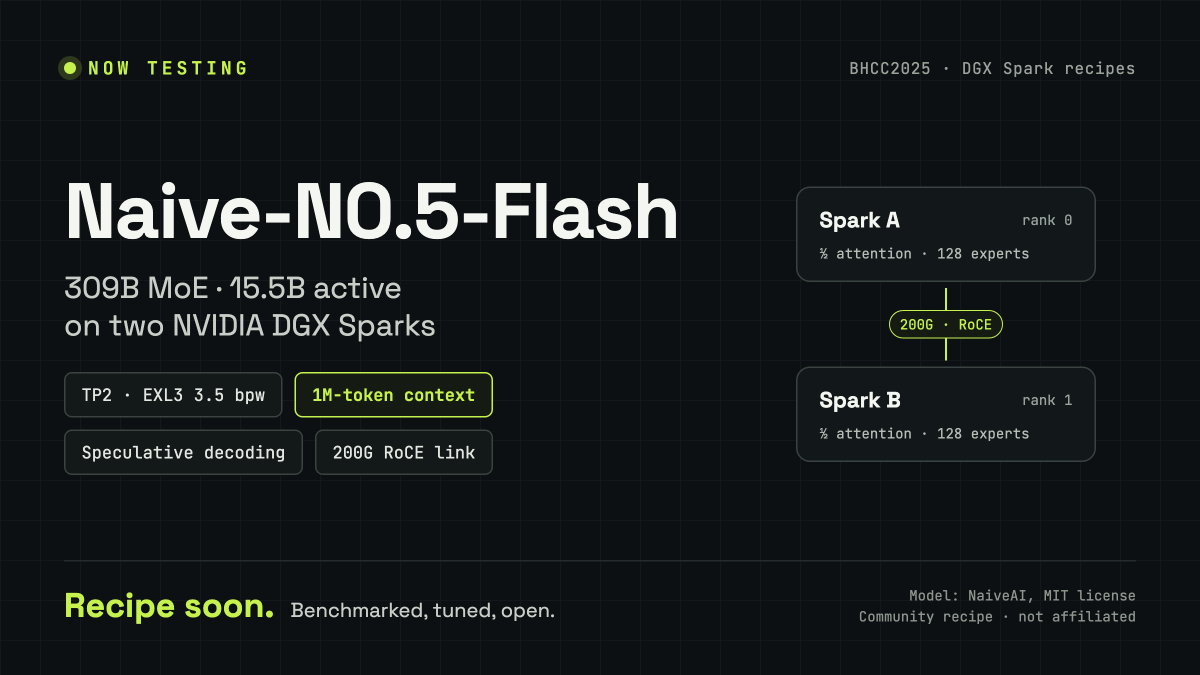
Now testing: Naive-N0.5-Flash on two NVIDIA DGX Sparks 🔬
309B MoE, 15.5B active · TP2 · EXL3 3.5 bpw · speculative decoding · 200G RoCE between the boxes · pushing for the full 1M-token context
Benchmarking and tuning now. Recipe soon.
#DGXSpark#LocalLLM
Running Claude Code inside herdr, pasting screenshots into the prompt just doesn't work.
So I built a Claude Code mod: /shots
Newest screenshot is pre-selected, number keys pick more, Enter drops them into the prompt. Works with any screenshots folder.