4/ The real difference: Intelligent UI lives inside ChatGPT. The open stacks let you ship it in your own product, with your own design system and any model.
"Software adapting to people" shouldn't only happen inside one app.
1/ OpenAI just shipped Intelligent UI in ChatGPT. GPT-6 now answers with charts, forms, calculators, even games, streamed from a native component library.
Impressive. But you can already build this yourself, open source 🧵
3/ CopilotKit's Open Generative UI makes the opposite bet: the model writes raw HTML, SVG and Three.js into a sandboxed iframe.
Algorithm visualizers, 3D scenes, synths. Wilder output, less predictable.
1/ Today we announce Pleiades, a series of epigenetic foundation models (90M→7B params) trained on 1.9T tokens of human methylation & genomic data. Pleiades accurately models epigenetics for genomic track prediction, generation & neurodegenerative disease detection from cfDNA, outperforming previous pure DNA baselines.
Product Manager guide to product/feature success metrics for product using Generative AI capabilities.
6 categories:
1. Engagement
2. Accuracy and Quality
3. Cost and Time Saving
4. Latency and Responsiveness
5. User Satisfaction
6. Ethics and Fairness
Defining the right success metrics is key to measuring the impact and value of your product. It helps guide decision-making and ensures alignment with user needs and business objectives. #successmetrics#productstrategy
9/9
@jonhainstock@OpenAI@langchain Once the data is stored, figure out the pages/chunks that has the required information (we can makeup a question, use cosine similarity on the pages/chunks). This will give us the required pages which we can pass on to @langchain, Kor, @OpenAI for extraction
I have spent 5 years in designing document understanding systems.
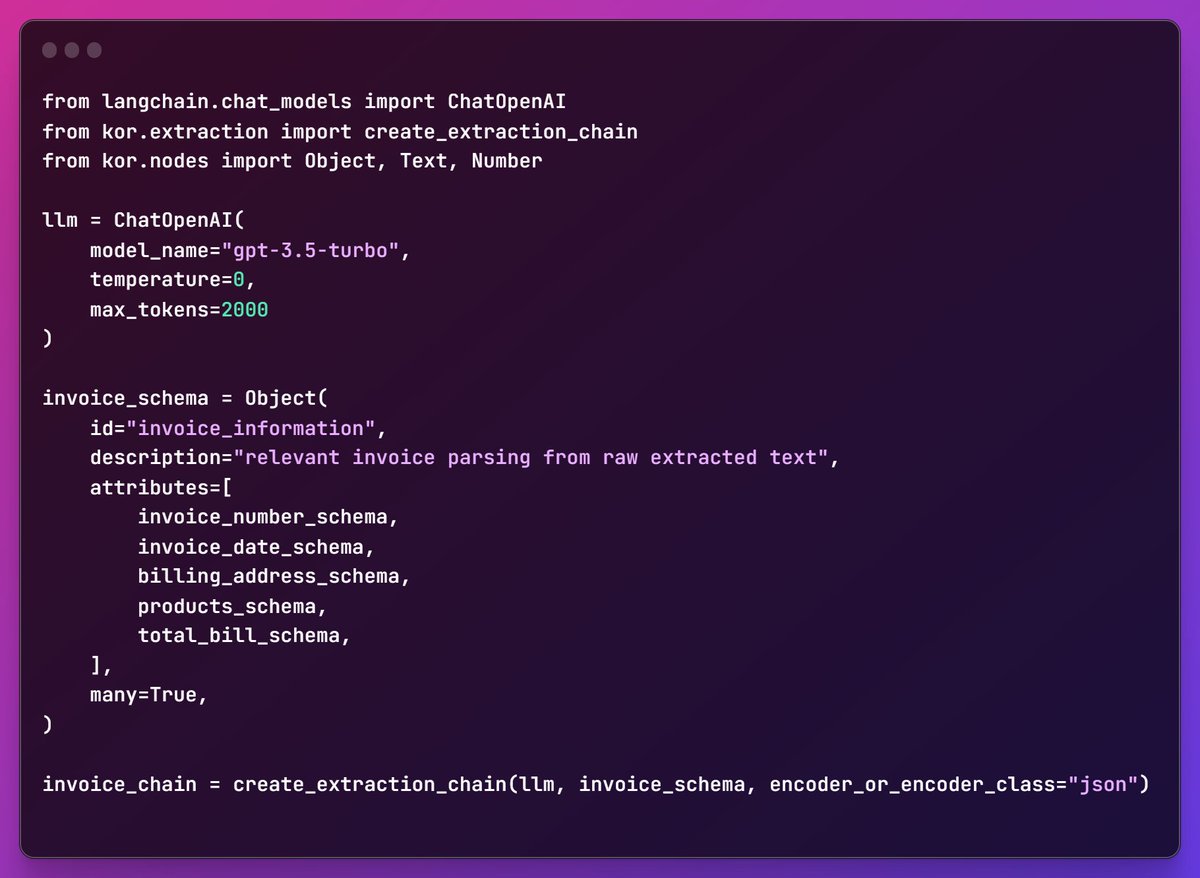
I must say that creating a document understanding and extraction engine from the ground up and getting it to a commendable level has never been this effortless using @OpenAI@langchain
1/3
@jonhainstock@OpenAI@langchain Why the solution works for short documents is because it is certain that the information it is looking for is present in whatever text is extracted.
For long docs, add an interim step that stores the extracted text page wise (or chunks) in a vector db with embeddings (1/2)
The proposed solution scales really well for any type of invoices, receipts irrespective of receipt language (which was a big challenge in itself).
Github: https://t.co/6ei0MszWip
3/3
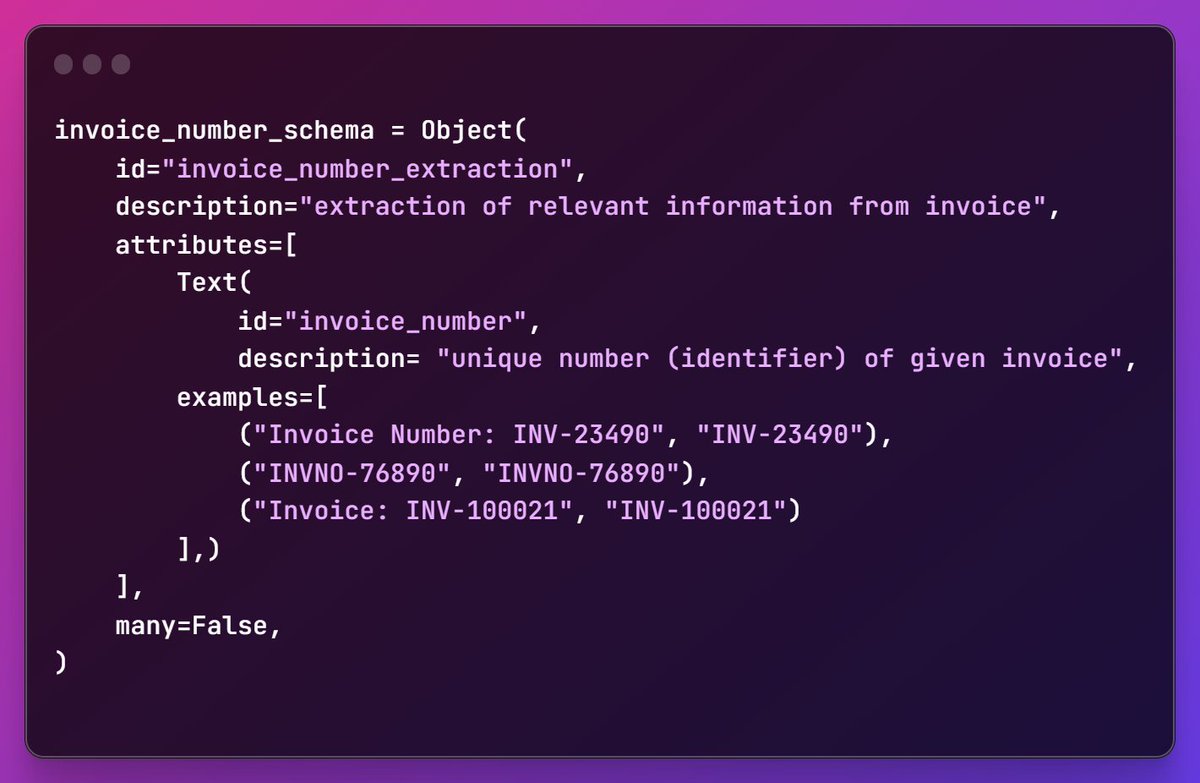
Very simple to define each field by providing a couple of examples (making it a few shot learning problem), rest @OpenAI can take care!
See examples for Invoice number and Invoice date
2/3