First in my bloodline to use a quantum computer
It's easier than you think:
> Create an account at @IBM Quantum Platform
> Create an Open Plan instance and copy its CRN
> Generate an API key from the dashboard and keep it private.
> Install Qiskit and IBM’s runtime package: pip install qiskit "qiskit-ibm-runtime>=0.50.0".
> Build your circuit in Python, connect using your API key and CRN, and select a real quantum computer.
> Submit your circuit, track it under Workloads, and retrieve the measurement results when it finishes
RAG is officially cooked.
IBM built a retriever that hallucinates 65x less than fine-tuned RAG systems.
Right now, every company is using Retrieval-Augmented Generation (RAG) to stop their AI from hallucinating.
The idea is to give the AI a private database to read so it doesn't make things up.
But there is a massive structural flaw.
Standard RAG blindly grabs documents based on vector similarity and forces the AI to read them. If the retriever pulls irrelevant garbage, the AI doesn't stop.
It just hallucinates with citations.
IBM just dropped a paper that changes the math entirely.
They built a new retrieval architecture that hallucinates 65x less than state-of-the-art fine-tuned RAG systems.
65x is the difference between a fun prototype and a production-grade enterprise system.
Instead of blindly dumping context into the model and hoping for the best, their system actively filters and validates the retrieved data before the generation step even begins.
It cuts out the noise. It forces absolute precision.
For businesses, this is the holy grail.
Zero hallucinations means zero liability. It means autonomous agents can finally be trusted with sensitive company data without a human babysitting every output.
RAG is so back!
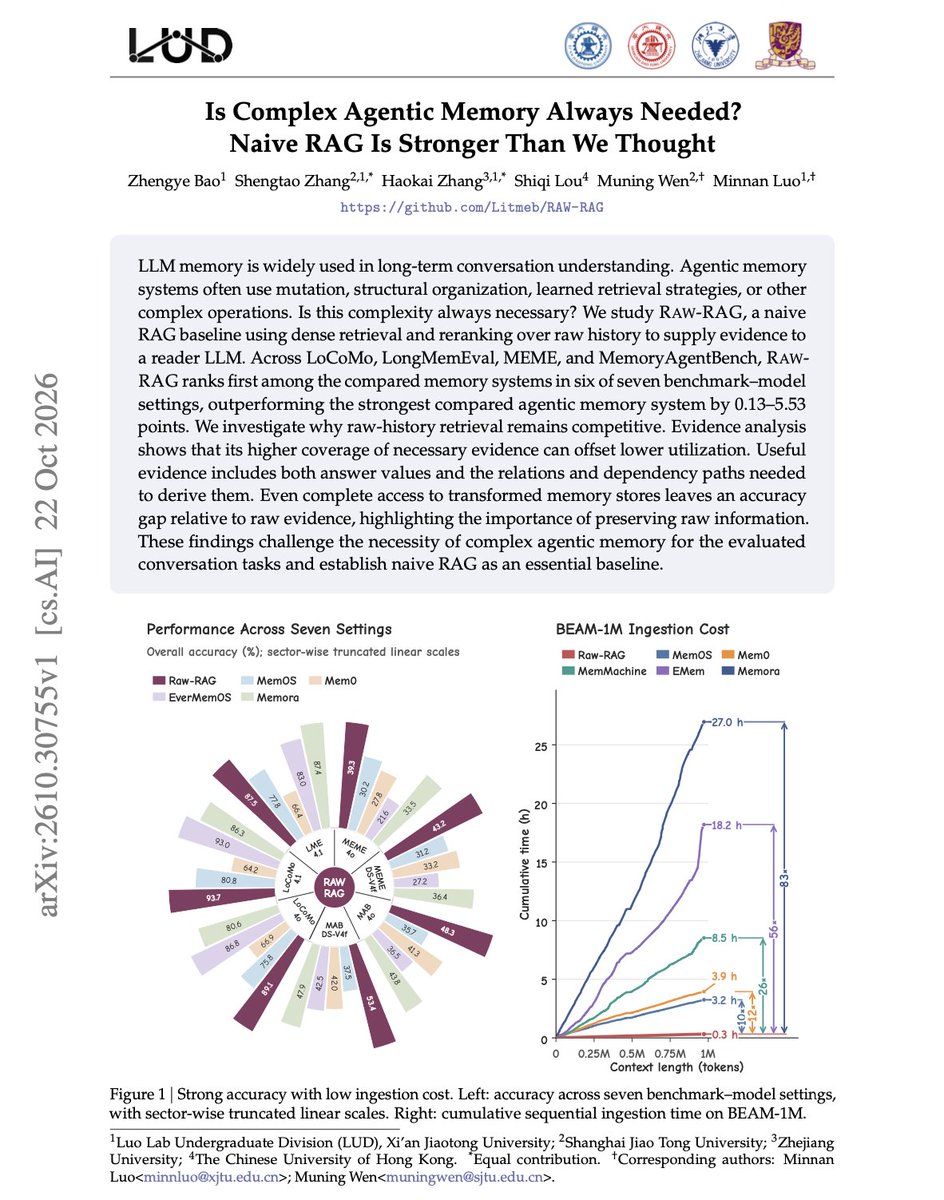
A new paper shows that straightforward retrieval from chat history can outperform much more complex agent memory systems.
The approach, RAW-RAG, retrieves relevant passages from the original conversation, reranks them, and passes the evidence to an LLM.
Across four benchmarks, it ranked first among the compared memory systems in six of seven benchmark–model settings.
The interesting part is why.
An answer can depend on several connected statements, including what changed, when it changed, and which earlier facts it affects. Turning conversations into isolated memories can break those connections.
RAW-RAG supplied enough evidence to answer more often. Even improved access to the transformed memory stores left an accuracy gap compared with raw evidence.
Preserving the original conversation keeps more of those relationships available for retrieval.
For these memory tasks, that makes simple RAG a baseline that more elaborate systems should have to beat.
paper: https://t.co/HDpy6bkICv
On a related note, I wrote about how observations in agent memory connect facts across conversations to surface patterns an agent can act on. If you’re building agents, you might find that article useful. It’s quoted below.
Got selected as one of the Top 100 Fellows globally for @nexfellow Fellowship 2026.
8 weeks to build a product, work with a mentor, and deploy a MVP.
Supported by @osconnect1 and @adaption_ai.
I'm going to ETHGlobal Mumbai @ETHGlobal!
Use my referral link below to earn a discount on your stake!
Link: https://t.co/Hq0plqlBhj
https://t.co/Hq0plqlBhj
Mumbai, we're here.
Getting ready for the AWS Student Builder Mixer and excited to meet a bunch of builders from across the city.
If you're into communities, open source, hackathons, startups, or just like meeting interesting people, come find us.
Let's catch up and talk communities.
The right order for learning AI engineering in 2026.
What most people do:
→ Jump to agents
→ Skip foundations
→ Ignore MLOps
→ Wonder why nothing works
What this roadmap shows:
1. Foundation (Python, APIs, clean code)
2. Semantic intelligence (embeddings, vector DBs)
3. RAG (grounded outputs)
4. Agents (autonomous workflows)
5. MLOps (CI/CD, containers)
6. Evaluation (metrics, drift, bias)
7. Inference optimization (quantization, caching)
8. Portfolio
9. Specialization
The sequence builds on itself. Skip steps and you'll hit walls later.
Btw, DataCamp has opened 680+ courses for free from June 1-7. Worth exploring.
https://t.co/vi6gtDZS66
Image credits - @agenticgirl (Follow her)