Token Forecaster is a tool that predicts LLM output length while you type, then shows whether the reply is running long as it comes in. It lives in the terminal, the Mac menu bar, and the browser.
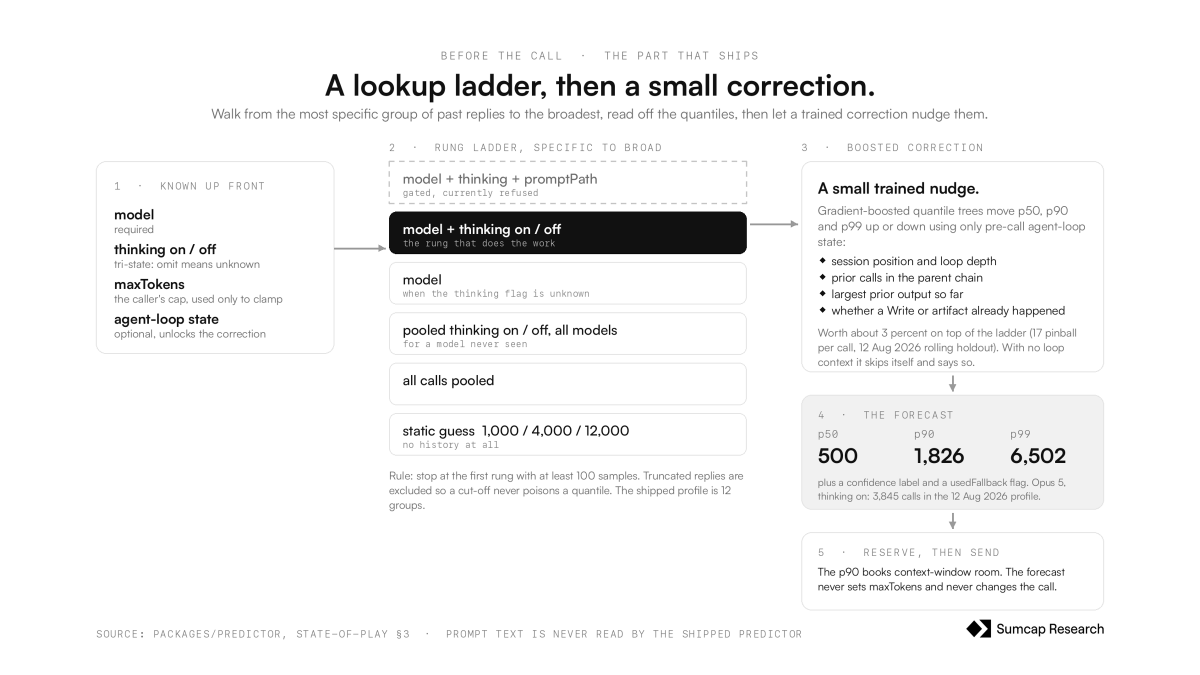
Underneath, it groups replies by model and thinking mode, backs off when data is thin, then adjusts from agent-loop state: depth, prior calls, whether a file was already written.
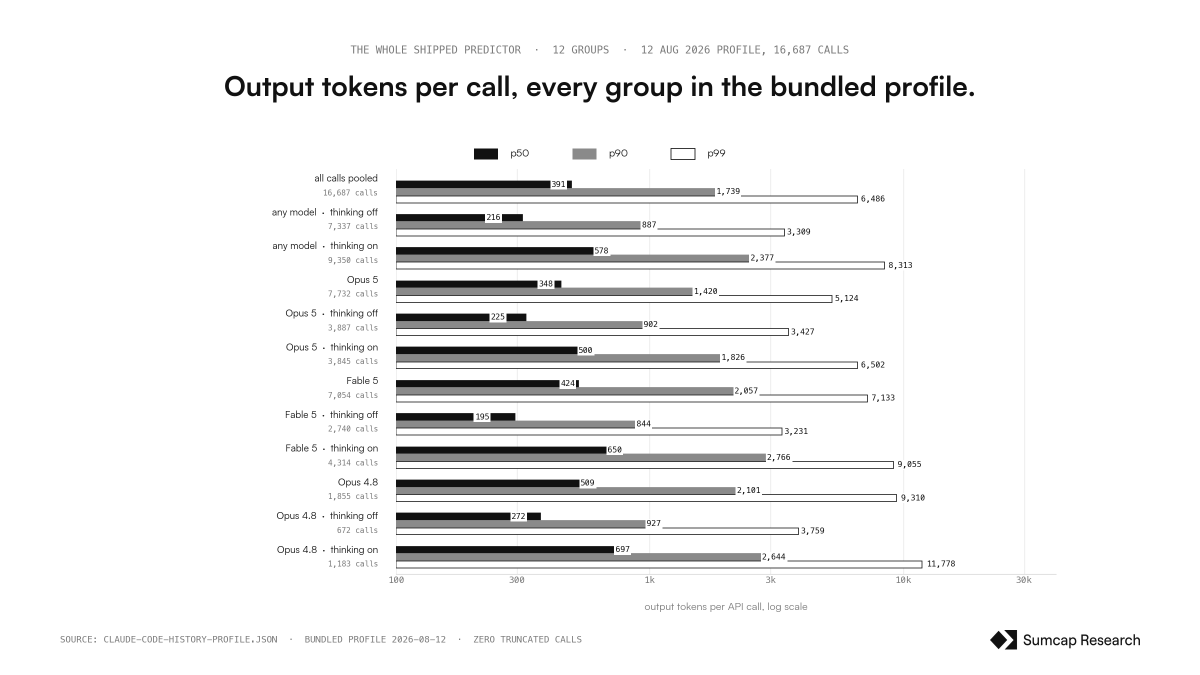
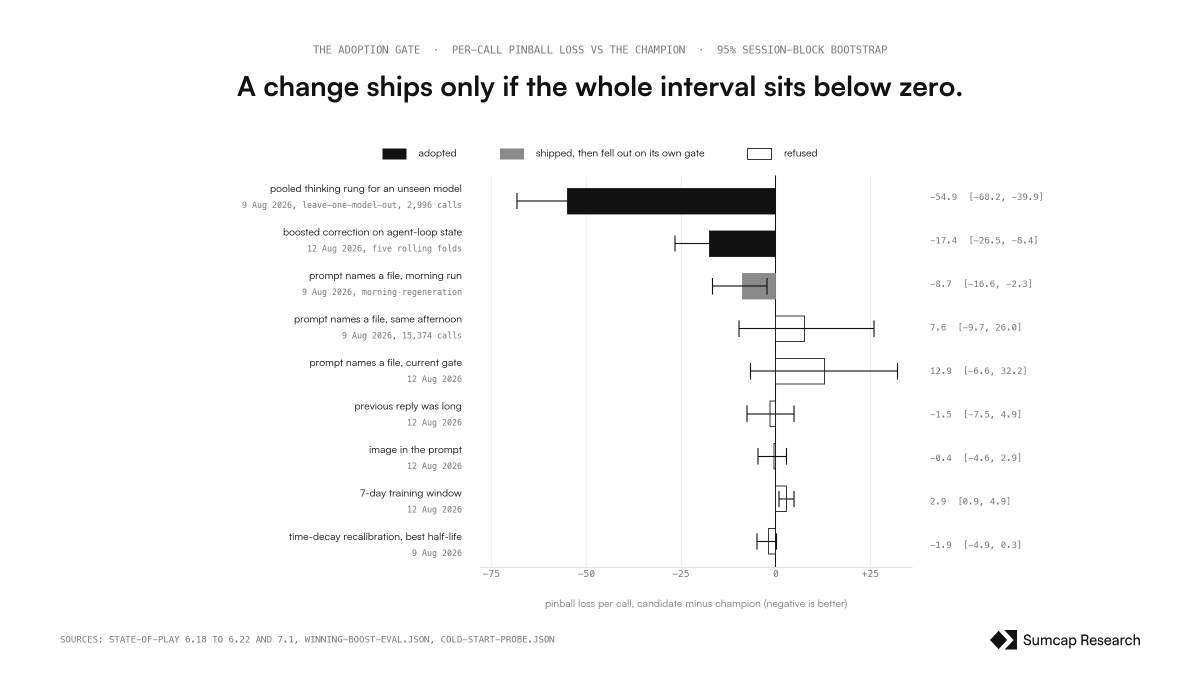
The setting that mattered most was thinking mode: it moved the tail 2.5×. On 4,146 held-out calls from unseen sessions, the 9-in-10 line held 90.6%.
So yes, output length is forecastable. In our data, most of the useful signal came from the model, the thinking mode, and what the agent had already done, more than from the prompt itself.
Estamos a oferecer um EA Sports FC 24 para plataforma à tua escolha! Só tens de:
➡️ Seguir @B24Esports e @solverdept
➡️ RT neste tweet
➡️ Identificar um amigo nos comentários
Great news!
We are proud to announce that Hash Game Store will be present at @WebSummit as an Alpha Startup!
The biggest tech conference in the world will be the perfect opportunity to introduce our project.
We are excited to meet you all!
#WebSummit#web3#gaming#startup
We were just two little kids from Normandy with an impossible dream. Welcome to the Alpine family Pierrot, let’s make our team and our country proud 🇫🇷
On était juste deux gosses en Normandie avec un rêve qui semblait impossible.🇫🇷 Bienvenue dans l’équipe Pierrot. @AlpineF1Team