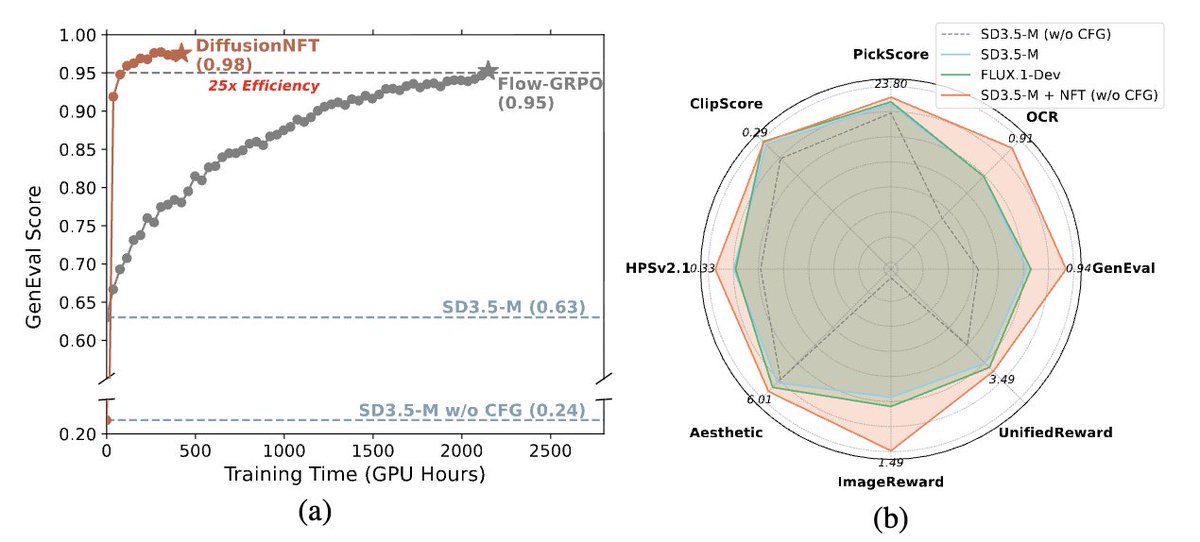
We propose DiffusionNFT, which outperforms conventional Policy Gradient algorithms like GRPO by 3-25 times. I am confident this is the future of online Diffusion RL paradigm. Check it out!
1/ Excited to share the latest work with @chenhuay17!
We propose DiffusionNFT, a new online diffusion RL paradigm that optimizes directly on the forward diffusion process.
Paper: https://t.co/oacDQZua6I
Code: https://t.co/4UBx26TOyz
Check out @haotian_yeee's work on regularized video diffusion RL. It is amazing how simple data regularization turns out to be so effective in preventing hacking problem and boost quality.
🤔Want a principled way to RL your diffusion model?
Check Data-regularized Reinforcement Learning (DDRL)! Post-train @nvidia#Cosmos World Foundation models with a million GPU hours! 🤯
Novel formulation ➡️ Theoretically integrates SFT into RL ➡️ Robust to Reward Hacking 🛑
Details: https://t.co/1A9q8ho2xb
#DDRL #Diffusion #RL #NVIDIA #Cosmos
🚀Try out rCM—the most advanced diffusion distillation!
✅First to scale up sCM/MeanFlow to 10B+ video models
✅Open-sourced FlashAttention-2 JVP kernel & FSDP/CP support
✅High quality & diversity videos in 2~4 steps
Paper: https://t.co/xZZK25oIrJ
Code: https://t.co/aPAo1MO0JQ
Looking for an RL algorithm for improving your diffusion models? DiffusionNFT might be able to help. Check it out.
https://t.co/HFiouCWdJD
25x more efficient than FlowGRPO and gives you SOTA results on various benchmarks.
with @chenhuay17@zkwthu@qsh_zh@Haoxiang__Wang@haotian_yeee
@_akhaliq Thank you for posting our work! Several unique features of NFT besides superior performance.
1. Allow any black-box solvers inlcuding ODE.
2. Only store clean images.
3. CFG-Free formulation throughout training, easily surpass CFG performance.
https://t.co/TuvpEeTXV0
This is a joint work between NVIDIA, Tsinghua, and Stanford. Many thanks to @zkwthu for leading the project , and @haotian_yeee@Haoxiang__Wang@qsh_zh for collaborations.
We propose DiffusionNFT, which outperforms conventional Policy Gradient algorithms like GRPO by 3-25 times. I am confident this is the future of online Diffusion RL paradigm. Check it out!
1/ Excited to share the latest work with @chenhuay17!
We propose DiffusionNFT, a new online diffusion RL paradigm that optimizes directly on the forward diffusion process.
Paper: https://t.co/oacDQZua6I
Code: https://t.co/4UBx26TOyz
DiffusionNFT: RL for diffusion models via the forward process
• Contrastive fine-tuning: positives vs negatives → implicit policy improvement
• Works with any solver, no CFG, no trajectory storage
• 25× more efficient than FlowGRPO
• Boosts SD3.5-M: GenEval 0.24 → 0.98 in 1k steps (vs 5k for FlowGRPO)
🌟 MOST comprehensive & up-to-date Efficient Attention Methods Survey !
🚀 A Survey of Efficient Attention Methods: Hardware-efficient, Sparse, Compact, and Linear Attention
Paper Website: https://t.co/lNOqtP6lAH
GitHub: https://t.co/yfMdCZNo2d
pdf: https://t.co/95t8SYaubP
So many works talking about entropy, but what is the **mechanism** of entropy in RL for LLMs? 🤔
Our work gives a principled understanding, as well as two tricks that get entropy **controlled** 🧵
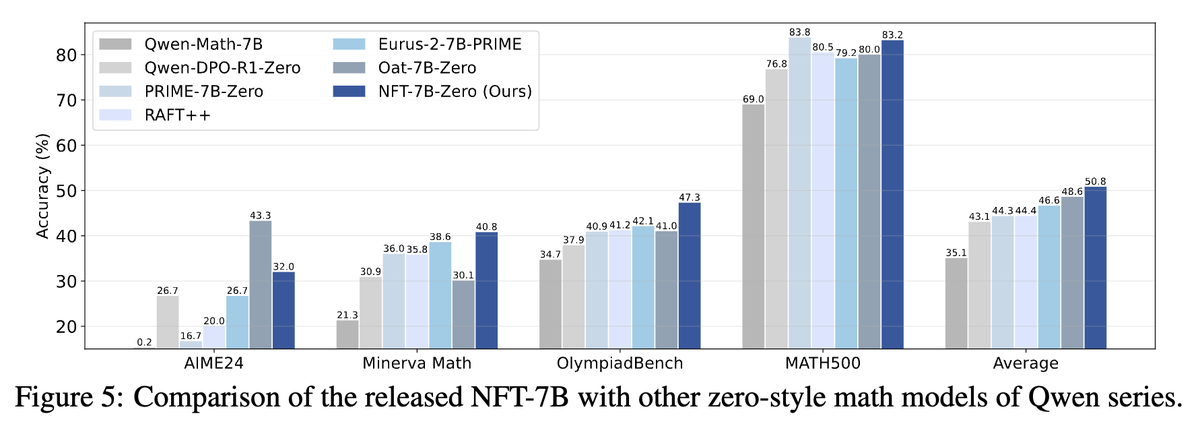
@hendrydong@hendrydong really hope to share with you our recent work, closing the gap between raft and rl methods like grpo by allowing learning from negative data. We find raft++ is strong baseline, while additional negative feedback further boost
its performance
https://t.co/36RVzoFzI5
Is self-improvement exclusive to RL?
Can we use supervised learning to match LLMs trained with SOTA RL algorithms?
In Negative-aware Fine-Tuning (NFT), we introduce a purely supervised learning method to enhance LLMs' math reasoning with no external teachers. NFT matches or even surpasses leading RL-based methods such as GRPO and DAPO on both 32B and 7B models.
https://t.co/GKNtpeRUxL
https://t.co/T61VdfBuHD
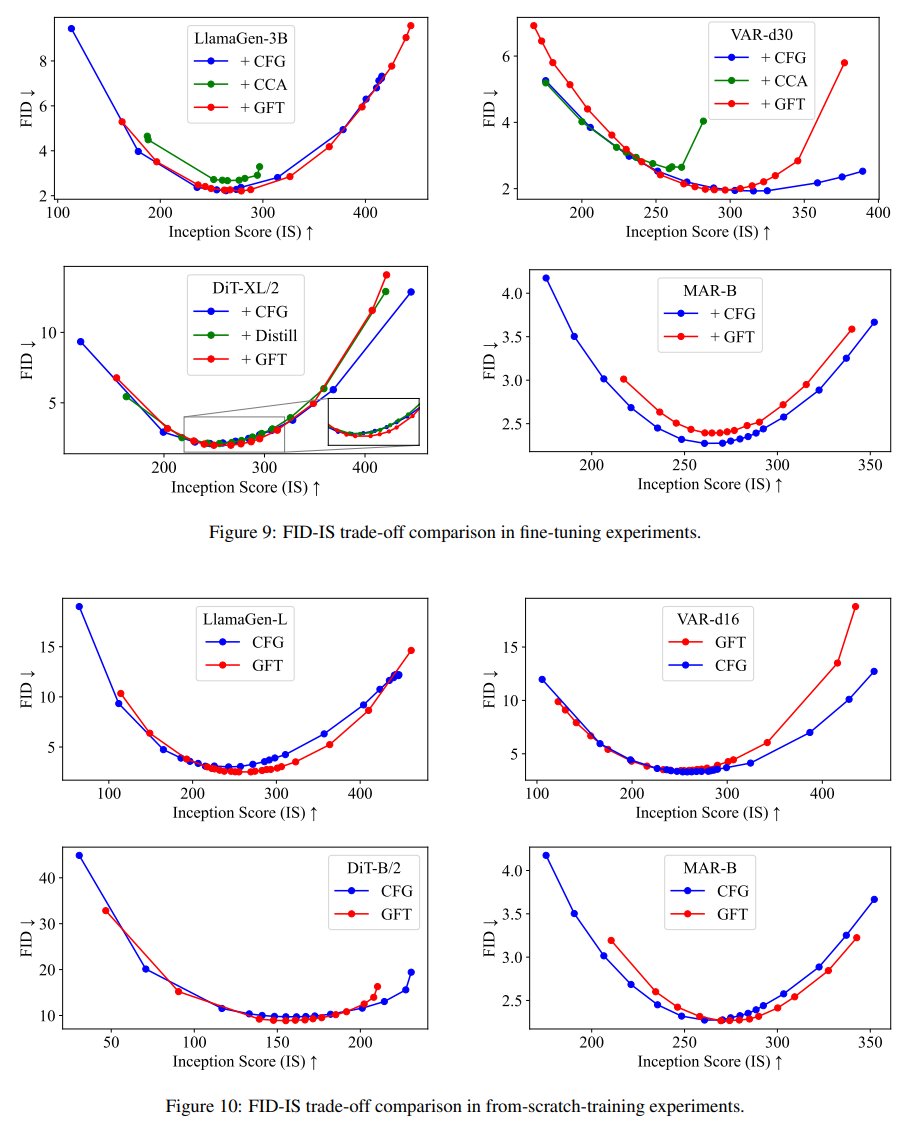
Guidance-Free Training
Add <10 lines of code to achieve guidance-free visual sampling.
Same or even better performance with CFG on 5 distinct models across diffusion/AR/masked. Support from-scratch training. Require no extra GPU memory.
Check out https://t.co/MlUspZoNQc
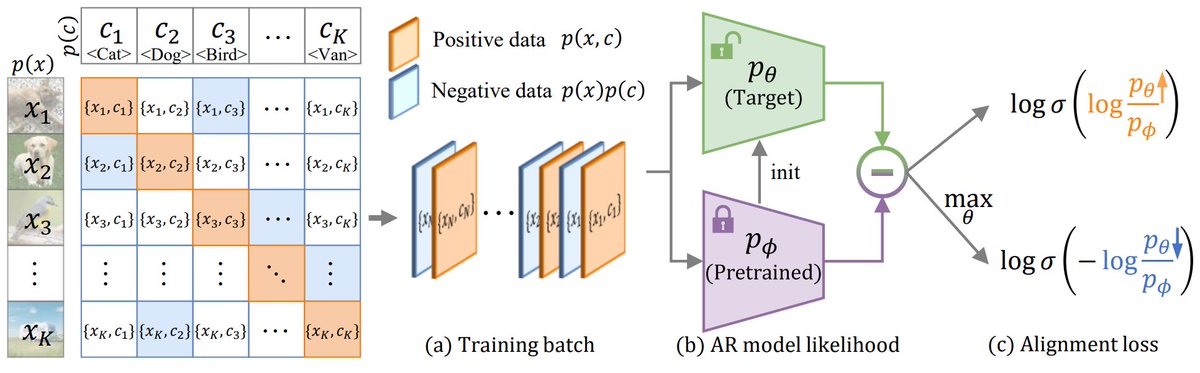
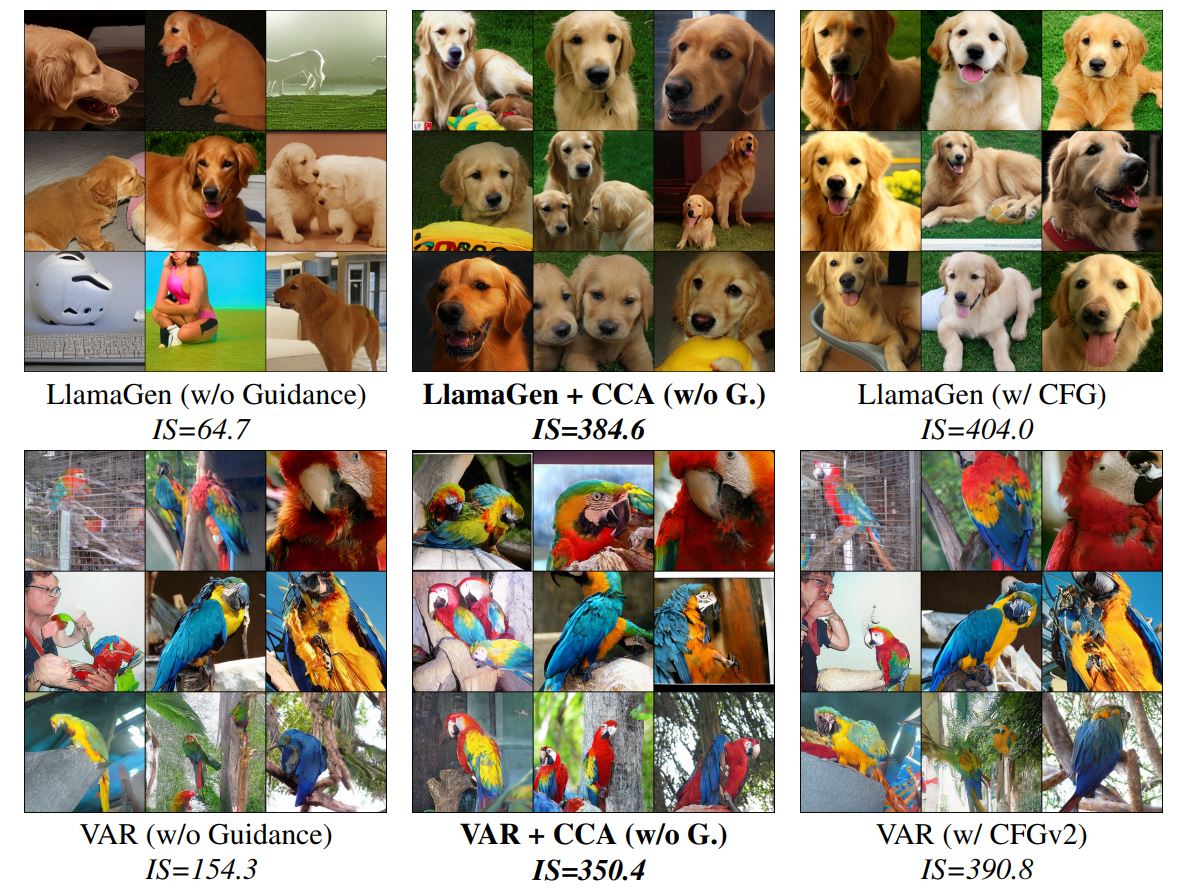
Introduce our recent work.
Toward Guidance-Free AR Visual Generation via Condition Contrastive Alignment
https://t.co/TfDIcRZRxr
CCA vastly improves fid/is performance of pretrained autoregressive visual models by only 1 epoch of fintuning. Requires only pretraining data.