@kalomaze Would be interesting to compare to this: https://t.co/JbbnVDPasi
All tokens of all BPE tokenizers on the HF hub. (Though we do need to rehydrate with new tokenizers)
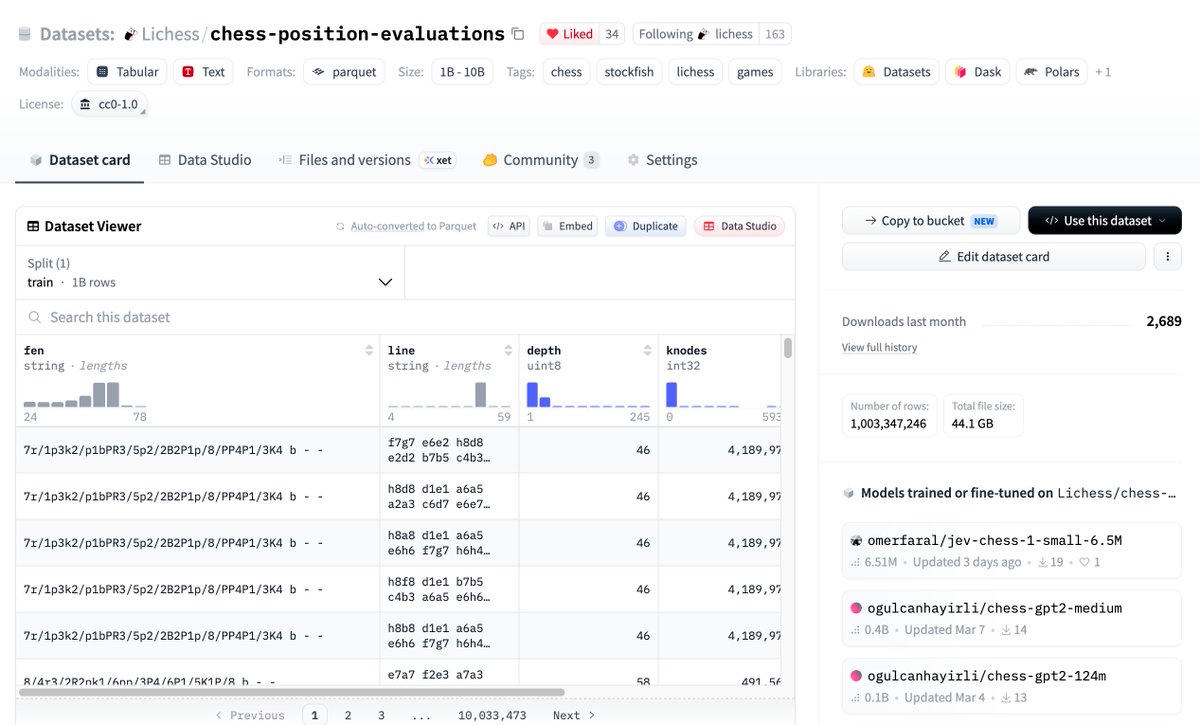
The @huggingface version of our chess position evaluations dataset just crossed 1 billion rows. That's 1 billion @stockfishchess evaluations from games played on @lichess!
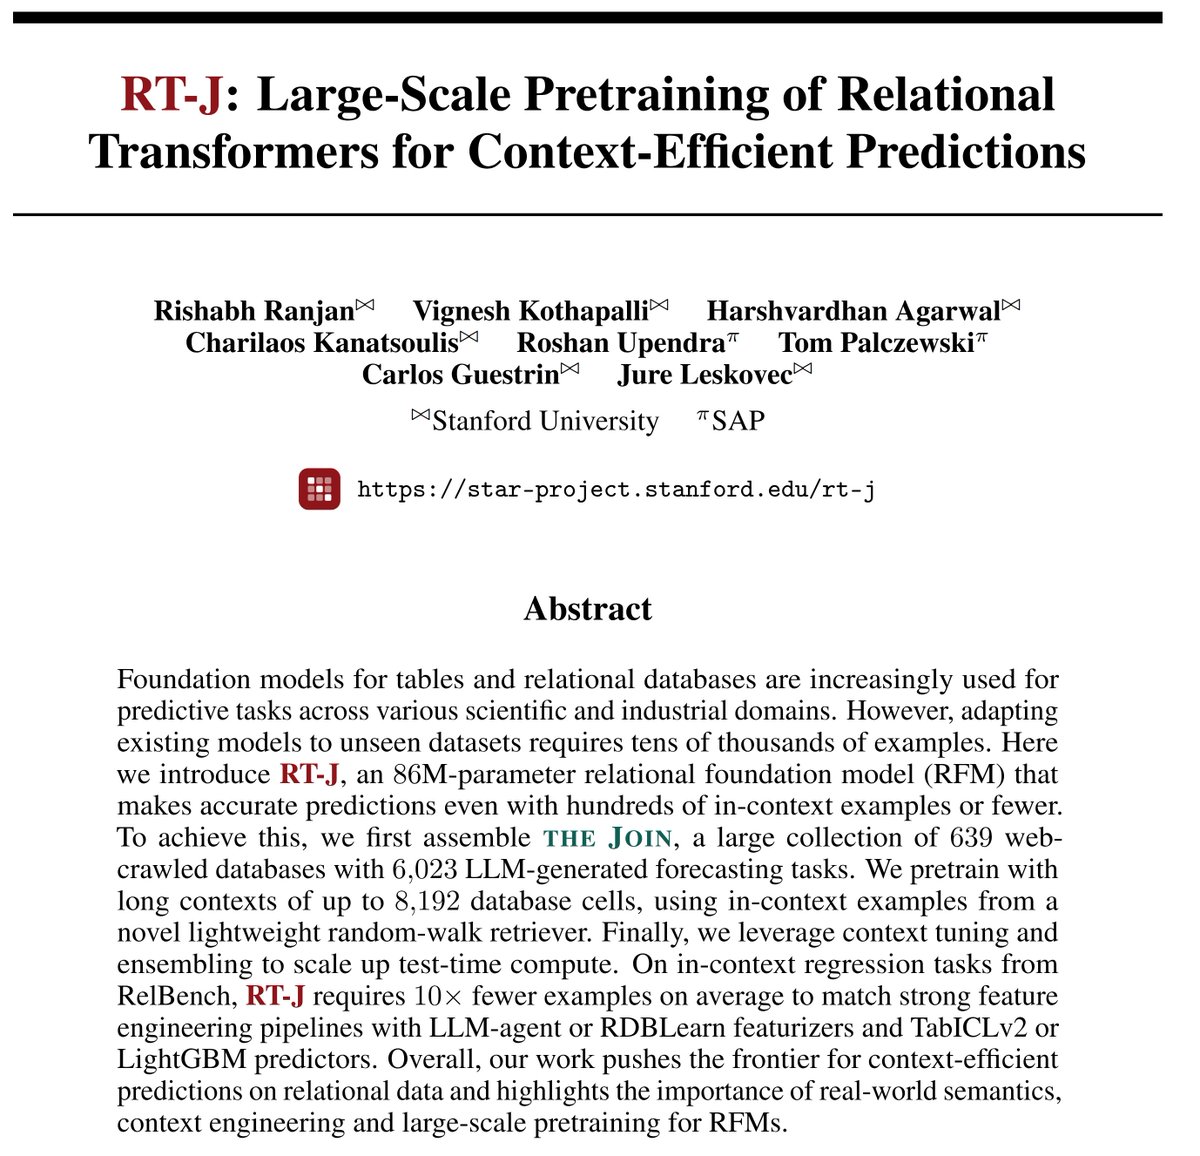
Interesting release by @jure Leskovec's group: RT-J (86M "relational transformer" ) and THE JOIN, a web-crawled corpus of 639 relational databases with 6K forecasting tasks. (data and models on @huggingface)
Everyone wants those AI scientists! But how possible is it for an LLM to generate novel research ideas rather than just optimizing hyperparameters (broadly construed)?
Building directly on the once novel work of @SchmidhuberAI!
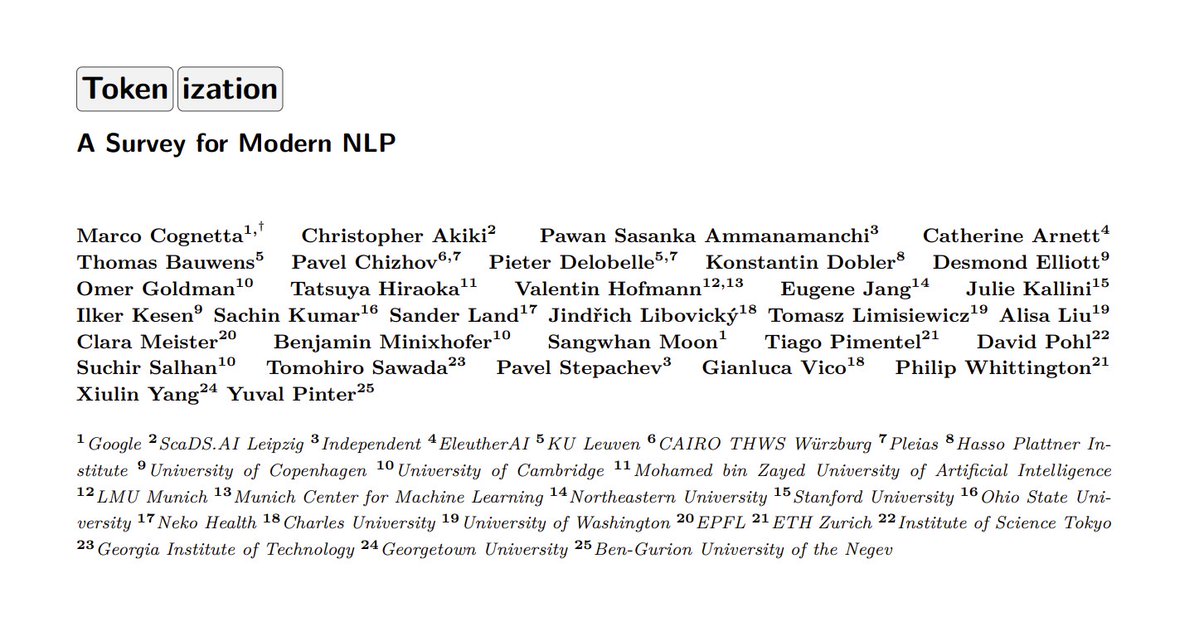
🚨 [Token][ization] Paper Alert 🚨
Tokenization is a wildly understudied area of language modeling despite it having effects across all of NLP. Over the past ~8 months, 32 (!) tokenizer researchers put together the most comprehensive survey of the field. Check it out!
@leland_mcinnes@lu__jasper This looks insanely cool. Is this happening in a branch you could link to? Or in stealth mode?
PS: UMAP never stopped being cool.