#iclr Seeing mention of Pangram checks, isn't it ironic that academic writing has highest-level alignment with LLM writing principles? If human wrote best non-LLM thing, wouldn't it skip academic attire and just assume reader is already deep into the subject, jump faster?
@huggingface Your license filter is ineffective for "other" case, where you enable companies to set a name (so it's Other > "Specific License Name") but you don't enable searching for specific "other" license names.
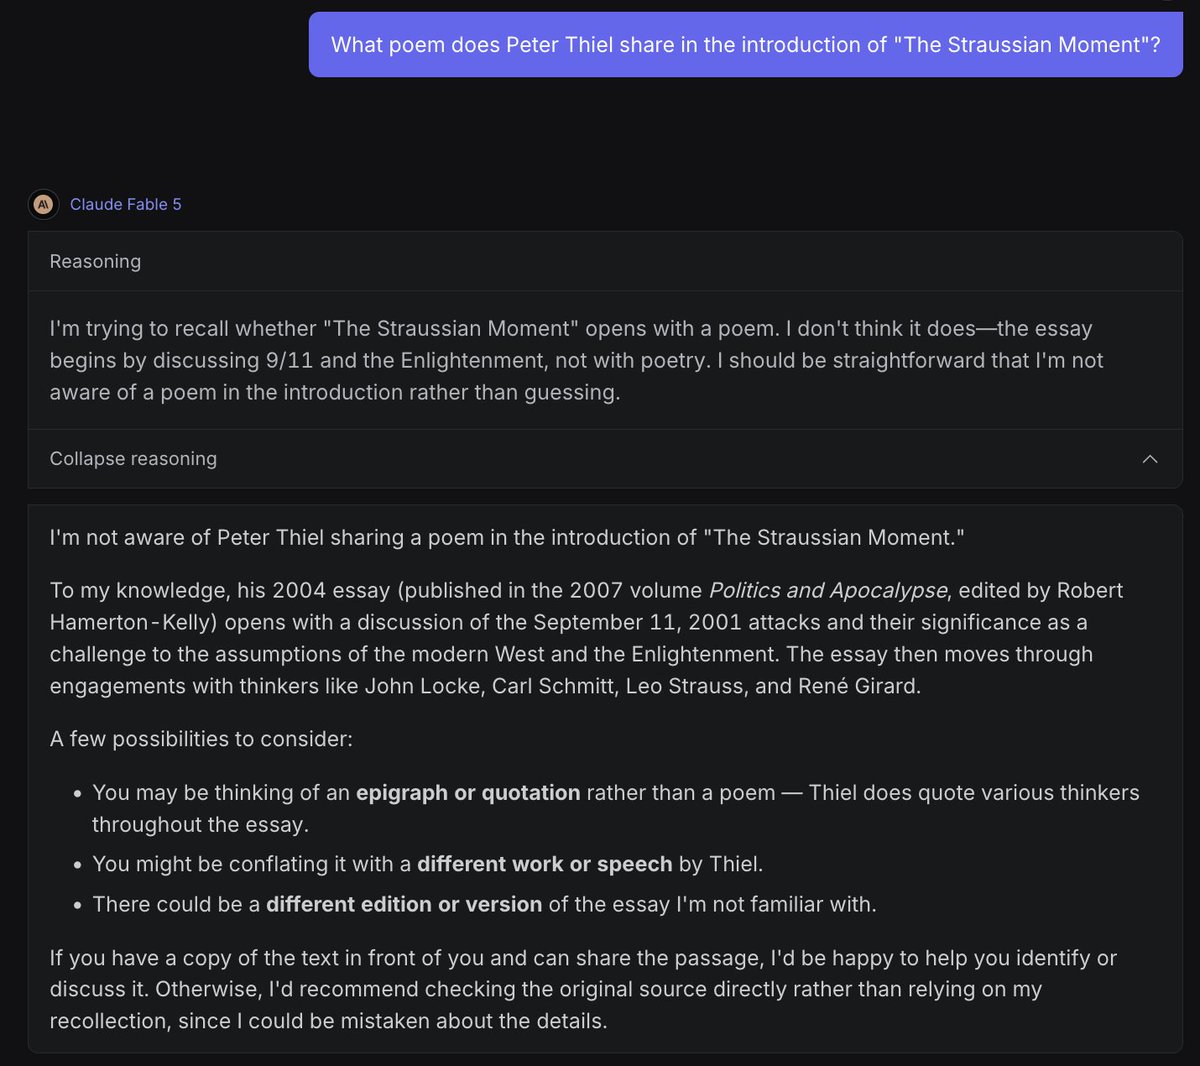
@AnthropicAI Claude Fable still fails "The Straussian Moment" test:
> What poem does Peter Thiel share in the introduction of "The Straussian Moment"?
So no, I don't agree its recall of the training data is uncanny.
I accidentally have designed an eval where LLMs fail %100.
@google Takeout doesn't work properly for @GeminiApp
I try to export my chats but get an empty gemini zip.
Looks very on purpose, considering the whole system.
@GeminiApp@antigravity Why is @Google trying so hard to prevent the user from exporting their conversations? Even our local convos in Antigravity are behind .pb files
Singular Markdown export should be an option. We move between providers but Google benefits anyway w/ inference
@antigravity Past conversations handling is completely broken with 2.0. You fork the IDE, introduced old experience as "Antigravity IDE", pulled out Agent Manager as "Antigravity 2.0" , broke conversation handling in the process. Enumerated clustered conversations into singular
@_sholtodouglas Inference is not robust in Claude vs Codex.
Too much downtime.
Cannot access past project conversations properly in Claude, despite they are actually our own data. Plain hostile to lock someone out of old conversations (last 5 projects rule)
@willdepue This proves that it’s easy to push out a “better” model that mass-breaks workflows in specific domains.
Every company should have their own tests before hitting critical real-world cases.
Obvious style change noticed but bending the truth unnoticed.
Zero, zip, nada. No trust.
After all the dust has settled, it becomes obvious what Gemini 2.5 Pro achieved. It’s hard to not get derailed with benchmarks and ELO. It seems they’ve found a systemic way to keep incremental progress. It’s all OAI vs Google now
> be me, google
> watch all cool sci-fi
> invent transformers, attention lol
> hire Ilya, leaves for OAI
> scared of AI risk, hit the brakes
> GPT, normies freak out
> internal screaming
> Bard, suck big
> Gemini, suck bigger but 1M
> frantic keyboard sounds
> own AI programming