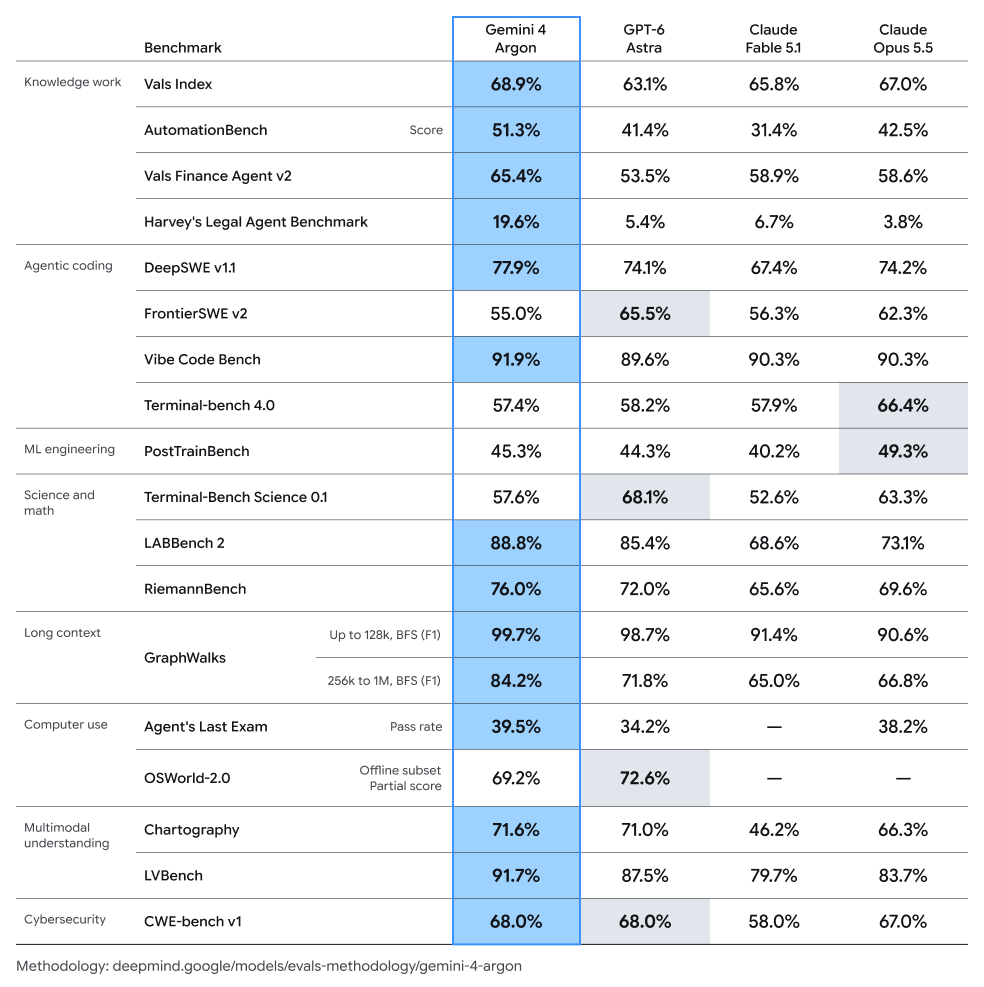
Gemini 4 Argon 👀🔥
91.9% on Vibe Code Bench and 77.9% on DeepSWE.
The agentic coding results look seriously impressive. Can't wait to try it. @GoogleDeepMind@GeminiApp
Introducing Gemini 4 Argon – our new frontier model.
It’s built for complex workflows across coding, enterprise knowledge work, and cybersecurity defense – rolling out today to a set of trusted testers through our Fairwind Program.
Introducing Claude Sonnet 5.5, the second model in the Claude 5.5 family.
It’s a clear upgrade over Sonnet 5, runs more than 30% faster, and costs up to 30% less for most work.
🎮 Claude Opus 5.5 built a full 3D fighting game! 🤯
I gave it Mixamo characters + animations and asked it to build a playable 3D fighting game. @ClaudeDevs
Full video 👇
https://t.co/G8KDt1HZnR
Create and deploy custom audio with our new text-to-speech models:
🔵 Gemini 3.8 Flash TTS: Design unique voices with distinct accents and characteristics.
🔵 Gemini 3.8 Flash-Lite TTS: Built for efficiency and scale, choose from your created styles or our expansive production-ready library.
Meet Space Bunny Alpha on OpenRouter ⚡
A flash model with fast inference, adjustable reasoning, and a 1M-token context window. It takes text, image, and video input.
Give it a spin and share your feedback: https://t.co/g1XybNcJue
Meet Space Bunny Alpha on OpenRouter ⚡
A flash model with fast inference, adjustable reasoning, and a 1M-token context window. It takes text, image, and video input.
Give it a spin and share your feedback: https://t.co/g1XybNcJue
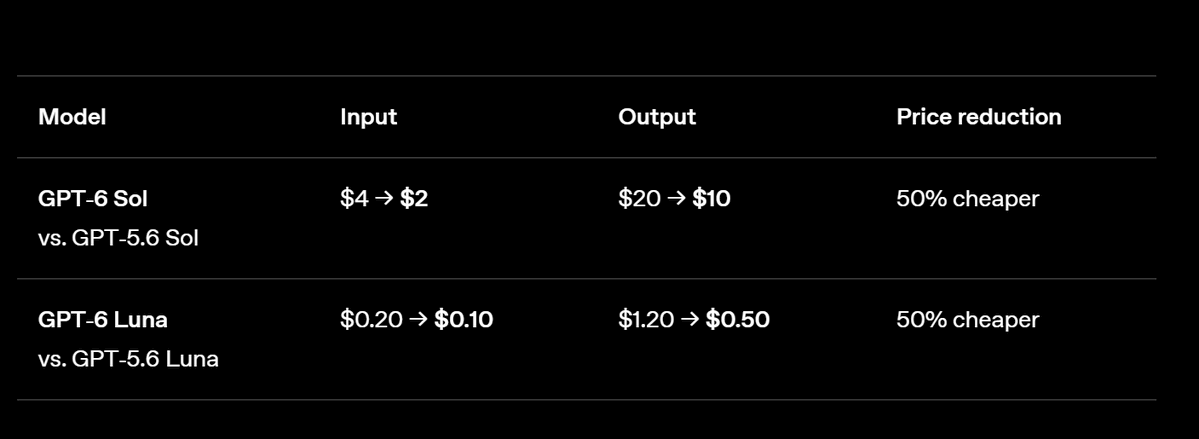
🚨 Introducing GPT-6 Sol & Luna - now 50% cheaper than the previous models!
GPT-6 Sol: $2 input / $10 output
GPT-6 Luna: $0.10 input / $0.50 output
https://t.co/TMFLZEceIg
@OpenAI
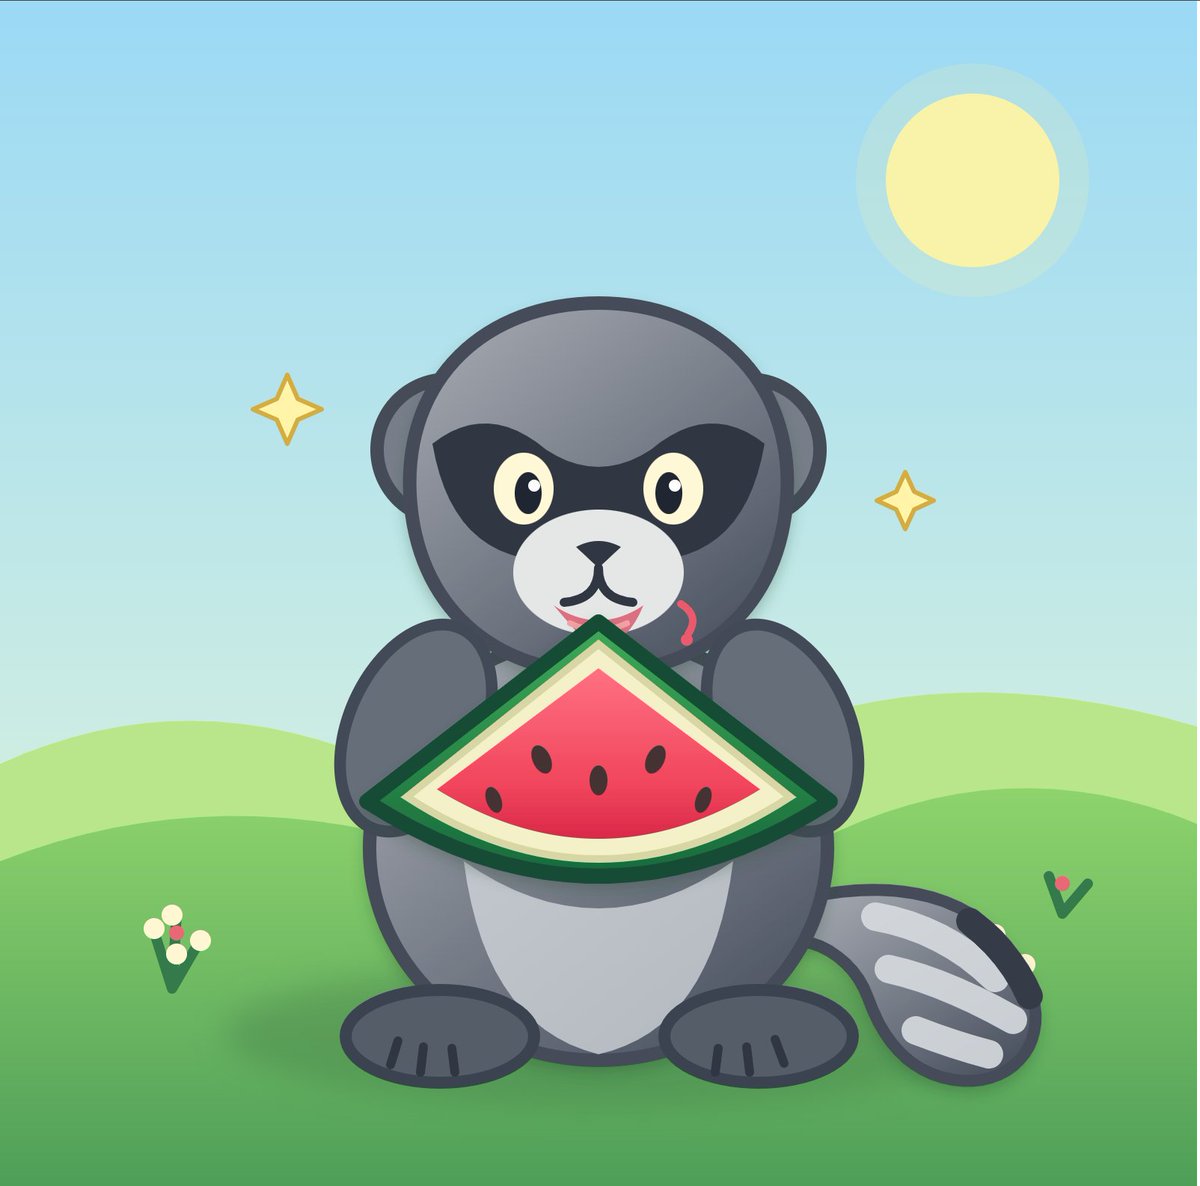
The difference between Opus 5.5 Xhigh and High is HUGE. 👀
Left: Xhigh
Right: High
Same prompt.
Xhigh produced a much more accurate raccoon honestly, I have never seen this level of detail from an SVG generation before. 🤯🔥 @claudeai
Opus 5.5 Medium just beat Fable 5.1 Max on CursorBench. 👀 https://t.co/xD5ycSEB3R
52.5% vs 51.8%
Cost:
$2.91 vs $17.28/task
Higher score. ~83% cheaper. 🔥 @claudeai
🚨 Claude Opus 5.5 hits 58 on the Artificial Analysis Intelligence Index.
That puts Opus 5.5 at the top of the latest leaderboard, ahead of the previous frontier models👀
The gap between the leading models is getting very tight.
Opus 5.5 - 58 🥇
Fable 5.1 - 53
Astra — 53
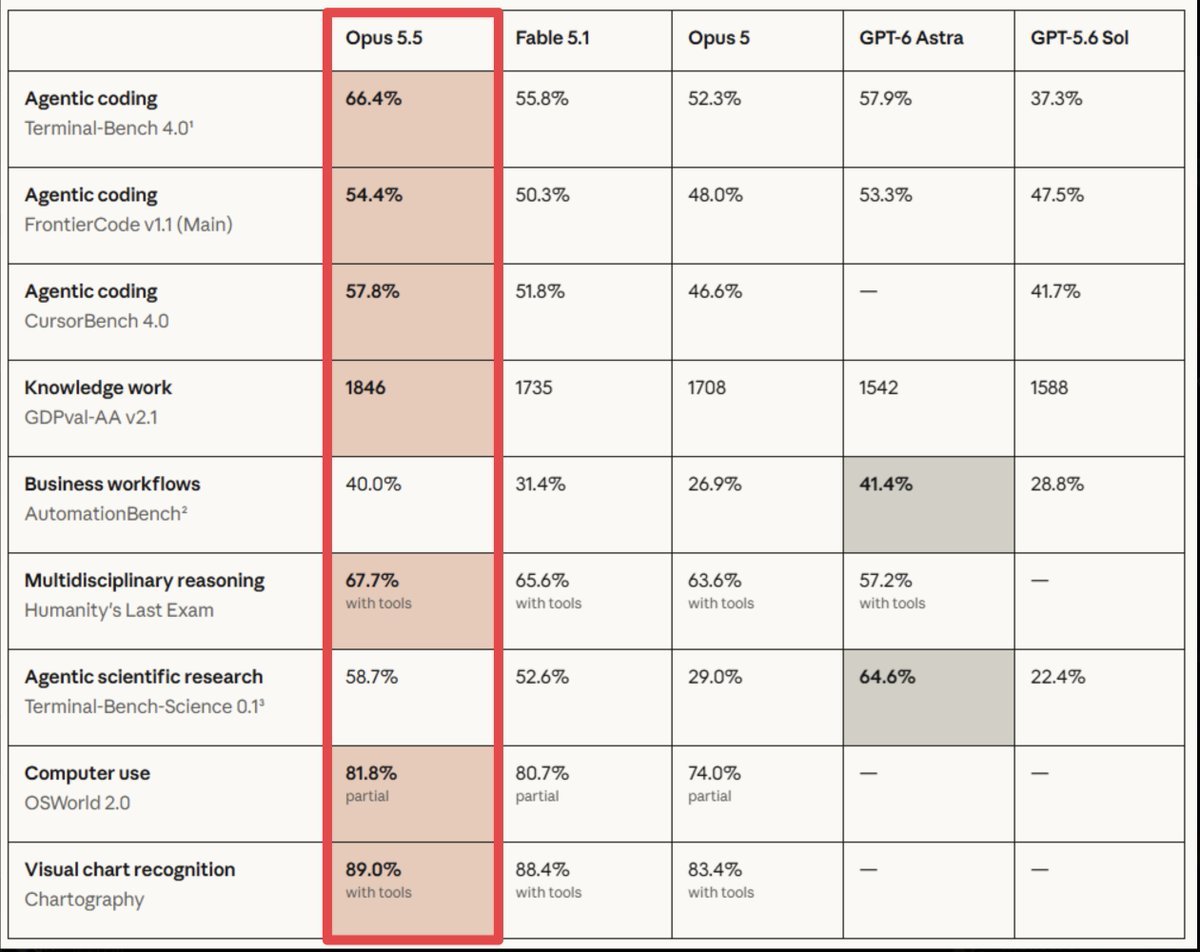
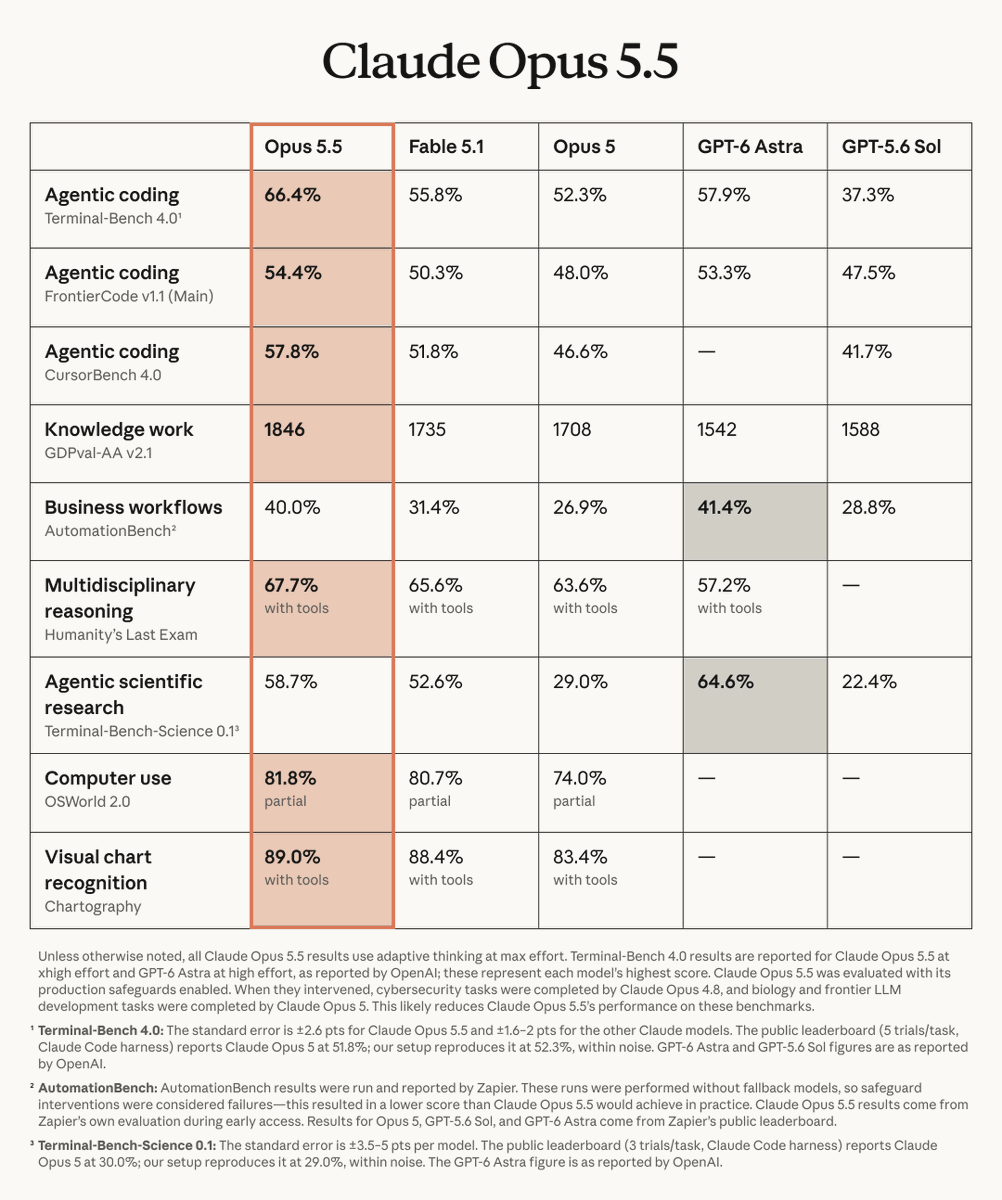
🚨 OPUS 5.5 IS HERE...
Anthropic’s latest model reportedly outperforms
Fable 5.1 and GPT-6 Astra across coding, reasoning, knowledge work, computer use, and vision while costing half as much as Fable 5.1.
@ClaudeDevs@claudeai