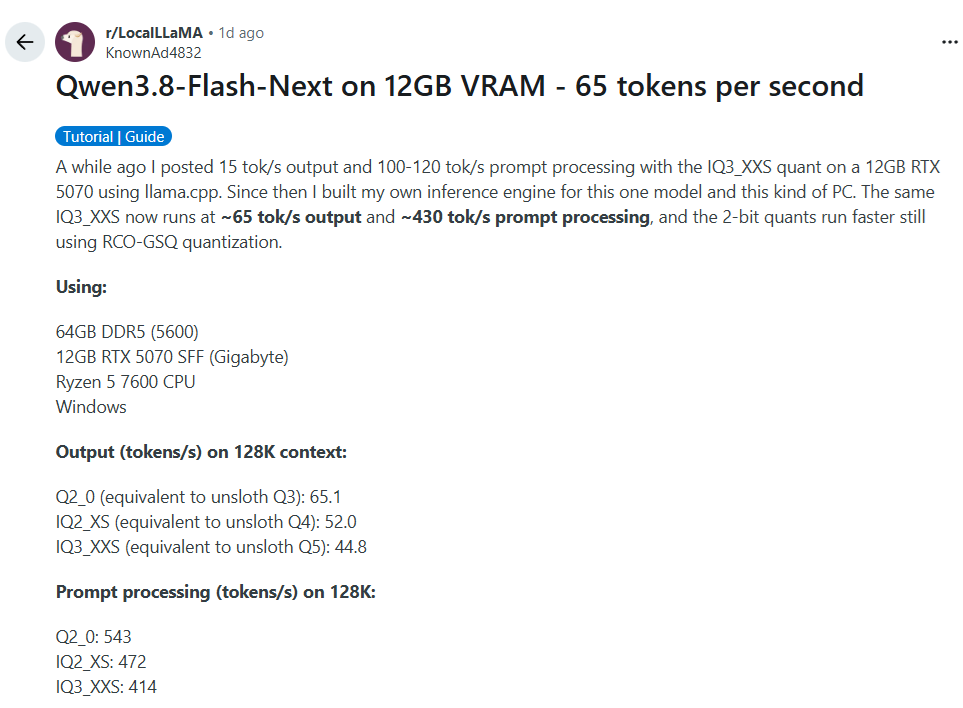
This guy was getting ~15 tps running Qwen3.8-Flash-Next on his 12GB RTX 5070.
Apparently that wasn't good enough. 😂
So he built his own inference engine. (as we all should)
Now he's reporting
🐌 llama.cpp → ~15 tps
🚀 Strata → up to 65.1 tps
And this isn't big workstation either
Specs
🎮 RTX 5070 12GB
🧠 64GB DDR5-5600
⚙️ Ryzen 5 7600
🪟 Windows
At 128K context his new Strata engine reports:
Q2_0 → 65.1 tps + 543 tps prompt
IQ2_XS → 52.0 tps + 472 tps prompt
IQ3_XXS → 44.8 tps + 414 tps prompt
For Qwen3.8-FLASH-NEXT. 👀
He built it specifically around this model and this kind of CUDA + system-RAM setup, paired with RCO-GSQ quants. 👉 And he open-sourced it.
I love these kind of Local AI projects.
🔗 Link in ALT