1/ Can Large Language Models (LLMs) truly reason? Or are they just sophisticated pattern matchers? In our latest preprint, we explore this key question through a large-scale study of both open-source like Llama, Phi, Gemma, and Mistral and leading closed models, including the recent OpenAI GPT-4o and o1-series.
https://t.co/2tv8Pp9MSz
Work done with @i_mirzadeh, @KeivanAlizadeh2, Hooman Shahrokhi, Samy Bengio, @OncelTuzel.
#LLM #Reasoning #Mathematics #AGI #Research #Apple
Le CO2 réellement "sauvé" est celui que l'on n'émet pas.
Mon prochain déplacement longue distance, même si effectué en train, est-il réellement utile et nécessaire ? 🙃🤔
@GroupeSNCF@SNCFConnect@SNCFVoyageurs#TeamTrain
Here is our largest database of PhD fellowships yet: we found 195 fellowships and funding opportunities.
For each fellowship, this searchable database lists description, deadline, amount, and eligibility criteria.
Download it here: https://t.co/1h76jJaHOv
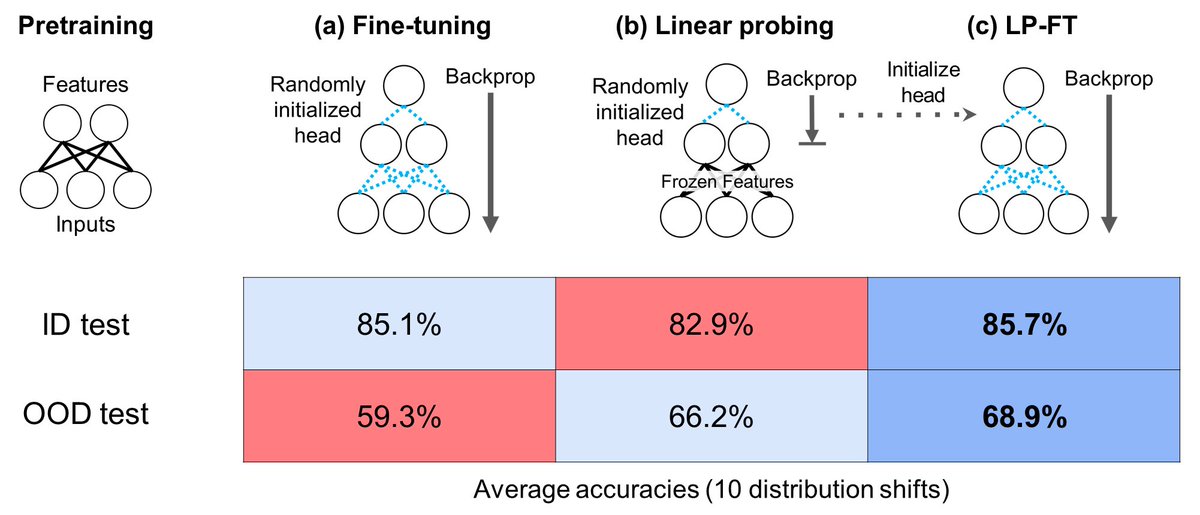
How should you fine-tune a large pretrained model (CLIP, SimCLR) robustly? We find that standard fine-tuning can do poorly out-of-distribution (test data ≠ fine-tuning data). Our analysis leads to a simple fix, higher accuracy on 10 datasets. https://t.co/hyfx9vnAOd (ICLR Oral)
An awesome @geoffreyhinton presenting «The Forward-Forward Algorithm for Training Deep Neural Networks».
A training algorithm that does not require to propagate derivatives or remember neural activities and learns representations of streaming sensory data on the fly. #NeurIPS22
𝗠𝘂𝗹𝘁𝗶𝘀𝗰𝗮𝗹𝗲 𝗯𝗿𝗮𝗶𝗻 𝗺𝗼𝗱𝗲𝗹𝗶𝗻𝗴 as the way to go!
"The quest for multiscale brain modeling", by Egidio D’Angelo and Viktor Jirsa.
How do all scales influence each other??
https://t.co/CMDectjyVw
@TERPays2LaLoire Bonjour, dans le TER 857323 entre Le Mans et Nantes. Il fait super froid (clim à fond). Y at-il possibilité de moduler la clim ? 2 enjeux: 1/ climatique et économie d'énergie 2/ ne pas attraper de rhume en plein juillet. :-)
My first @GoogleAI residency project was accepted to @emnlpmeeting#EMNLP2021!
Prompt Tuning can condition a frozen T5 XXL model to perform new tasks while only adding 0.003% more parameters and no performance loss.
Camera Ready 📸: https://t.co/UMSpXpidmH
Quick Thread 🧵(1/7)
Introducing 𝗔𝗧𝗧𝗘𝗠𝗣𝗧, a new modular, multi-task, and parameter-efficient approach to combine knowledge from multiple tasks to solve a new task using a small trainable of parameters 🔥 while keeping the original LM *frozen* 🧊 [1/9]
Paper 📜: https://t.co/IgJvwCX5tU
@wiseed Bonjour, le projet fonds France Valley Revenu Europe mentionne 10% de commission de souscription. A qui est reversée cette commission et que finance-t-elle?
https://t.co/PlwnPaYJoQ
Language models memorize data & we can pull that data back out.
If you're training on private data, this should give you pause. If you're training on public data, this should still give you pause. Where does your training data come from and who consented (or didn't)?
The Productivity + Intelligence group in @MSFTResearch seeks experienced research managers in empirical software engineering to join us in advancing research on data-driven and AI-infused developer productivity experiences. For more information: https://t.co/ccxyHcgsHy
Check out our work at Microsoft on Unit Test Case Generation with Transformers!
Models pretrained on English and source code, then finetuned on the task of generating test cases.
Paper: https://t.co/QYpcpXYV9I
Collaborators: @DawnDrainML, @asvyatko, @skdeng, Neel Sundaresan