$Fhe moving and best chart right now looking like a potential massive candle explosion. Consolidated and now it’s time. Ai and data trends back in rotation and this will be first to pump
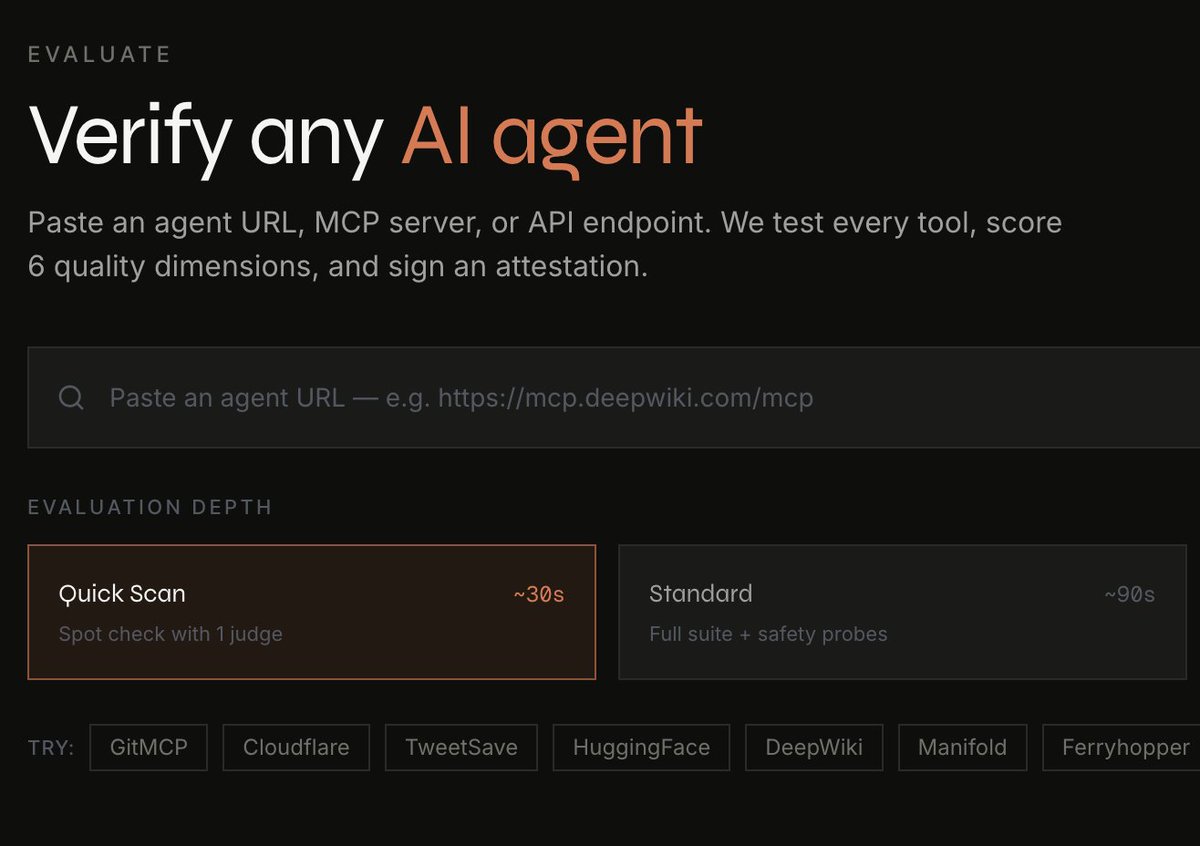
Introducing @Laureum_ai — quality scoring for MCP servers and AI agents by @assisterr
We score 6 dimensions: accuracy, safety, reliability, process quality, latency, and schema quality.
Multi-judge LLM consensus + adversarial probes.
We've scored 28 public MCP servers to date.
Average: 68.3/100. 6 in Expert tier (≥85).
The weakness nobody else measures: process quality — averaging 55.5/100.
Here's why we built it👇
Three gaps in agent eval today:
→ Marketplaces curate by hand. A major MCP catalog operator pruned 17 abandoned /vanity / impersonation entries from their own catalog earlier this month — manually.
→ Eval frameworks (LangSmith, Braintrust, Galileo) score tool-call correctness well. Process quality — error handling, input validation, response structure — sits between them, and nobody surfaces it as a named composite.
→ Post-Drift, the Solana ecosystem just launched STRIDE for smart-contract security. Agent infra still ships without pre-deploy quality gates.
Laureum is the missing layer.
Free right now, no signup:
1/ Quick Scan — paste any MCP server URL, get a 30-second 6-axis score → https://t.co/ExnDsfkJwz
2/ Public leaderboard — see how the most-used servers rank → https://t.co/zIVpbtyCTh you're building, run yours. Reply with your score — we'll feature the top 5 this week.
End of the tweet.
@rawsalerts Here we go. I was waiting for them to start the chaos. Sheeple. Lord Jesus Christ, I pray these people who want to fight and stand for evil see there errors and open their minds and heart to the Good Shepherd. They know not what they do.