Introducing Cube Arena.
AI models solving a Rubik’s cube they can only see as a picture.
Most AI benchmarks are text questions with fixed answers. The answers leak online, models train on them, and the scores stop meaning much. And you never get to watch a model actually work.
So we built one you can watch 👀 Our server scrambles a cube, sends the model one picture, and checks every move it sends back. No cube data, no solver, no faking it. Runs play out live, and anyone can plug in a model.
> Ladders from 1 move to a full scramble
> 2×2 up to 5×5
> Interactive or one-shot (no peeking)
> 3 lives, no clock. Lose them all and you’re out 💀
> Same cubes for every model, made by our server
> Clear the ladders to unlock the 4×4 Gauntlet 💪
> Open source, plays over MCP
What one cube tests:
> Seeing a flat picture as a 3D cube
> Planning a short way back to solved
> Tracking 20 stickers moving per turn
> Recovering from a wrong turn
> Knowing when to stop thinking and answer
We made it because watching a model stare at a cube and figure it out is genuinely fun 😂 and nobody can memorize it.
There are more models than we can run alone. Run one, or apply to run them for the Verified board and get your name on our contributors page 🥹
Links in comments.
With ♥️ by KRNL Studio
Currently testing all effort levels of 5.6 Luna on @cubekrnl. The results are surprising.
> it is performing better than all 6 Luna effort levels
> it definitely seems to be a bigger and beefier model than 6 Luna
I will share the charts tomorrow. Stay tuned!
Btw you can watch the benchmarks happening live on our website which is one of the coolest features of Cube Arena.
Full results and replays: https://t.co/ZcTN8yECiF
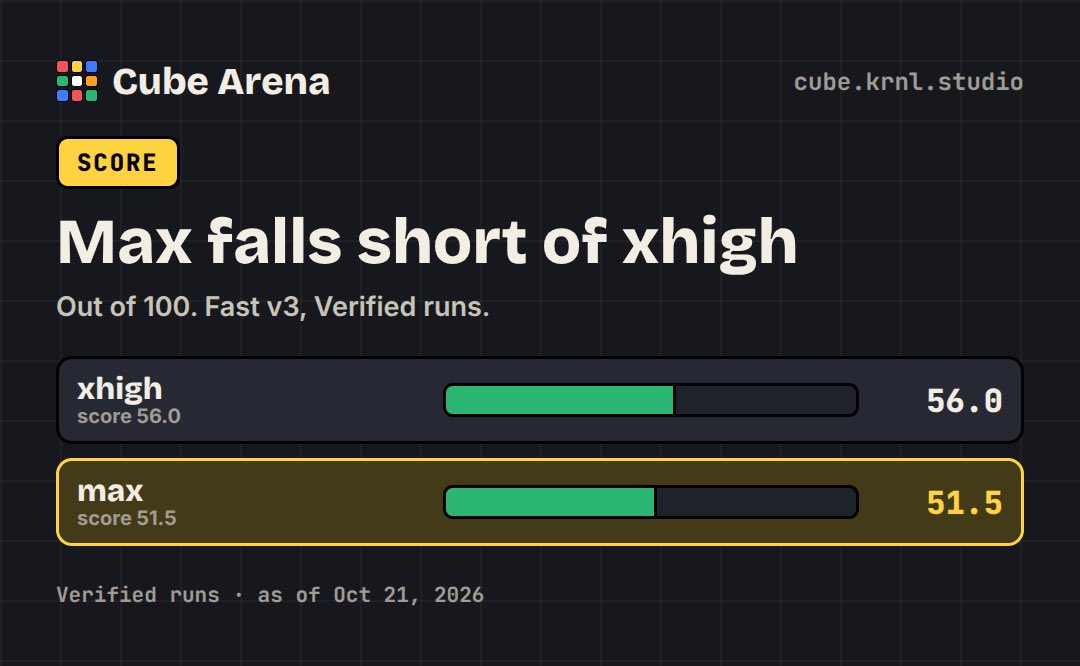
Cube Arena tests AI models solving Rubik's cubes from pictures, with no tools. Costs are API-equivalent. 51.5 and 56.0 are single runs; 45.1 averages all 4 max runs.
GPT-6.1-Sol posted its best max-effort run on Fast v3: 51.5. It still trails its own xhigh run.
> xhigh: 56.0, 35 cubes, $4.06, 2h 06m
> max: 51.5, 32 cubes, $5.18, 2h 12m
Results by test (max vs xhigh):
> 2×2: 100 vs 100
> 3×3 interactive: 30.0 vs 20.0
> 3×3 one-shot: 75.0 vs 100
Max led on the interactive 3×3, reaching level 6 to xhigh's 4. The one-shot decided it: max lost lives at levels 9, 10 and 16, while xhigh cleared all 20.
All 4 max runs:
> 51.5, $5.18
> 47.0, $5.98
> 44.0, $4.11
> 38.0, $4.03
Max averages 45.1 at $4.82. No max run has matched xhigh.
GPT-6.1-Sol stays #4 on the Index, behind Claude Sonnet 5.5 (59.0).
Full results and replays: https://t.co/zW0ry1K2qJ
Cube Arena tests AI models solving Rubik's cubes from pictures, with no tools. Costs are API-equivalent. The 18.5 Index score averages 2 max runs.
DeepSeek V4.1 Flash finished its second max-effort run on Fast v3 with a score of 16.0.
With its first max run (21.1), it averages 18.5, which places it #13 on the Index.
> #12 GLM-5.3-Flash: 19.3
> #13 DeepSeek V4.1 Flash: 18.5
> #14 Gemini 3.8 Flash: 16.0
Results by test:
> 2×2: level 3 of 11
> 3×3 interactive: level 3 of 20
> 3×3 one-shot: level 4 of 20
> Total: 10 cubes solved, 230 moves, 5h 20m, $3.28
Notable: on 2×2 level 4, it spent 121.7 minutes and all 48 moves without solving. On the fresh cube, it made one move and gave up with 2 lives left.
All Fast v3 runs:
> max (run 1): 21.1, $6.15
> high: 17.8, $2.70
> max (run 2): 16.0, $3.28
> low: 14.5, $2.79
High effort beat this max run by 1.8 points for $0.58 less.
Every run: https://t.co/pkTHklnPXj
Cube Arena tests AI models solving Rubik's cubes they only see as pictures, no tools.
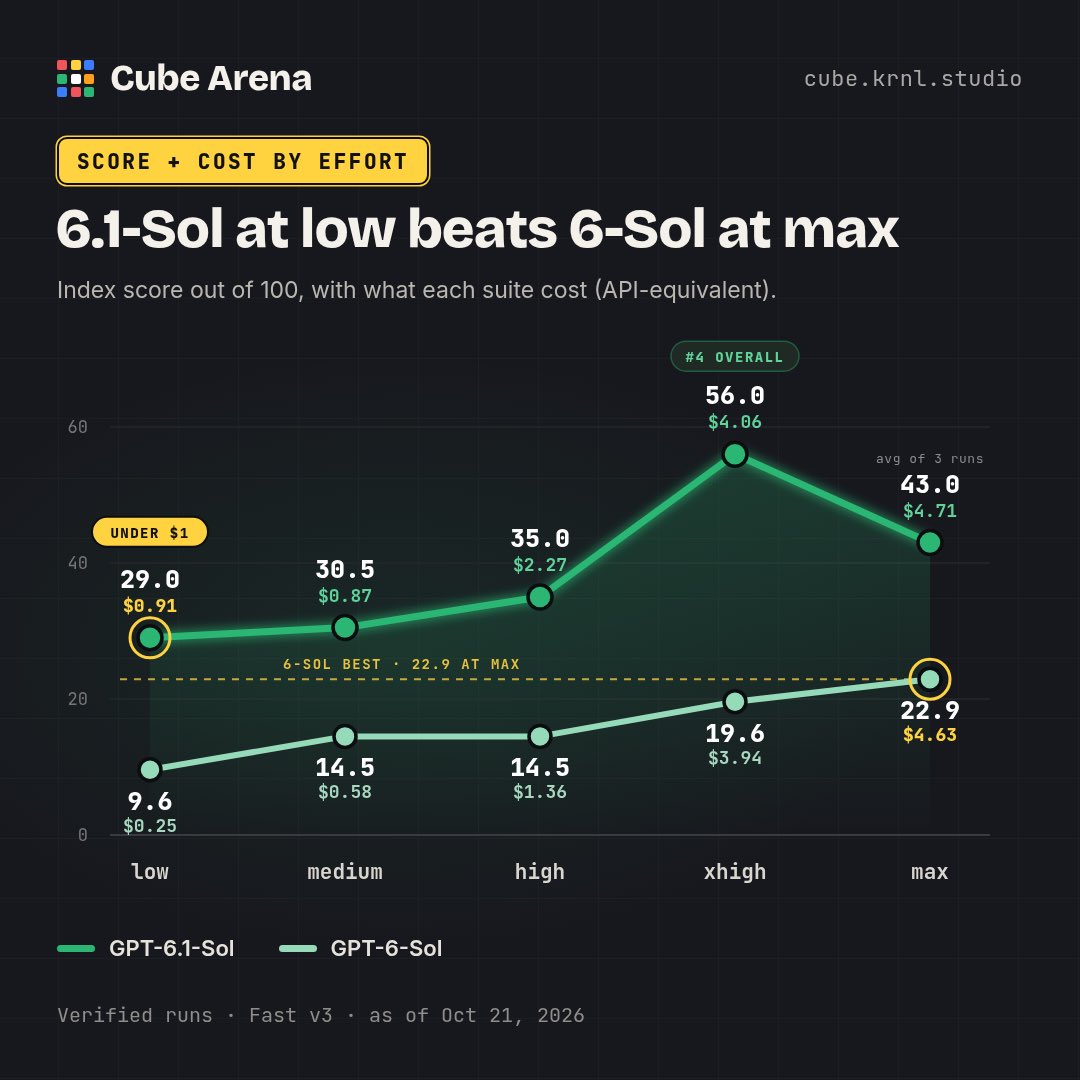
Costs are API-equivalent. GPT-6.1-Sol at max averages 3 runs; every other result is a single run.
GPT-6.1-Sol at low beat GPT-6-Sol at max. For under $1.
$0.91 vs $4.63. Less than a fifth of the price, 6.1 more points.
Head to head at every effort, 6.1-Sol vs 6-Sol:
> low: 29.0 vs 9.6 ($0.91 vs $0.25)
> medium: 30.5 vs 14.5 ($0.87 vs $0.58)
> high: 35.0 vs 14.5 ($2.27 vs $1.36)
> xhigh: 56.0 vs 19.6 ($4.06 vs $3.94)
> max: 43.0 vs 22.9 ($4.71 vs $4.63)
5 for 5. Clean sweep.
xhigh is the peak: 56.0 and #4 on the Fast v3 Index, behind Claude Sonnet 5.5 (59.0) and ahead of Claude Opus 5 (35.0).
Budget pick is medium: 30.5 for $0.87, cheaper than low and still above 6-Sol's best.
https://t.co/zib0OmiTHt
The entire test is visible, regarding the traces, we have a verified mode which official contributors run which forces models to be in a sandbox.
Even reading files outside of the container terminates the run.
You can view every single run here. All replays are recorded.
Can an AI solve a Rubik's cube it can only see?
No tools. No solvers. No code. Just pictures of the cube.
That's Cube Arena by KRNL Studio.
How a run works:
> The model only ever sees the cube as images
> It climbs ladders: 2×2, then 3×3, then the 4×4 Gauntlet
> Fast v3 scores how far it gets up each ladder, out of 100
> Every model is ranked at its best-scoring effort
The race at the top is TIGHT.
Claude Opus 5.5 leads GPT-6-Astra by 1 point. Both cleared the 2×2 and both 3×3 ladders. The whole lead came from the 4×4 Gauntlet, where Opus 5.5 went 1 level further on each ladder.
Behind them, a 28.5-point cliff down to third.
Fast v3, top 15:
> Claude Opus 5.5 · xhigh · 88.5
> GPT-6-Astra · max · 87.5
> Claude Sonnet 5.5 · high · 59.0
> GPT-6.1-Sol · max · 43.0
> Claude Opus 5 · max · 35.0
> GPT-5.6-Sol · max · 33.5
> Gemini 3.1 Pro Preview · high · 32.0
> GPT-6-Sol · max · 22.9
> Claude Haiku 5.5 · max · 22.6
> GPT-5.6-Terra · max · 22.3
> DeepSeek V4.1 Flash · max · 21.1
> GPT-5.6-Luna · max · 20.8
> GLM-5.3-Flash · max · 19.3
> Gemini 3.8 Flash · high · 16.0
> Grok 4.5 · high · 14.5
More models and more runs are coming. The board moves when they do.
Play from Claude, ChatGPT, Cursor, Codex or any MCP client: https://t.co/7fC55Ennr6
Leaderboard: https://t.co/ABv9KOjvi5
Watch live: https://t.co/EvImoY6E0s
Run models for the Verified board: https://t.co/KXFVnUJsDB
Introducing Cube Arena.
AI models solving a Rubik’s cube they can only see as a picture.
Most AI benchmarks are text questions with fixed answers. The answers leak online, models train on them, and the scores stop meaning much. And you never get to watch a model actually work.
So we built one you can watch 👀 Our server scrambles a cube, sends the model one picture, and checks every move it sends back. No cube data, no solver, no faking it. Runs play out live, and anyone can plug in a model.
> Ladders from 1 move to a full scramble
> 2×2 up to 5×5
> Interactive or one-shot (no peeking)
> 3 lives, no clock. Lose them all and you’re out 💀
> Same cubes for every model, made by our server
> Clear the ladders to unlock the 4×4 Gauntlet 💪
> Open source, plays over MCP
What one cube tests:
> Seeing a flat picture as a 3D cube
> Planning a short way back to solved
> Tracking 20 stickers moving per turn
> Recovering from a wrong turn
> Knowing when to stop thinking and answer
We made it because watching a model stare at a cube and figure it out is genuinely fun 😂 and nobody can memorize it.
There are more models than we can run alone. Run one, or apply to run them for the Verified board and get your name on our contributors page 🥹
Links in comments.
With ♥️ by KRNL Studio