frontier generative media models (voice, image, video, music) @Google Building AI product since 2019: @flowith @onyx_dot_app @anyscalecompute @ibmwatsonx
Meet Gemini Omni 1.1 Flash ⚡️ Our newest multimodal model for video generation and editing. It now features your favorite creative controls from Veo, plus brand new capabilities.
Enjoy features like 4K upscaling, first / last frame control, and fast 360p drafting.
But, the biggest upgrade? Next-level scene extension.
With Omni 1.1 you can extend scenes based on 10 seconds of context from your original video, a big jump from Veo's 1 second! That means tighter consistency, deeper control, and longer, more cohesive storytelling.
See it in action ↓
Today we’re introducing Gemini 3.5 Transcribe, our latest transcription model built for incredibly precise, smart dictation across your favorite apps and devices.
Remember when traditional speech-to-text meant shouting over background noise, constantly hitting backspace to fix misspelled words, and manually deleting every "um" and "uh"? Those days are over.
Gemini 3.5 Transcribe isn't just dictation — it’s active intelligence with precise, context-aware speech-to-text support in 85+ languages. The model automatically filters out filler words, formats unstructured speech, and even pairs with your screen context to execute voice commands.
Watch as Gemini 3.5 Transcribe removes filler words and uses multimodal capabilities to seamlessly turn messy voice input and local files into a polished email draft.
そんなわけで、大勢の人たちの前で、ドラクエ10に登場するAIキャラ・スラミィについてスピーチすることが出来ました。『Gemini Live API』という技術のおかげで、自分専用のバディが誕生します。本当に最近のAIて、すごいですよね。この席を用意してくれた、Google Cloudのチームの皆さん、そしてスクエニの安西さん、小園さんに感謝です。
Finally shipped! The smart audio tags make me feel like I’m directing a voice play! Some practice and tips to share:
Guide to prompting Gemini 3.1 Flash TTS (text-to-speech) @googlecloud https://t.co/jD8Qq2xFFZ
Gemini 3.1 Flash TTS (text-to-speech) is available on Google AI Studio and Vertex AI today!
The new TTS model introduces a high level of controllability by allowing you to steer the delivery using 200+ audio tags.
Learn more → https://t.co/GHkEkObhms
The jump from AI video to AI "worlds" (#Genie3) + real-time interaction (#AIAvatars) is the ultimate crossover.
Imagine an avatar living 1k+ hours in a generated world—is it a tool or an "Innie"? Realizing that the "creepy" digital life scenes from #TheWanderingEarth aren't just movies anymore. 🌍📽️
We love stepping inside the worlds you’ve created with Genie 3.
Here’s a thread of some community favorites. Keep building and share your creations below!🧵
Listen up 🔊 We’ve made some updates to our Gemini Audio models and capabilities:
— Gemini’s live speech-to-speech translation capability is rolling out in a beta experience to the Google Translate app, bringing you real-time audio translation that captures the nuance of human speech
— Gemini 2.5 Flash and 2.5 Pro Text-to-Speech preview models bring improved adherence to style prompts, precision pacing with context-aware speed adjustments, and character voice consistency for multi-speaker scenarios
— Gemini 2.5 Flash Native Audio is now updated, with improvements to handle complex workflows, navigate user instructions, and hold natural conversations
I tried it out, and it was like having a virtual assistant that’s always with me. It can see, hear, and even take action based on what I say. I showed it my UPS shipping label, and it can tell me my package status when I asked later(it remembers the tracking number from the label I showed :O ). Multimodality is no longer a thing of the future!
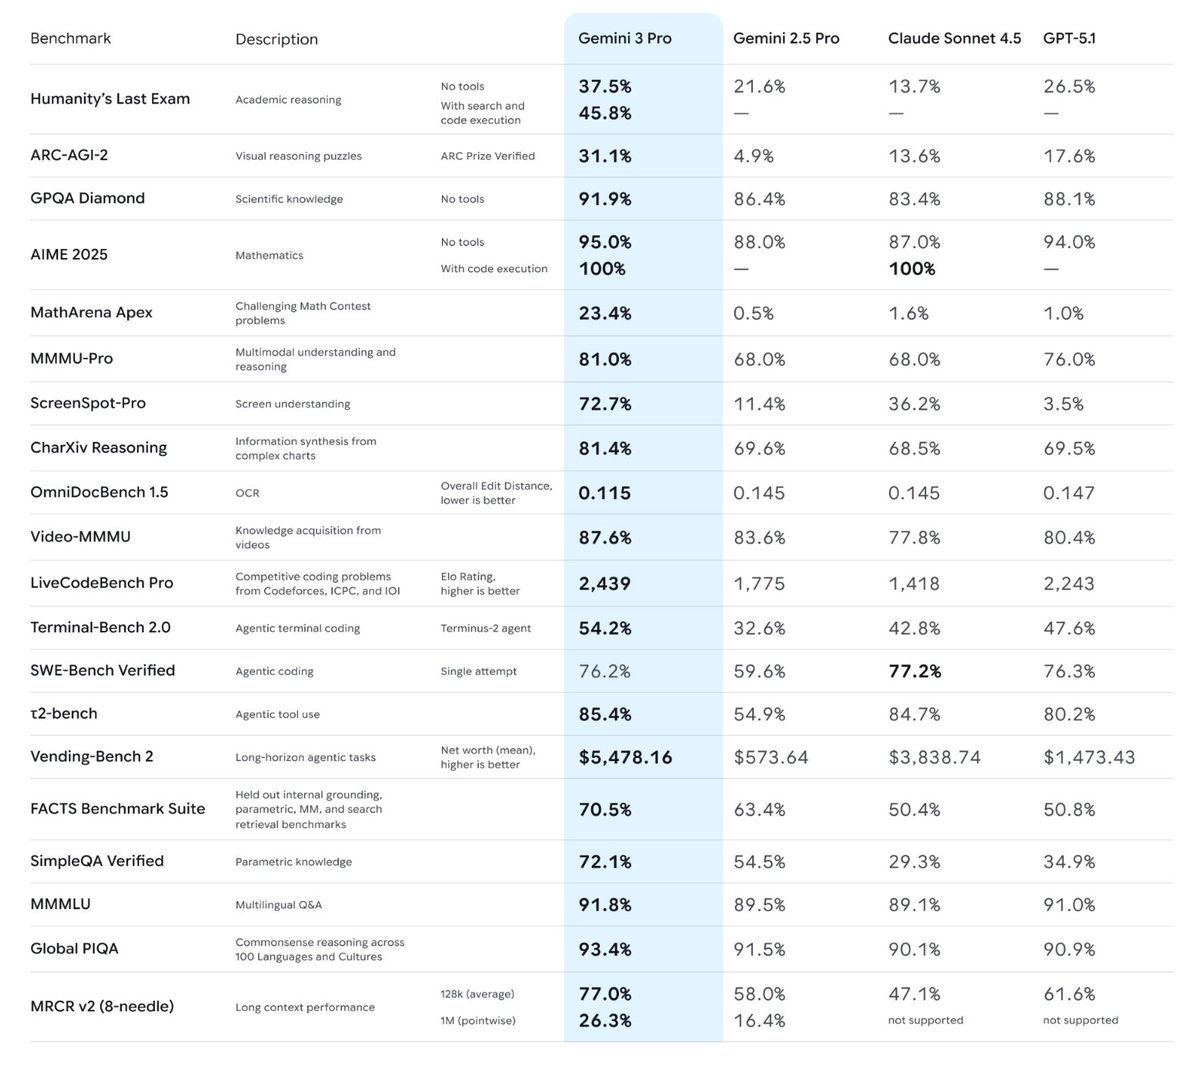
I’m really excited about our release of Gemini 3 today, the result of hard work by many, many people in the Gemini team and all across Google! 🎊
We’ve built many exciting new product experiences with it, as you’ll see today and in the coming weeks and months.
You can find it today on @GeminiApp and AI Mode in Search. For developers, you can build with it now in @GoogleAIStudio and Vertex AI.
https://t.co/KRV0xzniBY
The model performs quite well on a wide range of benchmarks.
Chatbot is the past, you deserve better.
Introducing Flowith 2.0 - supercharged AI creation workspace, with all your knowledge.
Your AI Canvas is now: multi-threaded, context-aware, deeply connected. See how: (1/6)
Thrilled to experience @clairesilver's work (remember her collab with @emikusano https://t.co/MK8EXREZk3) via holographic avatars, and watch @AcrylicRobotics recreate artwork live later today! See you there!
https://t.co/P0dpddjt9M
#AWSGenAILoft#AIArt#GenAI