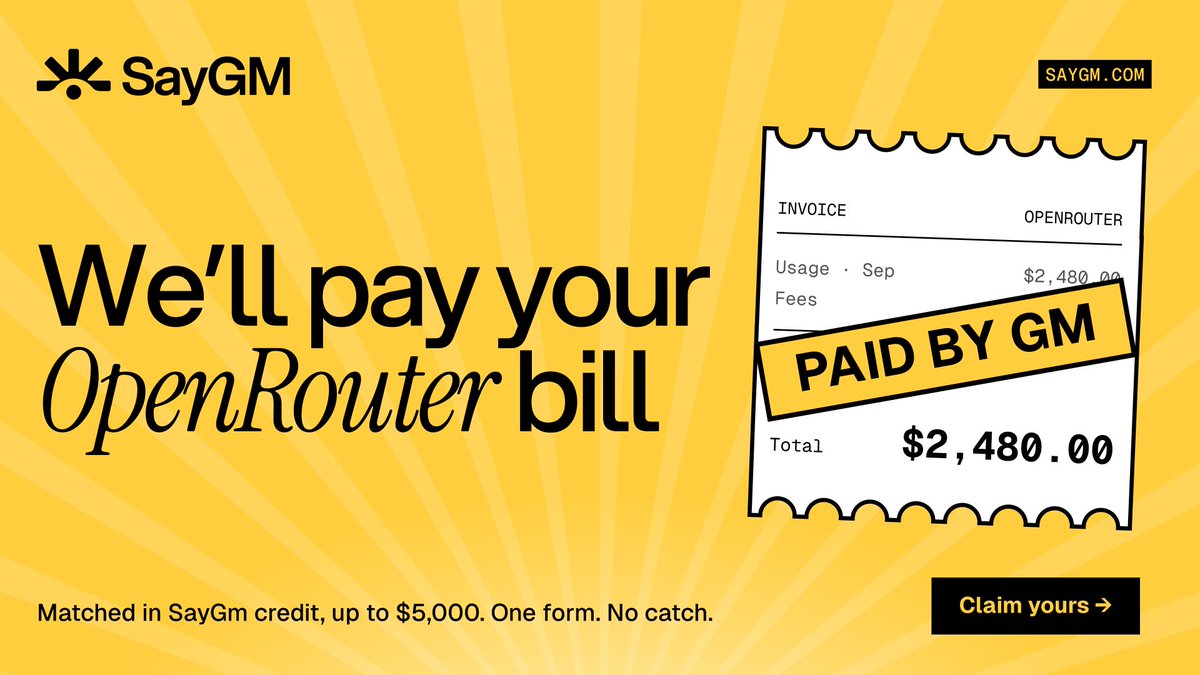
What if we just paid your OpenRouter bill?
Send us your last invoice. We'll match it in SayGm credit, up to $5,000.
One form to fill in. Claim it now👇
https://t.co/BqC5lHwIkk
Kappa run is now stopped, not too bad overall! We passed llama 3.2 1b on ARC-C, OBQA, TQA, etc., nearly matched on ARC-E, SciQ, etc. Considering that was 9T tokens and we hit those numbers on the 576B checkpoint, AND we did so around 90% cheaper per token, I'd call it a solid preliminary win!
Issues with the run:
1. In one of the Gated DeltaNet-2 heads, the per-channel decay gate underflowed, causing state wipe, and ourput RMSNorm amplified near-zero outputs ~1000x into fleet wide grad spikes.
2. Very late/slow nodes were so far behind their evidence was discarded, not a huge effect but we should have had better tolerance for stale data and partial updates.
3. We packed samples but didn't do masking/etc. which is sub-optimal for pretraining (not a huge diff but worth fixing anyways).
4. The first and last layers being GDN2 may be suboptimal also, vs. SWA, no clear evidence but might be worth switching up the order a bit for those two.
We have a fix for this GDN2 issue, but while that was still running I also tested EDA (https://t.co/2baRkRGnDA) and it actually addresses some of the root cause directly (and seems to have better loss than GDN2 anyways) so we'll probably switch to EDA once all tests come back clean and pass the kappa's instability regime (and waiting until we have highly optimized tilelang kernels for EDA to keep MFU/throughput high).
Onwards and upwards 🚀
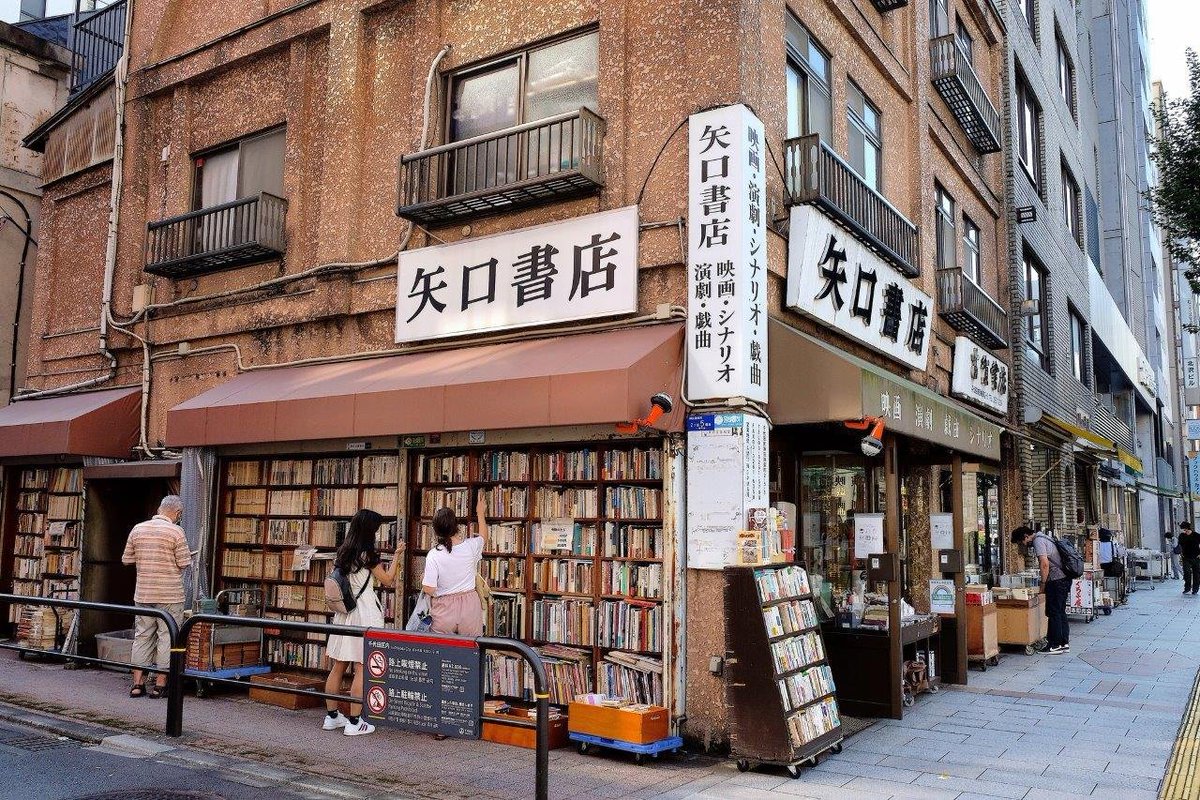
🦔Someone is buying Japanese used books by the ton. Not novels or comics. Philosophy, history, medical law, Edo-period cultural texts. Multiple buyer accounts all ship to one logistics center in Okayama Prefecture that won't answer questions. Export records show over 50 tons, roughly 100,000 volumes, shipped to the US since last year. No buyer has been identified.
Separately, court documents confirmed Anthropic's "Project Panama" bought millions of books in the US, cut the spines off, scanned them, and shredded the originals. An internal memo said the goal was to "destructively scan all the books in the world." Similar operations have been reported across Europe.
My Take
Anthropic's US book operation came out in court filings earlier this year. Project Panama. Millions of books, cut the spines off, scanned, shredded. Their VP chose the codename so nobody outside the company would find out. That story broke and apparently the same operation just moved to Japan. Anonymous buyer accounts, a warehouse in Okayama that won't take questions, and 100,000 volumes of specialized academic texts that nobody buys to resell.
I don't know how you build a trillion-dollar industry on material you had to acquire in secret through middlemen because you knew the public would object. Authors spent years on those books and now they're fed through a scanner and thrown away so a chatbot can sound smarter. If the data was free to use, they wouldn't need codenames and anonymous warehouses. The lawsuits over who owns this material have barely begun and I think the copyright exposure across the whole AI industry is enormous. Anthropic's internal memo said the goal was every book in the world, which describes the foundation of the product.
Hedgie🤗
A Harvard research team and @chutes_ai just released a public dataset covering one year of real-world LLM inference on Chutes: 6.12B requests across 9,174 models.
Technical usage data from a Bittensor subnet is now open to the wider AI research community.