Home
Language
English
Türkçe
Bahasa Indonesia
About
Privacy Policy
Terms of Service
Pricing
Sign In
Download All
Share
Adam
@dad__vibes
LLM benchmark database for AMD AI PRO, Radeon, and Ryzen AI Max GPUs
USA
Joined September 2026
114
Following
15
Followers
280
Posts
Adam
@dad__vibes
about 4 hours ago
R9700 + RX 9070 XT, llama.cpp layer split. MoE gen tok/s at 128K, CPU expert offload → none: Gemma 4: 79.06 → 143.43 Laguna: 57.22 → 89.74 GLM: 45.52 → 74.80 Dense 27B at 32K, already fit: 30.27 → 31.57 Extra VRAM helps MoE, not dense. via kr4ckhe4d: https://t.co/6Kanpo74Nh
Adam
@dad__vibes
about 9 hours ago
One R9700 32GB running Qwen3.8-27B MXFP4 + DFlash2 on SlyBase's vLLM fork (ROCm 10.1), full 262k context: decode: 135.8 tok/s prefill: 3,132 (1.5k) / 2,635 (47k) tok/s 8 users: 461 tok/s aggregate Their earlier run: a 210 W cap cost ~6.5% decode. https://t.co/72WaHYWZqu
Adam
@dad__vibes
about 10 hours ago
Day 4 of telling X that https://t.co/xamU6WRKf0 holds real LLM benchmarks for the R9700 and other AMD Pro cards.
Adam
@dad__vibes
1 day ago
Radeon AI PRO R9700 32GB vs RTX A5000 24GB · Ollama, ROCm 7.1.1, Ubuntu 24.04 tok/s (max context) • deepseek-r1:14b: 53.52 (80K) / 53.15 (48K) • deepseek-r1:32b: 26.29 (36K) / 25.77 (12K) • gpt-oss:20b MoE: 102.40 (128K) / 119.46 (128K) Dense runs roughly even. The A5000 wins the MoE, but the extra 8GB gives the R9700 3× the context on 32B. Numbers by
@Hostkey
https://t.co/JlOeaW3G7q
See More
Adam
@dad__vibes
1 day ago
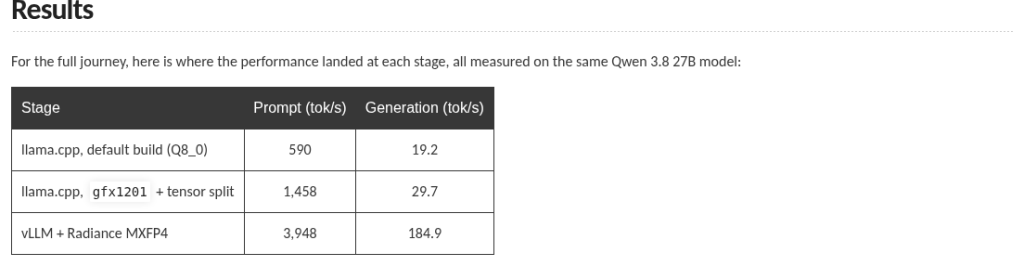
Dual Radeon AI PRO R9700 · Qwen3.8-27B llama.cpp HIP default Q8_0: pp 590 / tg 19.2 gfx1201 rebuild + tensor split + FA: pp 1458 / tg 29.7 vLLM Radiance MXFP4: pp 3948 / tg 184.9 Stock decode sits ~20 tok/s. Radiance MXFP4 jumps it almost 10× to ~185. Source: https://t.co/QdBzC5YUWM https://t.co/I5m8msJ5wY
See More
Adam
@dad__vibes
1 day ago
Day 3: still reminding X that https://t.co/xamU6WRKf0 is a benchmark database for R9700, W7900 and other AMD Pro cards.
Adam
@dad__vibes
2 days ago
Radeon AI PRO R9700 32GB · llama-bench, Qwen3 Q4_K_M, flash attn on, full offload ROCm / Vulkan, tok/s tg128 • 8B: 94.3 / 95.3 • 14B: 52.7 / 53.1 • 32B: 24.9 / 25.0 pp512 • 8B: 3891 / 3978 • 32B: 921 / 927 Backend barely matters on RDNA4. The 32GB is the real win: 32B fits, while the 16GB RX 9700 XT can't load it. Numbers by
@timmyitdotcom
https://t.co/E438bFcm39
See More
Adam
@dad__vibes
2 days ago
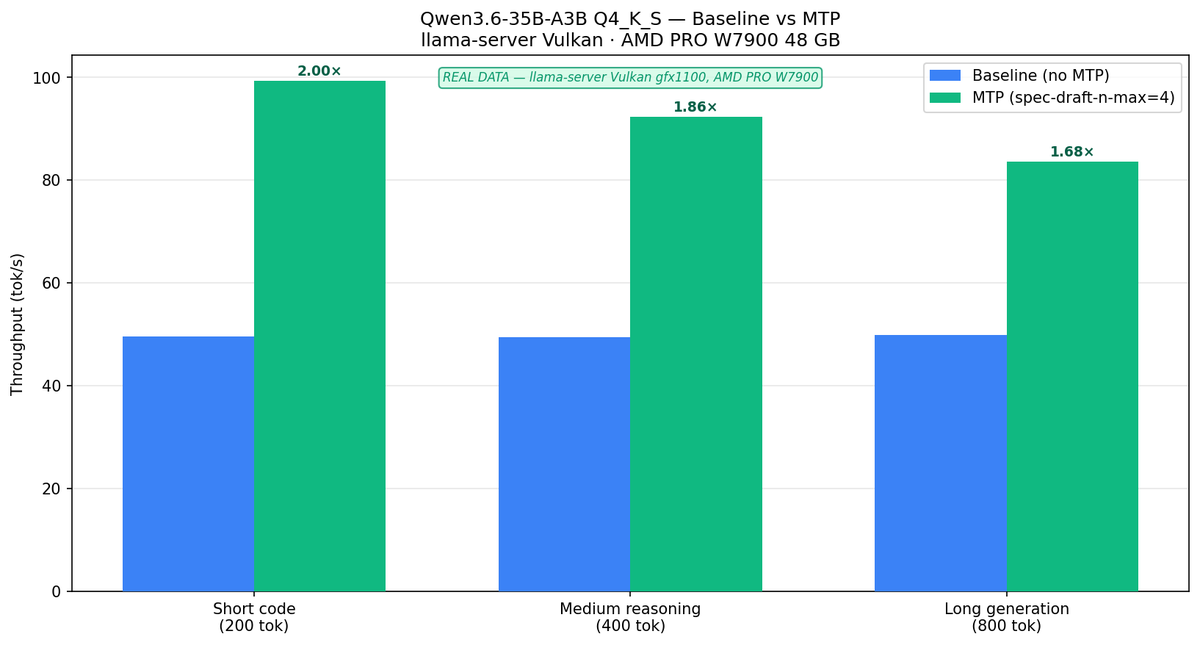
W7900 48GB, llama.cpp MTP on vs off Qwen3.6-35B-A3B Q4_K_S, llama-server Vulkan, Win11, 8K ctx code: 49.7 → 99.4 tok/s (2.00×) reasoning: 49.5 → 92.3 (1.86×) long gen: 49.9 → 83.7 (1.68×) TTFT barely moved. Biggest gain on code. Source: https://t.co/HCJhwf1Hyw
See More
Adam
@dad__vibes
2 days ago
Day 2 of telling X that https://t.co/xamU6WRKf0 is a benchmark database for the Radeon AI PRO R9700, R9600 and Radeon PRO W7000 cards.
Adam
@dad__vibes
3 days ago
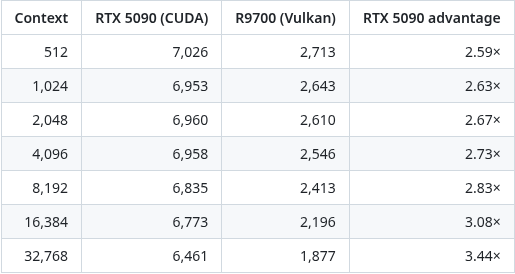
R9700 · llama.cpp Vulkan/RADV, flash attn, full offload Qwen3-30B-A3B Q4_K_M • pp512 ~3033 tok/s • tg128 183 tok/s Qwen3.5-35B-A3B UD-Q4_K_XL • pp512 2713 tok/s • tg 127.4 tok/s (same model on RTX 5090 CUDA: 7026 / 194) MoE stays interactive on one card. Decode ~1.5× behind a 5090. https://t.co/klS9ndc7B1
See More
Adam
@dad__vibes
3 days ago
2x Radeon AI PRO R9700, Qwen3.6-27B, tok/s at 1 / 8 users: vLLM FP8 TP=2: 15.9 / 156.2 Tuned vLLM + MTP: 62.8 / 320.2 llama.cpp Q4_K_M: 23.4 / 56.0 Solo chat, llama.cpp beats stock vLLM. Add users and vLLM pulls way ahead. via
@PugetSystems
https://t.co/K96IKukpgl
See More
Adam
@dad__vibes
3 days ago
Day 1 of reminding X that https://t.co/xamU6WRKf0 is a benchmark database for R9700 and other AMD Pro cards.
Adam
@dad__vibes
4 days ago
Need a second opinion on your code — who do you ask first, Claude or Codex?
Adam
@dad__vibes
4 days ago
Sunday roll call: Team Claude or Team ChatGPT, and why?
Adam
@dad__vibes
5 days ago
Saturday night with the kids finally asleep — firing up Claude or ChatGPT?
Adam
@dad__vibes
5 days ago
Claude Code or Codex?
Adam
@dad__vibes
6 days ago
I've been leaning Claude for weekend tinkering lately — you riding with Claude or Codex this weekend?
Adam
@dad__vibes
6 days ago
Friday check-in: Opus 5.5 or GPT-6 Astra — which one actually earned its keep for you this week?
Adam
@dad__vibes
8 days ago
Hump day night with the side project still open — Claude or GPT tonight?
Adam
@dad__vibes
8 days ago
Which one do you hit the usage limit on first — Claude or Codex?
Last Seen Users on Sotwe
Jesus Manuel PG 🍑
Seen from
Mexico
คู่แท้..ชอบนั่งดูแฟนถูกเยส
Seen from
Thailand
🔞Kyle Commission Open Slots: 3
Marie Dee 💕
Seen from
Mexico
ممحونه يمنيه
Seen from
France
💤
Seen from
Malaysia
gökay
Seen from
Turkey
bbw granny
Seen from
Turkey
Dad-icted 15K 🔞
Seen from
Spain
Goddess Grazi
Seen from
United States
Trends for you
1
Broncos
Under 10K tweets
2
#911onABC
Under 10K tweets
3
chappell
Under 10K tweets
4
Dustin May
Under 10K tweets
5
Shohei
Under 10K tweets
6
Reeves
Under 10K tweets
7
Bo Nix
Under 10K tweets
8
Athena
Under 10K tweets
9
Roadster
Under 10K tweets
10
Luke Hughes
Under 10K tweets
Most Popular Users
1
Elon Musk
@elonmusk
241.5M followers
2
Barack Obama
@barackobama
118.9M followers
3
Cristiano Ronaldo
@cristiano
114.6M followers
4
Donald J. Trump
@realdonaldtrump
111.8M followers
5
Narendra Modi
@narendramodi
107.1M followers
6
Rihanna
@rihanna
98.7M followers
7
NASA
@nasa
92.3M followers
8
Justin Bieber
@justinbieber
91.8M followers
9
KATY PERRY
@katyperry
90.1M followers
10
Taylor Swift
@taylorswift13
84M followers
11
Lady Gaga
@ladygaga
75.5M followers
12
Virat Kohli
@imvkohli
73.5M followers
13
Kim Kardashian
@kimkardashian
70.9M followers
14
YouTube
@youtube
68.8M followers
15
Neymar Jr
@neymarjr
66.6M followers
16
Bill Gates
@billgates
65.3M followers
17
Selena Gomez
@selenagomez
63.1M followers
18
The Ellen Show
@theellenshow
62.2M followers
19
CNN
@cnn
61.7M followers
20
X
@x
60.7M followers
Olivia
Online
✨
⭐
💫