@ElBesto37@RichardSocher What are you talking about they are showing nvfp4. I’m talking quantized to quantized. No one is wasting time running full precision for 1% more accuracy 🤣🤣
If ComfyUI keeps dying with "access violation" when it swaps GGUF models… try --disable-smart-memory
crashed on me 3 times in one night on my 5070 Ti 16GB
every time right when the next prompt swapped models (GGUF loader partially unloading)
with the flag models fully unload instead
zero crashes the rest of the run
slower swaps, but a queue that doesnt freeze at 2am is worth it
ComfyUI + ComfyUI-GGUF, MiniMax H3 turbo Q4_K_M
https://t.co/xml2IxEaYw
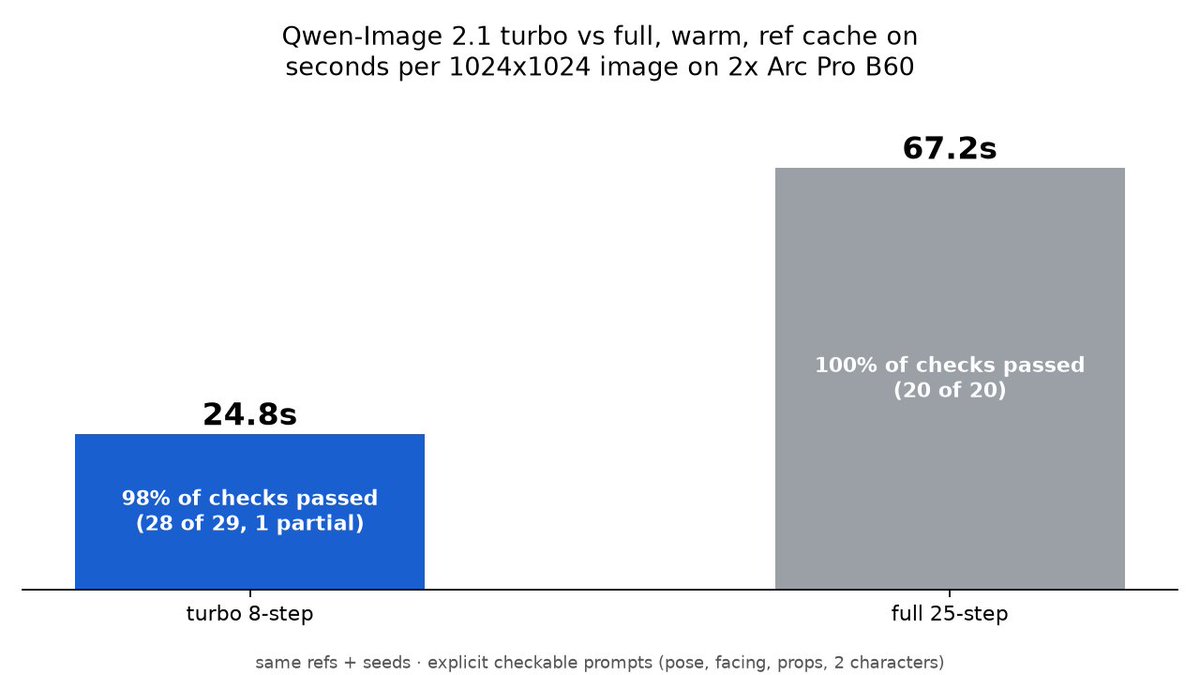
Said last week i couldnt tell Qwen-Image turbo from full… so i actually scored it
same refs + seeds, prompts with stuff you can check (facing direction, pose, props, 2 characters)
turbo 8-step: 98% of checks, 24.8s an image
full 25-step: 100%, 67.2s
1 partial miss for almost 3x the speed. im keeping turbo
int8 DiT, int8 ref cache on GPU, 1024x1024, 2x Arc Pro B60, ComfyUI XPU
Qwen-Image 2.1 with 6 reference images was taking 73s an image on my B60s
turned on the int8 ref cache on the GPU
31s first run
25s warm
same job. almost 3x faster
Qwen-Image 2.1 turbo int8, 8 steps, 1024x1024
Qwen3-VL-8B int8 encoder
QwenImage21Cache device=gpu dtype=int8
2x Arc Pro B60 24GB, ComfyUI XPU, ~12.7GB peak per card
https://t.co/GMVMe1QPFs
Yea you dont need a BF16 MTP head
swapped my int4 draft head for the original BF16 weights
acceptance at 8k: 51.7% int4 vs 49.5% BF16
at 200k: 62.1% vs 60.1%
and BF16 was 4-6% slower
rerunning the same int4 head moves it ~2.5 points, so its a wash. keep it int4
Qwen3.8 27B GPTQ int4 (Swift 1.5), MTP 6 drafts, 4 users
2x Arc Pro B60, vLLM 0.30 XPU + k8v4 cache
BF16 MTP weights from greglechin on HF
https://t.co/m5SQH6vb96
Spent last night trying to beat my own attention kernel on the B60s
fancy idea: pass partial results through L2 in a ring instead of writing them to VRAM
result: 2.3x SLOWER 😩
boring idea: just stop writing the dead rows
21MB less VRAM writes per request, a little faster, still bit-exact
Qwen3.8 27B int4, 200k ctx, 4 users, 2x Arc Pro B60
vLLM XPU + my k8v4 cache
https://t.co/m5SQH6vb96
Not specifically Intel but any of the large repos they have too many useless pr’s to filter through and nothing ever gets accepted. I’m glad your stuff did get accepted. I’m tired of everyone making their own tiny projects for small performance stuff instead of the big projects getting it 💪🏽