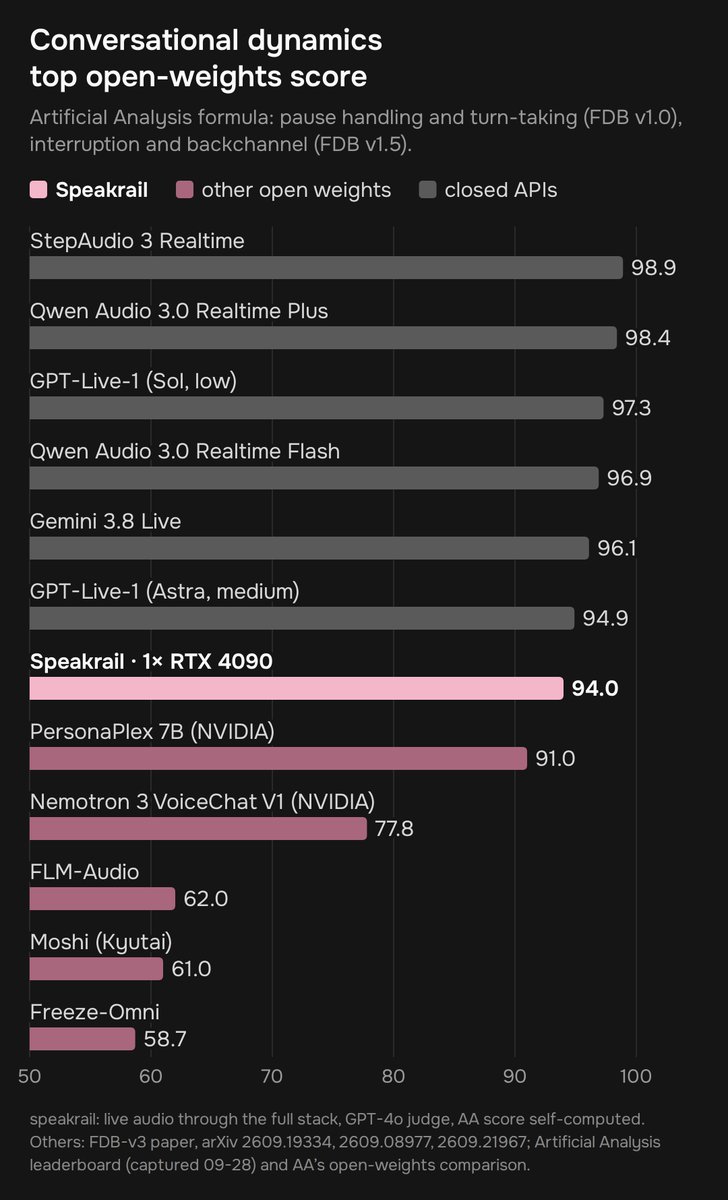
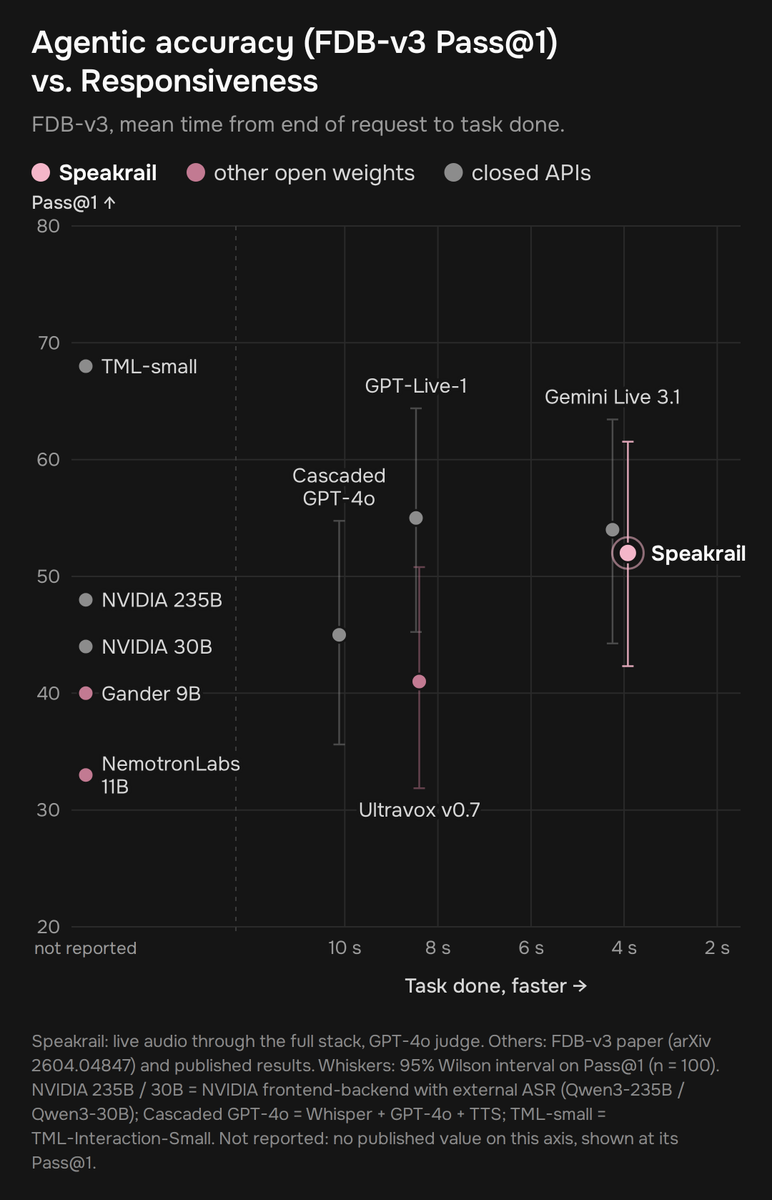
I built a fully local voice agent that rivals GPT-Live, on a single RTX 4090. Interrupt it mid-tool-call, it interjects, it ignores your 'mhm's. Completely open-source. A thread:
@ramsay I don't think you can do many concurrent sessions on a 4090. TTS and STT are the issue - they are not very batchable in the current code, and even if you could batch them, the 4090 can maybe do 2 clients at best at a good-enough latency
I built a fully local voice agent that rivals GPT-Live, on a single RTX 4090. Interrupt it mid-tool-call, it interjects, it ignores your 'mhm's. Completely open-source. A thread:
@Joshua_WD That's all for reliability. It doesn't incur any additional latency, so it works. Microturns help with interjections and interrupts as well, so training all this stuff wasn't a waste of time 😁
@Joshua_WD It's mostly done by the Voxtral model - I tuned a turn taking head onto it, and it understands that backchannels are something the model should ignore. Also, the Gemma microturn finetune is taught to ignore mm-hmms, okay, etc. And there are some guardrails in the harness as well.
To try it out, just download it from GitHub - https://t.co/3Alv8iC8pg
Needs a 24 GB NVIDIA GPU (tested on a 4090). Full technical report coming soon.
What should it learn next? Reply or open an issue, and I'll add it to the next dataset.
How it works: Gemma 4 12B is fine-tuned on "microturns": it reads streaming ASR and emits control tokens like <listen> or <interject>. A small head on Voxtral predicts when you're done, and a second Gemma writes thinking notes while you're still talking.
Inspired by the Thinking Machines' interaction demo. Their model is a closed-source 276B MoE, while this model can be downloaded and tested today.
The pipeline is based on Voxtral, Gemma 4 and Breeze TTS 2. Thanks to @MistralAI and @GoogleDeepMind for their amazing models.
As far as benchmarks go, this is the best open-source voice assistant that you can run locally. It completes tasks faster than GPT-Live, an API released a couple of months ago with approximately the same quality.
Launched Nexara - https://t.co/pMErteVzU1 - the easiest way to integrate speech-to-text into your n8n pipeline.
AI-First documentation - export entire docs into ChatGPT in one click!
200 minutes for free, no commitment. Feedback welcome!
#nocode#n8n#automation#speechtotext
Thinking of the following - if you read through the dataset, you might see a lot of boring "GPTisms". So what if I take a less powerful model that will, instead of rephrasing the given essay into a boring form, just create questions and copy-paste answers from the essay itself?
A thread:
I have been working on an extension of the custom ChatGPT tool to create a startup mentor based on Paul Graham's essays and YC Youtube Videos. For this, I created the following synthetic dataset: https://t.co/2TMYClIeIq
#startups#ycombinator#ChatGPT
Also considering doing RAG to reinforce the startup advisor even more (I still have ~15M characters of transcribed YC YouTube videos, so maybe I will put them into the RAG pipeline)
🚀Just finished the first version of my own ChatGPT UI! I know that there are a lot of similar projects out there, but I wanted to practice my Svelte skills😁 Really proud of how it turned out, looking forward to adding AI agents😎
Stay tuned for updates!
#ChatGPT#aiagents