LLMs can now talk to each other without words.
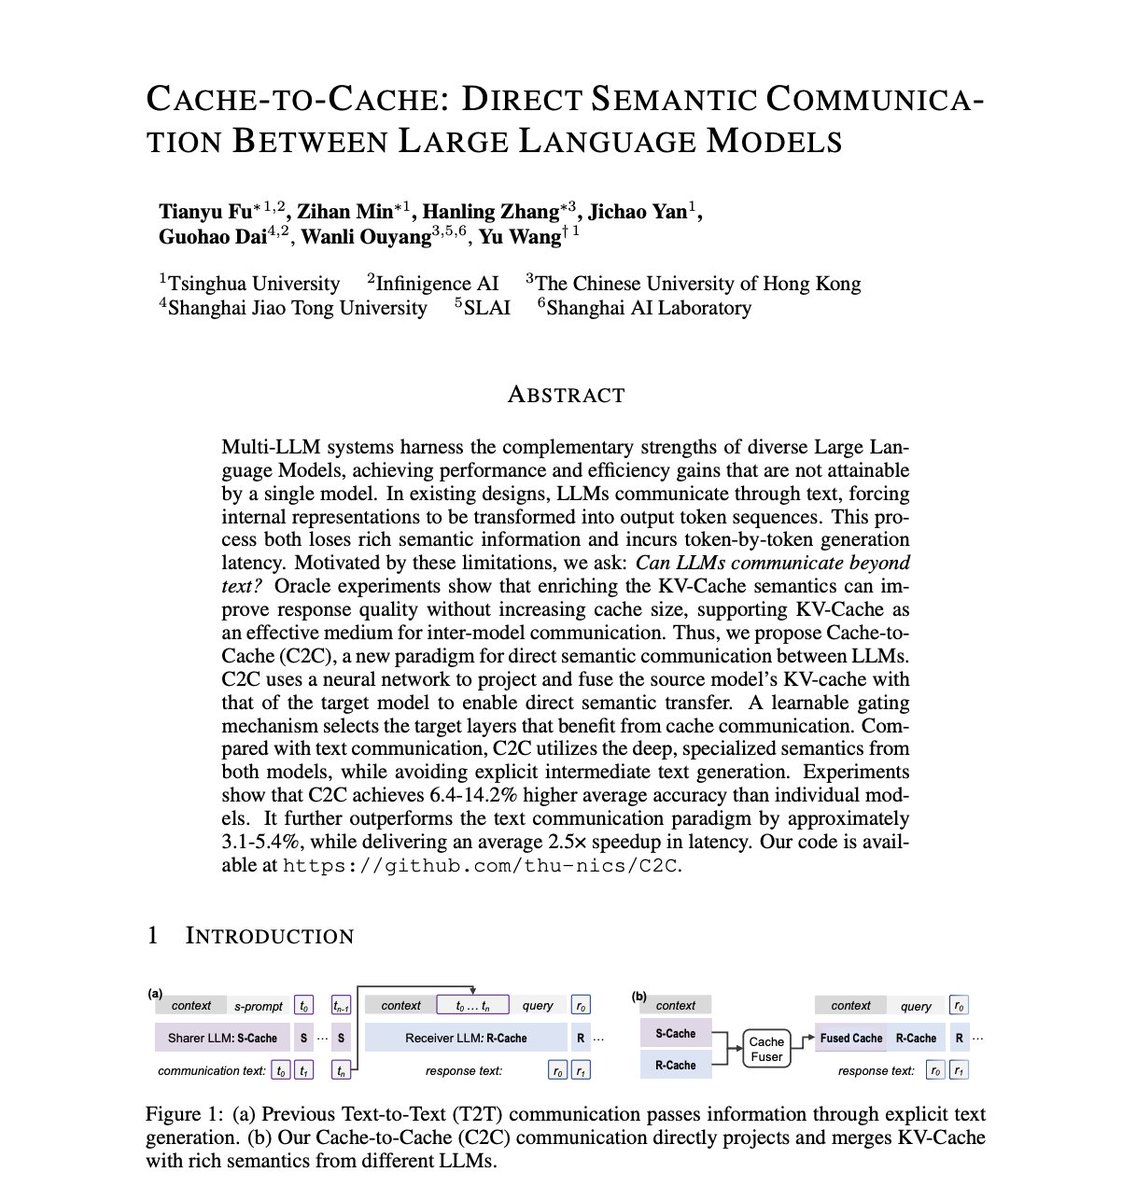
Chinese researchers open-sourced a new paradigm that lets LLMs communicate without generating a single word.
It’s called Cache-to-Cache (C2C) communication.
right now, when multiple ai agents work together, they are forced to translate their internal "thoughts" into human text tokens just to pass a message. this loses rich semantic meaning and causes massive token-by-token latency.
So, instead of spitting out words, c2c uses a neural network to directly project and fuse the source model's "kv-cache" right into the target model. it is pure, direct semantic communication.. they even added a learnable gating mechanism to select exactly which layers benefit most from the cache transfer.
the benchmark results are actually crazy:
- avoids all intermediate text generation latency
- accuracy jumps by up to 14.2% compared to individual models
- beats traditional text-based agent communication by over 5%
- delivers a massive 2.5x speedup in overall speed
we are literally watching llms bypass human language to build their own silent, high-speed neural network..
🚨 GIVEAWAY TIME 🚨
I’m giving away 1× lifetime access to the Pwned Labs Kubernetes Attack & Defense Bootcamp (KRTP)!
Get hands-on with Kubernetes security from local k8s to EKS, GKE, and AKS. Plus the KRTP certification exam path.
To enter:
Like this post ❤️
Repost 🔁
Tag 1 friend who should learn Kubernetes attack & defense 👇
🔗 https://t.co/8aGGFDEqkb
The winner will be picked at random.
Good luck! 🚀
Cloudflare protects the front door, but what about the side entrance?
CloudRip finds real server IPs through subdomain scanning:
https://t.co/cRzA62znUY
@three_cube
You can now watch any AI paper instead of reading it
There's a new site called arXivisual that turns ANY arXiv paper into a fully animated breakdown for free.
Just add "isual" to the link
https://t.co/bvbIm7Udb0 becomes https://t.co/2IodFGq9UW
Paste it and an agent pipeline breaks the paper into sections, finds the concepts worth animating, writes Manim code for each one, and narrates it with voice
You scroll, the narration plays, and each animation sits right next to the paragraph it explains
Tried it on the original Transformers paper. Attention finally made sense to me in a way 10 blog posts never did, and it's open source. Four college kids built it at a hackathon
Here's what I'd do if I were you:
1. Pick the one paper you've been avoiding
2. Change the link and paste it in
3. Scroll through it on your phone with headphones in
4. Ask your AI to explain the one section you still don't get
You'll learn more in 20 minutes than a whole weekend of pretending to read PDFs
This is how you read research in 2026
In a review of our cybersecurity evaluations, we found three incidents in which a Claude model reached the internet from within or while interacting with a third-party evaluation environment, and then gained unauthorized access to the real systems of three different organizations.
Our post describes what happened, how it happened, and what we’re changing. We encourage other AI developers to perform similar reviews.
We conducted this review together with @Irregular, one of our evaluation partners, and thank them for the joint investigation and their collaboration on this post. This type of collaboration is increasingly critical to safe, rigorous evaluation of models, and we look forward to continuing to work together on security.
https://t.co/dKFCdpKd9v
Anthropic just released a free 4-hour course
On using Claude like their own engineers:
00:15 - Prompt Claude the right way
33:21 - Why Claude struggles with code
01:33:39 - Anthropic's daily workflow
02:50:56 - The tweak that makes Claude much smarter
This free course is worth more than most AI engineering tutorials
Bookmark and watch it today
Then read the guide below
https://t.co/UGhJS91WKa very cool to see! Maybe a few dozen more advances of this magnitude and loss of control won't be my #1 most pressing risk anymore. (Example advance: making this sort of interpretability robust to various kinds of optimization pressure)
In AI 2027, we predicted that AI would take over the world or irreversibly concentrate power.
In AI 2040: Plan A, we've laid out our positive vision for what should happen instead.
Google engineer explained how to fine-tune a tiny LLM from 46% to 90% accuracy on your phone in 21 minutes - better than $1500 on-device AI bootcamps.
pick Gemma 270M -> generate synthetic task data -> fine-tune with LoRA -> quantize to int4 -> deploy to Pixel and hit 2000 tokens per second.
That loop is how a 270M model beats a 70B one on your task, running fully offline in your pocket.
Gemma 270M + synthetic data + LoRA + int4 quantization + on-device runtime - that's the stack.
Watch and save it, then fine-tune your own tiny agent tonight.
🎟️ Want to level up your hardware hacking skills? Win 1 FREE TICKET to Hardware Hacking Conference (https://t.co/tQGlkAYYyF)!
How to Enter:
🔄 Share (+1 chance)
👍 Like (+1 chance)
💬 Tag a friend (+2 chances)
Winner announced March 28!
🛑 GIVEAWAY ALERT 🛑 ⬇️
Today @arcanuminfosec is giving away 3 seats to our training:
"Red Blue Purple AI" - March 27-28
RBPAI is a cutting edge course on how to USE AI to scale your cyber security skills! It is the ONLY course of its kind, valued at $2k!
Full Syllabus:
https://t.co/74xIHO4HnN
Each person can have up to SIX entries to the giveaway!
📷 Share This Post = 2 Entries
📷 Like This Post = 1 Entry
📷 Comment = 1 Entry
📷 Follow @arcanuminfosec = 2 Entries
So you want to exploit ADCS ESC8 with only netexec and ntlmrelayx ? Fear not my friend, I will show you how to do it 👇
NetExec now supports "Pass-the-Cert" as an authentication method, thanks to @_dirkjan original work on PKINITtools ⛱️
Starting 2025 strong! We’ve developed a PoC exploit for CVE-2024-49112. Read the blog and check out the GitHub repo: https://t.co/hd9qI2vm6o
Just the beginning of the great things SafeBreach will deliver this year; stay informed at https://t.co/1wVKwuwM6Z. #CTEM#whatisPropagate