last dussehra Indians made about 19.6 billion UPI payments in a month. this september it was 24 billion (more than 800 million a day for the first time).
last dussehra google's $15 billion AI hub in Visakhapatnam had not even been announced. this april the ground was broken.
this year Indian teams released large ai models built here for Indian languages.
that is what one year looks like when a billion people keep showing up. wishing you and your family a very happy dussehra. may the year ahead bring good health and plenty to celebrate and may that celebration build our country
gemini 4 argon's 15% hallucination rate is too good but pls read the fine print.
it counts how often a model makes stuff up when it doesn't know. say 'i don't know' more and it drops.
argon got 50% right & gpt-6 astra got 63%.
lowest rate on the board? a 1b model at 1% btw.
openai shut down its ai detector three years ago because it didnt work, every tool since checks the words and words are easy to change
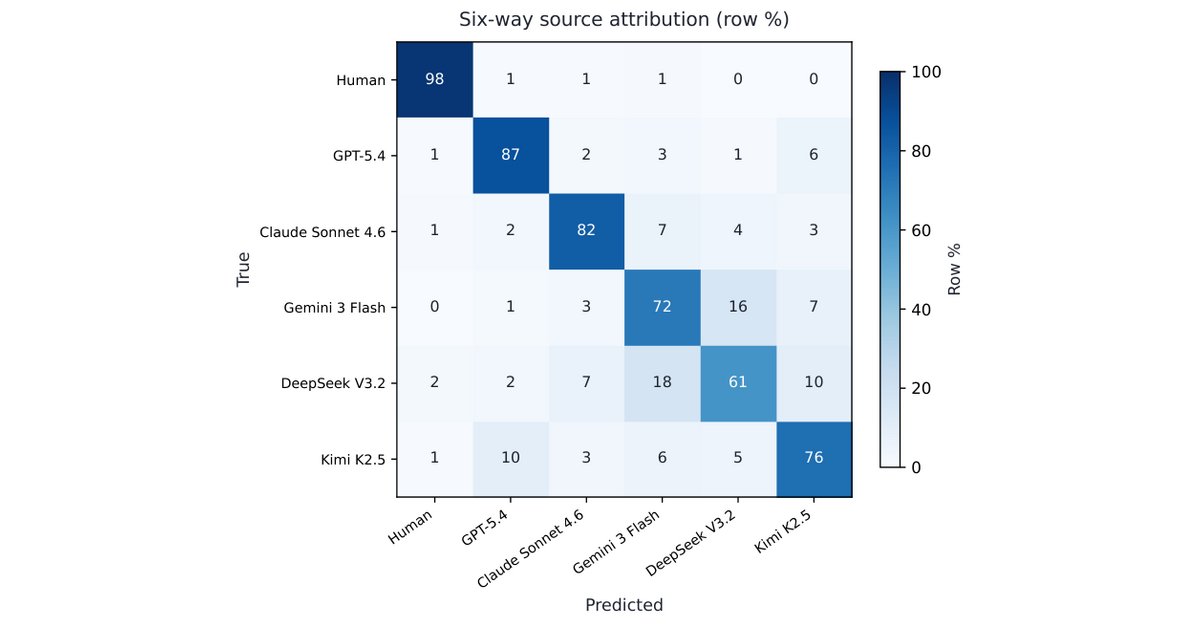
a paper this month tried something different instead of checking words it measured the shape of a post, does the title promise the payoff does the opening announce whats coming does the ending restate the point
it separated 2250 real company blog posts from ai copies and got 19 of 1740 wrong on companies it had never seen, then each model rewrote its own posts until three quarters of the phrasing was different, still got 19 wrong
the shape it found is the tidy post as it promises the result in the title says what it will cover before it starts and ends with a summary, gpt claude gemini deepseek and kimi all write it, the human posts were shorter rarely announced what was coming and were often interviews or roundups
the author adds a caveat i think is the real finding: the human writers knew their business and the ai only got a brief, some of what this measures is writing without context. when someone hands me an ai draft the fix is just the one thing they know that the model did not
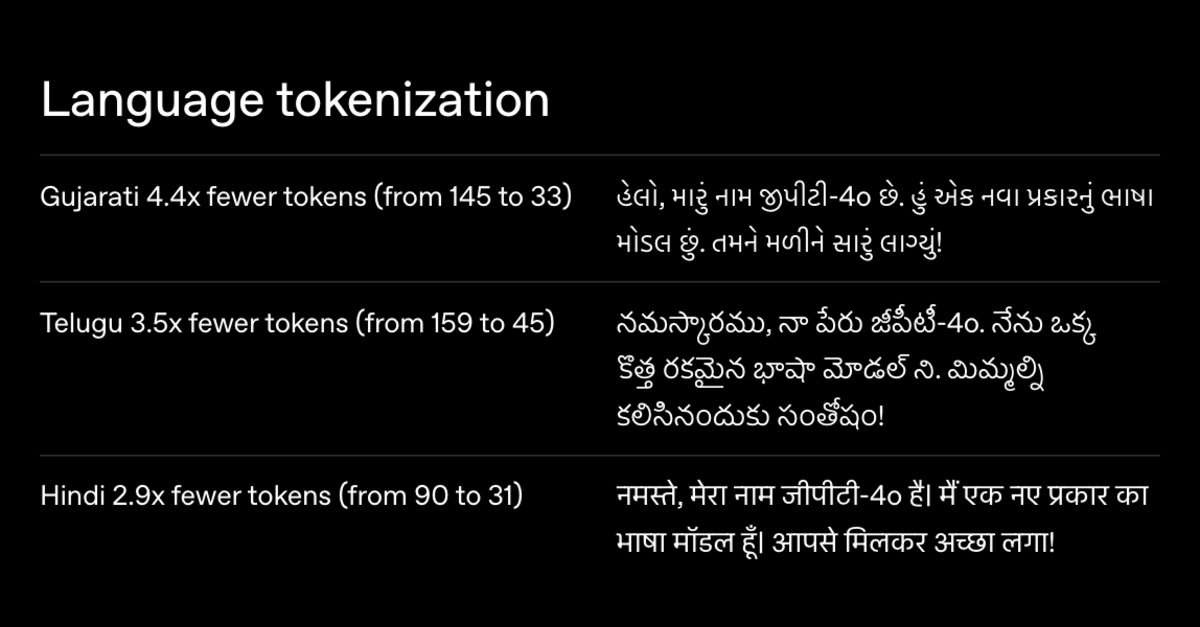
the same prompt in telugu used to cost 6x what it did in english.
on openai's older models, it took 27 tokens in english and 159 in telugu. tokens are the chunks of text an ai reads, and companies building on ai pay per token. so an app answering in telugu could cost about six times as much to run as the same app in english. openai published those numbers itself in 2024, when its new models brought telugu down to 45 (english went to 24).
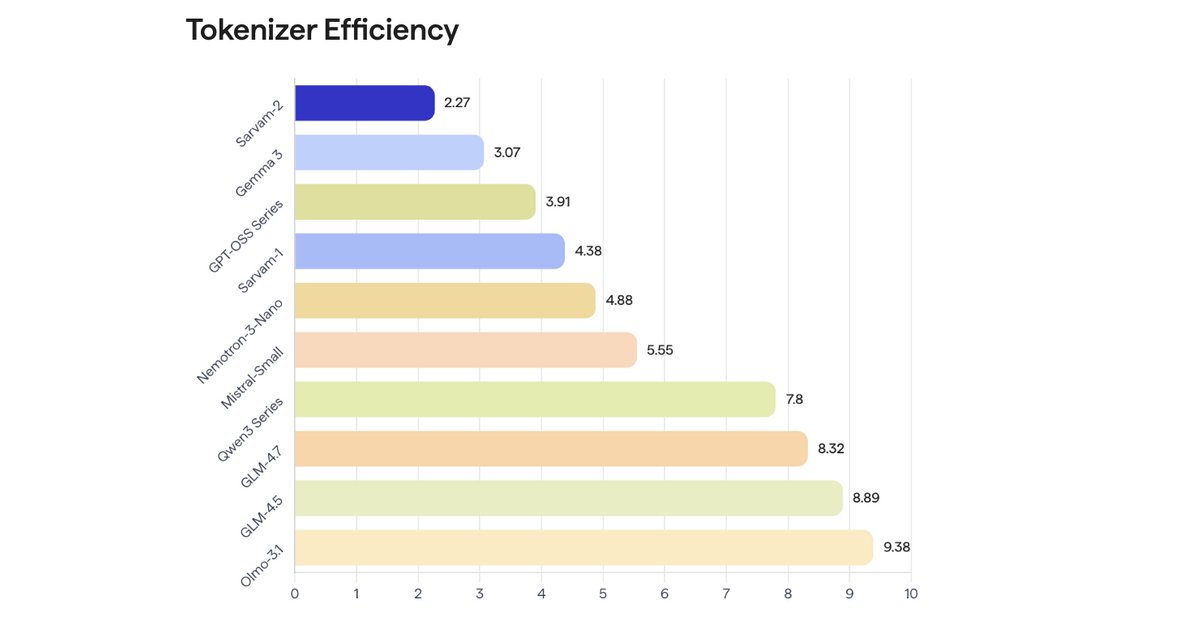
plenty of models haven't made that jump. sarvam, the bengaluru company building one of india's own models, published a chart this year of how many tokens different models need per word across english and 22 indian languages. it's their chart, and their model comes out on top at about 2.3. google's gemma 3 needs about 3. qwen 3, one of the most widely used open models, needs almost 8.
people ask why India needs its own models when global ones keep getting cheaper. part of my answer is in that chart. cheaper tokens don't help much if your language needs three times as many of them.
I hereby declare the "learn to code" era officially dead:
Big declines in the number of people studying computer science in the last year or two 📉
Chart from this week’s edition of our newsletter on AI and the labour market https://t.co/y4yKn6GTl1
i think outside tech most people using ai at work are on a free plan they signed up for themselves. plenty of the companies that said no to ai on security grounds just moved the work onto consumer accounts they have no way to know.
openai just said its next model meets the critical cybersecurity threshold in its own preparedness framework. finds unknown flaws, builds working exploits, across hardened systems w nobody steering
they wrote that threshold themselves and they are the ones announcing they have hit it lol
Muse Spark 1.3 is rolling out today with frontier performance almost too cheap to meter. This is the biggest jump we've made so far on coding and agentic work. Try it in Muse Code and our API.
Next up 🍉 and Muse Spark open weights releases coming soon.
Introducing Gemini 3.8 Flash, another upgrade in under a month! And the new 3.8 Flash Cyber pushes the frontier of cyber defense. Relentless progress 🚀 More on the models & our cyber security work in the blog - happy building! https://t.co/C5h14qANIV
Fable 5.1 is a massive upgrade, but the bigger story is how much cheaper it is.
Cache reads in particular are 75% cheaper!
This puts it much closer to the pricing of GPT-5.6-Sol, while being a much more capable model.
@mattshumer_ when the discount is more impressive than the model the frontier is clearly telling you capability has commoditised and price is the last axis left