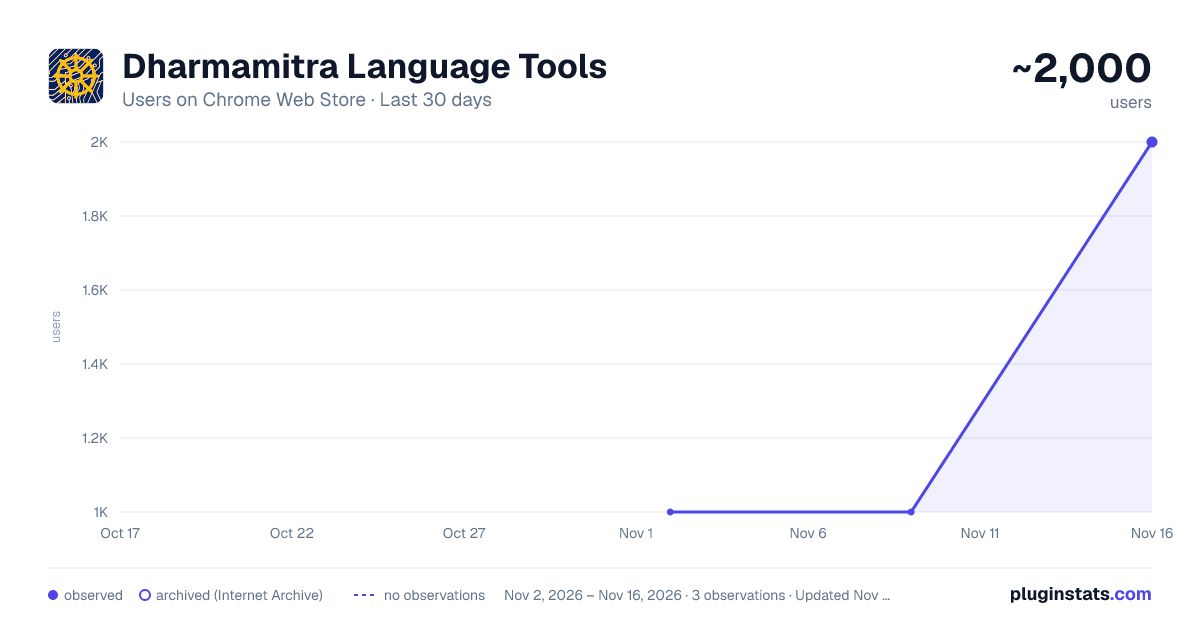
Trending on Chrome Web Store: Dharmamitra Language Tools by nehrdbsd
Provides translation and language tools from https://t.co/Sl0Qx0qsrs
+1,000 users this week (+100%)
2,000 users total · #2401
https://t.co/hH7K8QpEsu
After adding the Chinese version, the collection is now complete for all three languages: The downloade MITRA Lexica for Sanskrit, Tibetan, and Chinese, in Apple Dictionary and Stardict format! https://t.co/7kPEk7TEHd
New preprint: Nehrdich, S., Harimoto, K., Sellmer, S., & Hellwig, O. “MITRA-lexicon: Lexica of Attested Translations from Sanskrit into English, Tibetan and Chinese”. A family of corpus-grounded Sanskrit-English, Sanskrit-Tibetan, and Sanskrit-Chinese lexica with 2.18 million headword entries and 10.4 million attestations, each linked to its sentence pair.
New Release: We have the Dharmamitra Lexicon releases for Tibetan and Sanskrit now as standalone Stardict and Apple Dictionary files for free download! https://t.co/7kPEk7TEHd 1/
We just added to the Dharmamitra lexicon: Sanskrit ↔ English terms with 584k Sanskrit headwords (311k of them compounds & phrases), 1.13M sense pairs, 3.47M cited attestations from 402k aligned sentences across 54 texts!
The MITRA team is very happy to announce that we got two research papers accepted at WMT2026:
1. Mitrasaṃgraha: the largest Sanskrit–English parallel corpus to date with 391k sentence pairs
2, MITRA: a large-scale parallel corpus and 9B translation model for Buddhist languages
The Dharmamitra team is very proud to announce that we have switched our translation engine to a self-trained model recently, which in LLM-judge based evaluation outperforms our previous Gemini-based pipeline as well as Claude Opus consistently. 1/
New Dharmamitra open source models based on Qwen35: https://t.co/pWoOHMII52 We finetuned and released a number of base models, translation and instruction models, as well as embedding models in different sizes. We used over 30B tokens for the continuous pretraining!
Dharmamitra's OCR for Tibetan just got better by a large margin! We currently have a 20 page hard cap on OCR due to deploying much more powerful models, and we will lift this cap once our new hardware is ready for hosting the models!
Coming Up! Online workshop hosted by Dharmamitra and the Tsadra Foundation: "Translation in the Age of AI: Dharmamitra for Translator Workflows" https://t.co/sf5ROfWJvn @eventbritehelp
@Ratnadhrk It is the one we used until 2025, currently https://t.co/FPJcmYP9rD uses a specialized pipeline involving gemini, so the performance of that is a bit stronger than of our self-trained model.
The translation-optimized Mitra Chat LLM is now on Ollama: https://t.co/2OJY0TosJp Its especially strong on translation of Buddhist source languages into English, and it beats other open models!