I talk to an AI voice assistant every day. It’s genuinely useful.
But when I say “wait, that’s not what I meant,” it keeps talking for about four more seconds.
A human would stop instantly. Or get called rude.
That’s where voice AI is right now: useful, but still young. It fails in ways people don’t expect and don’t know how to design around. One day it’s perfect. The next it’s mispronouncing words, stuttering, lagging, talking over you.
The catch is that most of that never shows up in a transcript. The words look fine. The conversation wasn’t.
If you’re running voice agents across thousands of calls, you can’t read your way to these failures.
You have to listen.
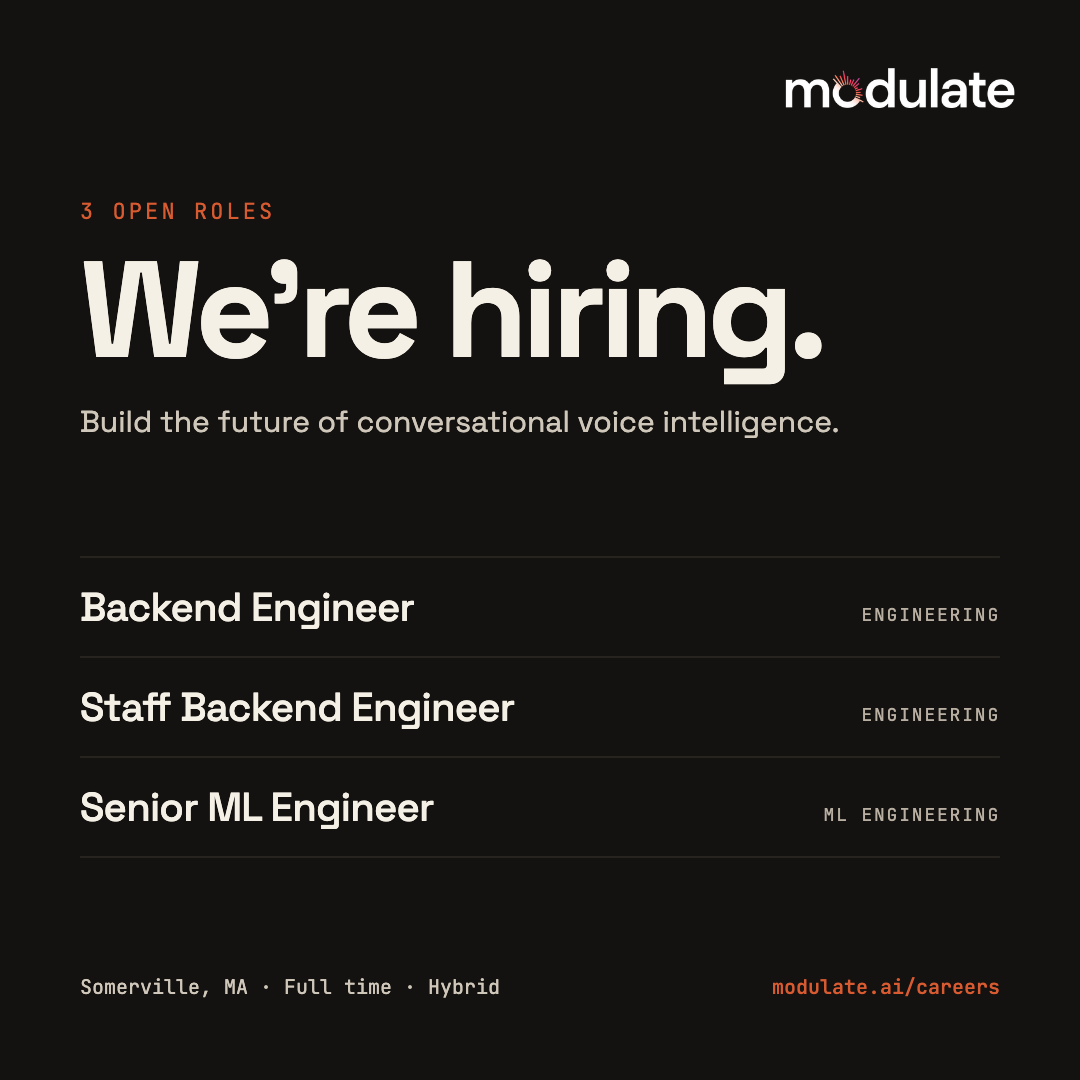
We're hiring. 3 roles, 1 mission: make voice a force for good online.
→ Backend Engineer
→ Staff Backend Engineer
→ Senior ML Engineer
Somerville, MA. Full time. Hybrid.
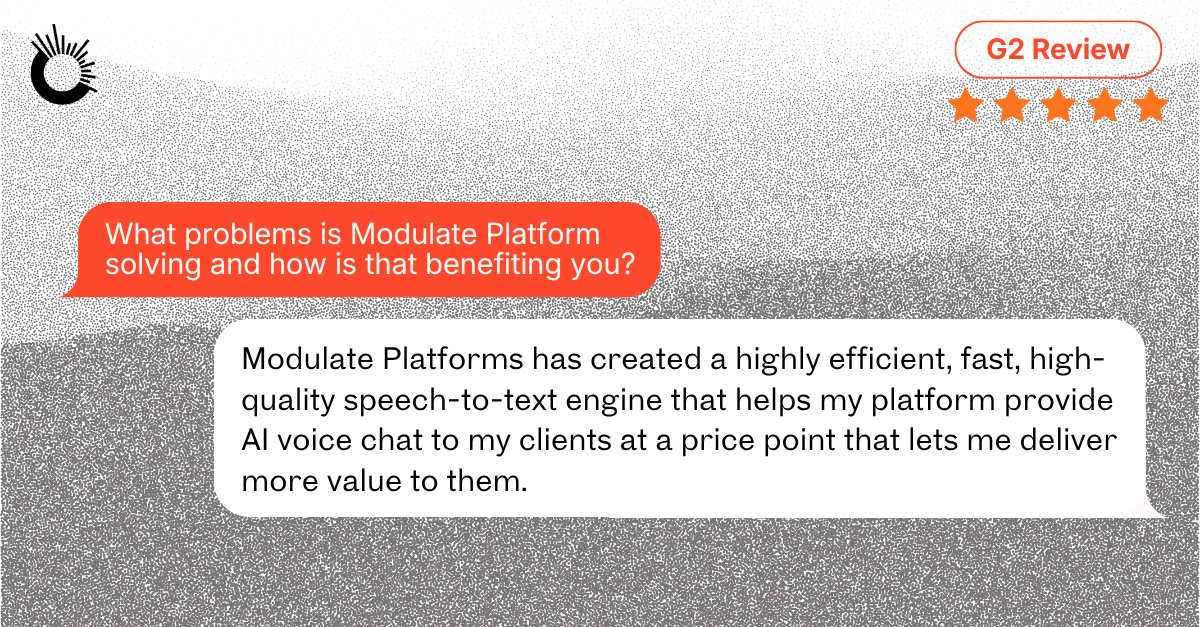
What does a small IT services team actually need from a speech-to-text API?
Speed. Accuracy. A price that doesn't eat the margin.
One G2 reviewer found all three with Modulate Transcribe:
⭐ 5/5 "Modern, Cost-Efficient STT with a Standout Feature Set"
They are now using it to power AI voice chat for their own clients - at a price point that lets them deliver more value downstream.
Start building with our API today 👇
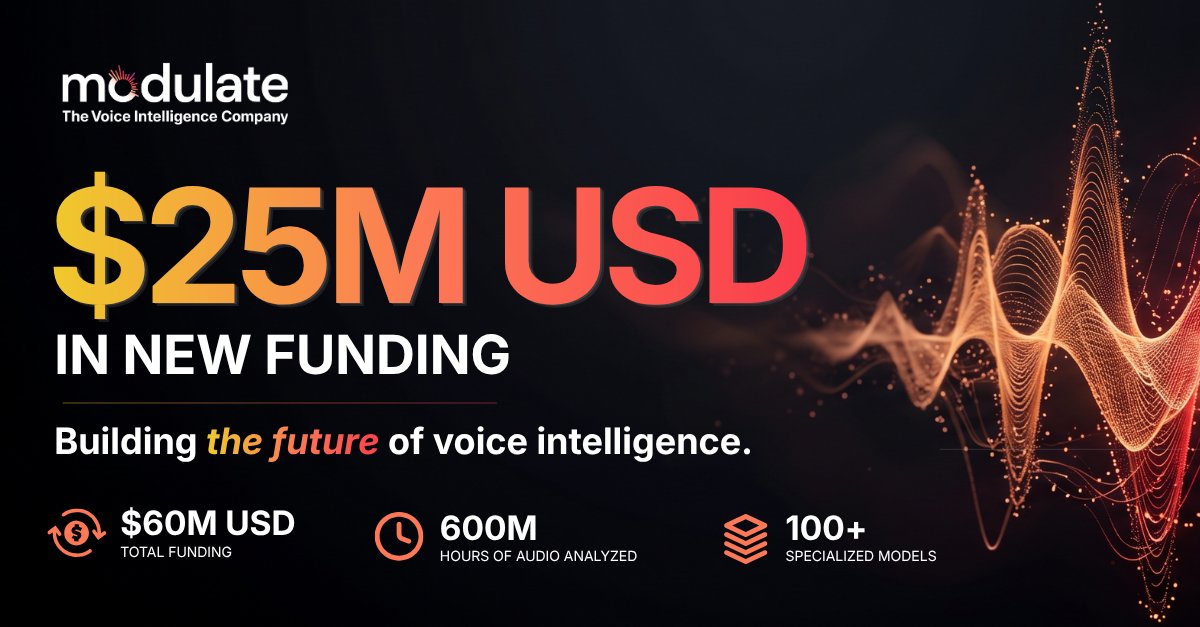
We just raised $25M in new funding led by Future Ventures (@VenturesVc), with @HyperplaneVC and @lakestarvc - bringing Modulate’s total funding to $60 million.
Building the next phase of audio-native AI: more models, more developers, more of the stack that actually understands voice.
Where we stand today:
- Ranked #1 on Hugging Face for deepfake detection and transcription
- 600M+ hours of audio analyzed
- 10M+ hours analyzed every month
A foundational layer of the AI stack is getting more powerful. More soon.
We’re hiring a Senior Machine Learning Engineer at Modulate 🔊
Voice is one of the richest sources of information we have - and we’re building models that can actually understand it.
This role will work across research and engineering to design, train, evaluate, and deploy ML models powering our conversational voice intelligence platform.
You’ll be working on problems spanning model quality, robustness, scalability, and production deployment - and helping push forward what machines can understand from human conversation.
If you have experience building and shipping production-grade ML systems, strong Python and PyTorch skills, and want to work on some genuinely interesting problems in voice AI, we’d love to hear from you! 🙌 👇
#hiring
Heading to @Ai4Conferences next week?
Join us and @axonis for happy hour on Tuesday, August 4 from 6-8 PM at Sugarcane, The Venetian.
Good drinks, great conversations, and even better company. Whether you're building AI, deploying it, or just want to meet fellow practitioners, we'd love to see you there.
Register to join here: https://t.co/qB6TQEuWfs
See you in Vegas! 🎲
Modulate is now #1 for Mandarin UER on Sierra's μ-Bench 🥇
Sierra's μ-Bench is the multilingual ASR benchmark built from real customer service calls. On it, Modulate Transcribe beat Google Chirp-3 and ElevenLabs Scribe-v2 on Utterance Error Rate - in Mandarin, the hardest locale on the leaderboard.
27.4% UER. 658ms P95 latency → nearly 2x faster than Chirp-3.
The lowest reported Mandarin UER on the leaderboard, at nearly half the latency.
Test it on your own audio. 1,000 free credits: https://t.co/lm7gCAsqIb
Our Voice AI Buyer's Guide breaks down the evaluation framework we wish more teams used - from latency and reliability to deployment, security, pricing, and the hidden tradeoffs that don't show up in benchmark charts 👀🚨
If you're evaluating Voice AI vendors in 2026, start here.
Download the guide: https://t.co/KD7XKxz0bJ
Soon, every platform that hosts audio will need to answer one question:
Is this AI-generated?
We teamed up with @hackernoon to show developers how to detect AI-generated music using the Modulate API.
Read the walkthrough and start building: https://t.co/PoOoJl5jdi
Voice AI is moving fast. Choosing the right platform shouldn't depend on who has the loudest marketing.
Our latest Voice AI Buyer's Guide covers what actually matters when evaluating solutions:
✅ Accuracy beyond benchmarks
✅ Latency and reliability
✅ Scalability
✅ Security & compliance
✅ Cost at production scale
✅ Questions every vendor should be able to answer
Whether you're building customer support, transcription, moderation, or conversational AI, this guide will help you make a more informed decision 💡
GTA Online players are remarkably tolerant of hard gameplay.
What the data suggests they're less tolerant of: abusive voice chat 👀
Players exposed to it show up to 50% higher anger scores - and up to 50% higher odds of logging off within 15 minutes ⏲️
Since implementing @modulate_ai’s ToxMod, weekly violators in @RockstarGames GTA Online have dropped from 3.2% to 0.49% - well below industry averages - with precision holding above 98% throughout.
Toxicity isn't just a community problem.
It's a retention problem.
Full case study linked in caption 🔗
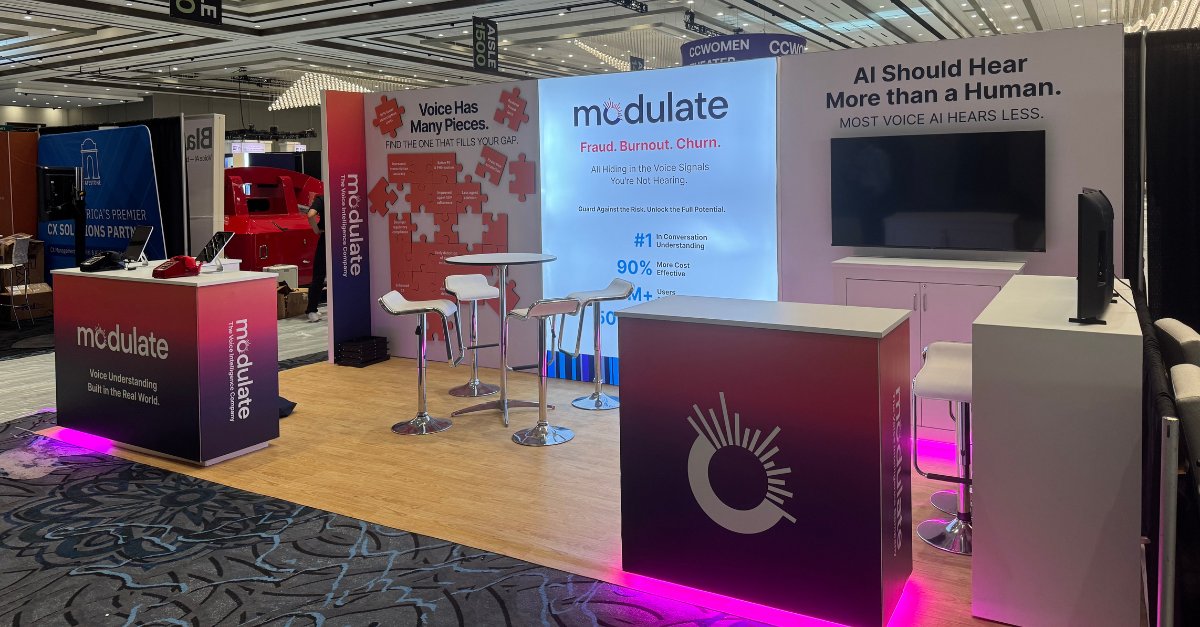
We're all set for @CustContactWeek and excited to meet everyone at Booth #1738 📍
Come see how Modulate is helping organizations move beyond transcripts and unlock the full context, emotion, and meaning behind every conversation.
Swing by, say hello, and let's talk about the future of voice AI! 🙌
#CCWVegas
We’re heading to CCW 2026 🙌
If you're attending, stop by and meet the team to see how Modulate is helping organizations unlock deeper voice intelligence, real-time insights, and better customer conversations.
See you there!
Ever misread someone just because of their tone? 😶
Now imagine that at scale - with AI.
In this clip, our CEO @mpappas74 gets into why voice isn’t just words. It’s pauses, emphasis, emotion - all the subtle signals people naturally interpret.
Miss that, and you’re misinterpreting the conversation itself.
That’s the layer we focus on at @modulate_ai - not just the spoke word, but the entirety of the conversation.
The world's first audio-native AI model is now available as an API.
Velma listens and understands like a human — emotions, tone, intent, rhythm, vocal stress.
Already analyzed 550M+ hours of conversation for Fortune 500s.
Now open to developers. 🧵
The AI playbook says: more data, more compute, bigger models.
We don’t buy it.
At Modulate, this is how we think + how we build.
In this clip, our CEO @mpappas74 breaks down why focused data + real insight beats brute force.
We’re a team of ~40, and that approach has led to:
- Transcription models outperforming @OpenAI on accuracy
- Deepfake detection models topping the @huggingface speech arena leaderboard
Not by hoovering the internet. By using the right data.
Because better > bigger.
We’re @hackernoon Company of the Week
Voice AI breaks down when things get real: messy audio, emotion, overlap, intent.
So we built Velma - the first Ensemble Listening Model, trained on 550M hours of real-world audio, designed to understand speech as it actually happens (not sanitized benchmarks).
And ToxMod - real-time voice moderation that detects how something is said, not just the words.
This isn’t research. It’s deployed at scale across Fortune 500 platforms today 🌐
Voice is the hardest problem in AI. It’s also the most human.
We’re building the infrastructure to make it work -safely, accurately, in real time.
Hosting a deepfake happy hour at #BOSTechWeek this May
Real vs synthetic audio
Most people get it wrong
Come try 👀
May 28, Boston
RSVP: https://t.co/5cWHLkk7zc
@Techweek_
Deepfakes are getting cheaper to create.
Detection shouldn’t be 100x more expensive.
We just flipped the equation.
Stop deepfakes for $0.25/hr - now at cost parity with creation ⚖️