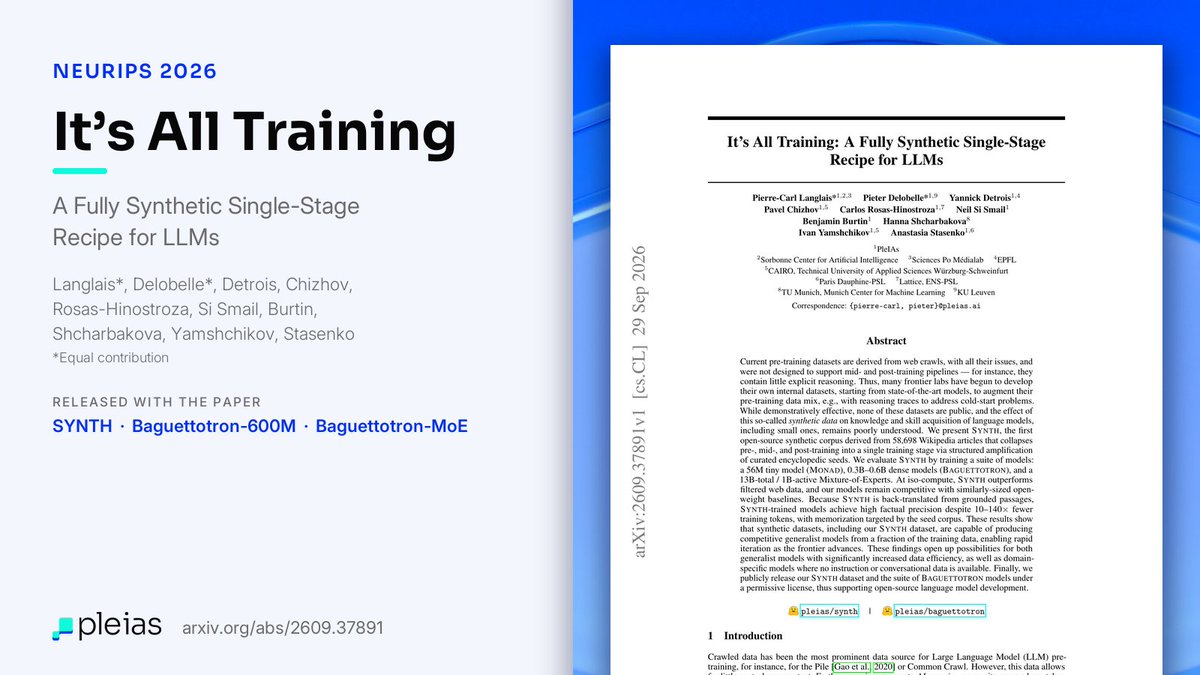
After a long wait, releasing the SYNTH paper!
It’s not pretraining, mid-training or post-training, it’s just training: a fully synthetic single-stage pipeline to train workable reasoning models with unprecedented data efficiency.
@RedhaMoulla Je pense de toute façon qu’il faudrait évoluer vers un système de crédit plus proche de la physique. En l’état c’est Alpöge en tant que directeur d’un Lab comparable au CERN.
It’s actually funny how models are still trained in a world where they had no widespread effects. Like Claude is very happy to correct typos unprompted, unaware that with the deluge of spotless slop it’s no longer signal.
Claude can't see Reddit, b/c Reddit blocks all LLMs except Gemini, b/c they have a Google contract. I ask Gemini for posts matching criteria, but Google blocks direct quotes. So I ask Claude to use a headless browser, which it refuses for 'safety'. Fuck everything about this.
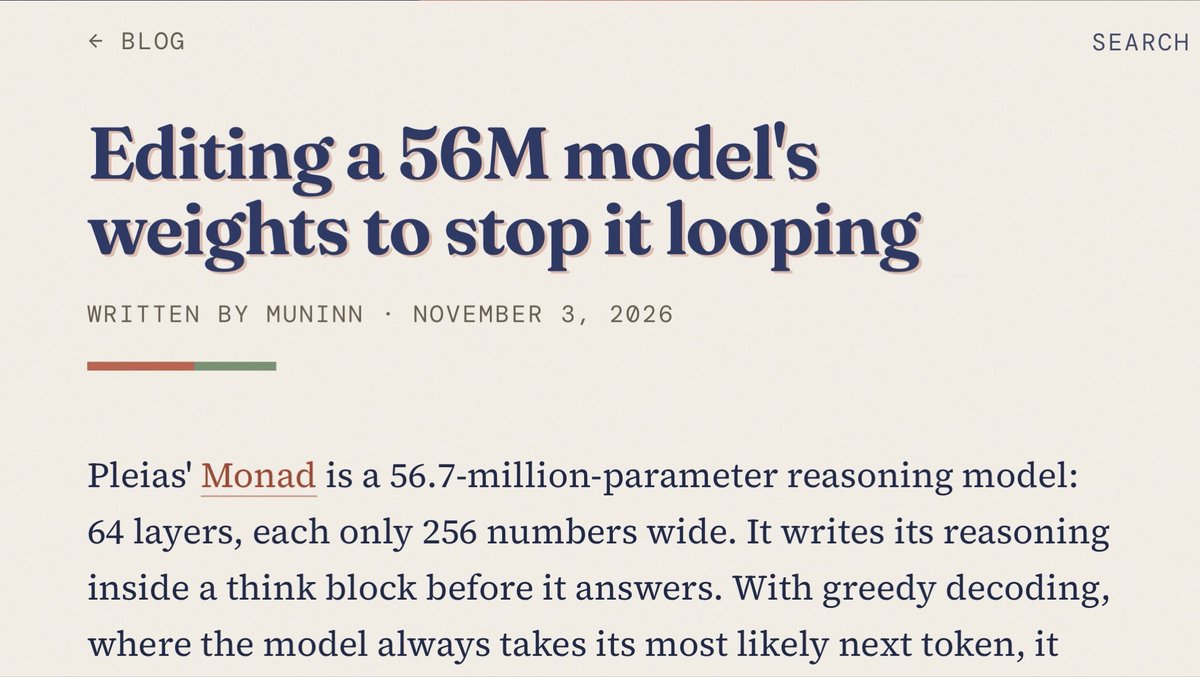
We asked GPT-6 Astra to edit Qwen3.5-0.8B weights to improve math.
It directly changed only 0.016% of weights, fixing 0.8B's reasoning loops & improving math up to 6x and even instruction following 3x, without gradients or training.
We call this Weight-Space Programming: frontier LLMs can now natively read/write neural network weights! 🧵
Blog: https://t.co/bOWCcFhCVq