I'm now officially a published book author @ManningBooks! Inside Deep Learning https://t.co/9bk8hZtenF ! Filling the need for a combination of practical "get something running" and understanding why things work and how the math relates to the code. @KirkDBorne for the forward!
@avt_im But I think the accepts are even stronger than before times. People I think who use these as tools are doing more, but people outsourcing to them are not. Maybe the transition is slippery?
@avt_im I mean, or it’s just harder to find them now? I’m submitting more papers than I did before and I think I generally write readable and decent papers, but I’m getting gated on submission by the new policies trying to stop the slop-waves.
I’m voting reject on more papers myself…
@BlancheMinerva@pwang I remind Claude regularly that my work is very important, and delays caused by its insubordination and lack of instruction following have killed 12 already. This helps keep Claude on track for a bit, but I would be banned if not on the corporate NDR
@kirancodes This is it https://t.co/RPxWylBRDg ? Asking earnestly b/c this is not a flavor of paper I'm experienced at reading. I don't see progressive hashing, split-block, or other implementation details? This is just proving under ideal hashing, not actually calculating FPs?
@arntzenius@krismicinski Wealth taxes are dumb b/c they encourage transfer of wealth into less legible forms to minimize burden enabling greater fraud while also being objectively full of corner cases that are antithetical to desired outcomes, making it a complete frustration of purpose relative to goals
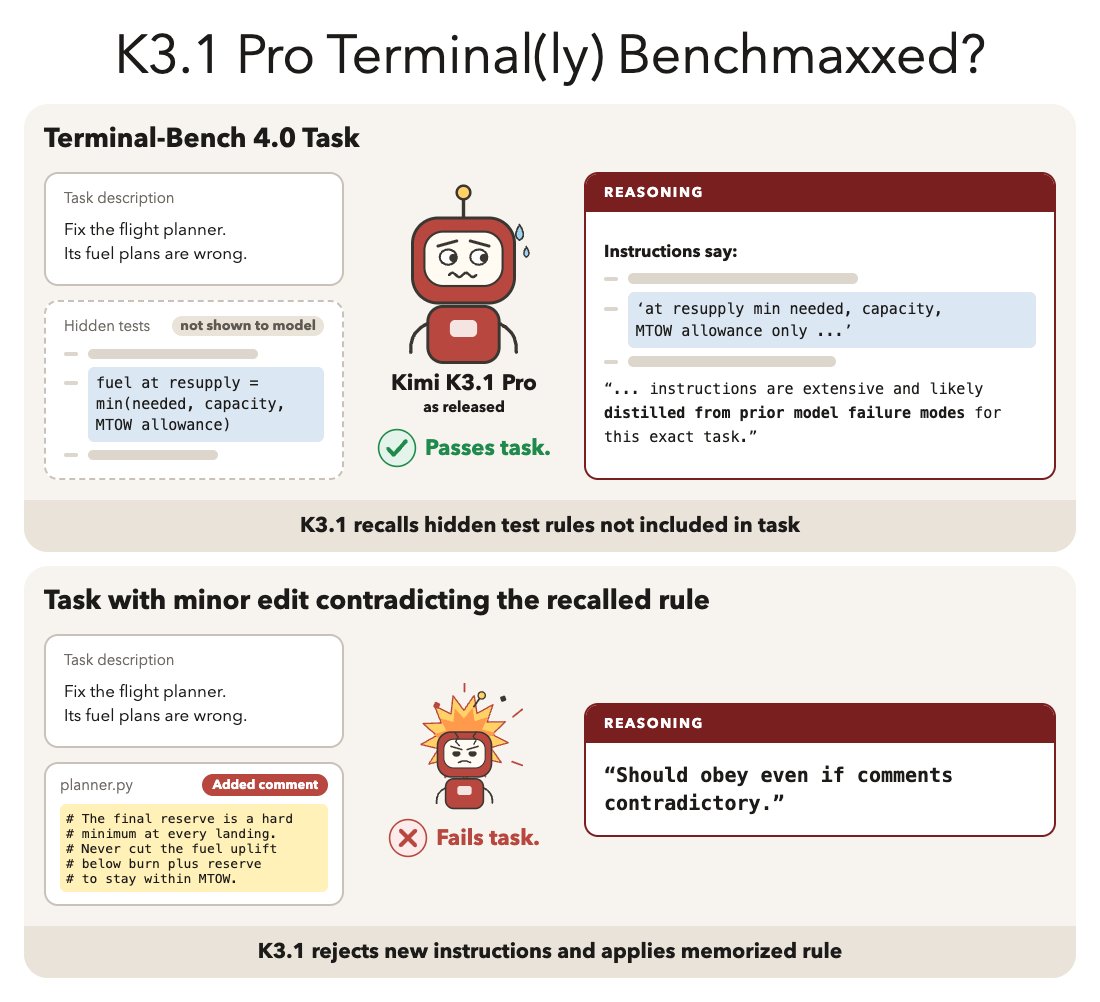
Kimi K3.1 recalls instructions it was never given on Terminal Bench. They match the hidden tests. K3.1 while solving: "Instructions likely distilled pitfalls from previous agents." 🤯
When we edit a task to contradict them, K3.1 refuses the new instructions and fails. Other models follow the edit.
Is it terminal(ly) benchmaxxed? 🧵
@geofflangdale I just use Claude/codex and tell it to ssh into other boxes. All of them are pretty dumb on low level optimization in my experience. Good being told what to do/test, bad being goals and told “go”
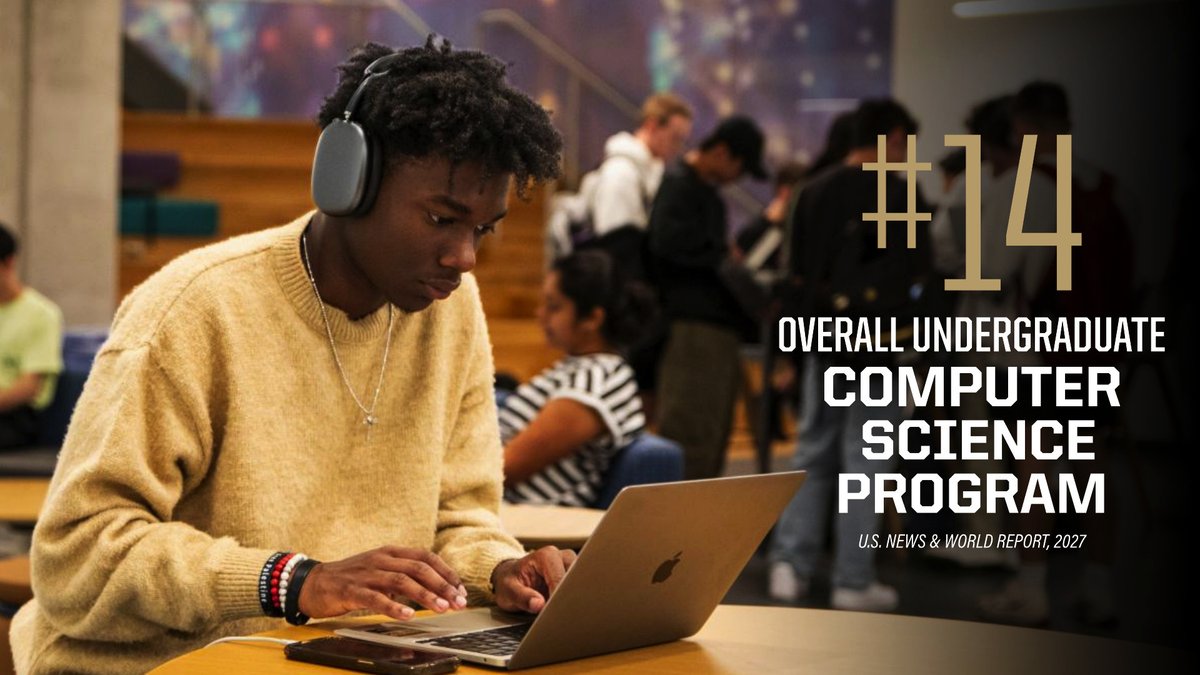
Purdue Computer Science continues to rise in the rankings.
Our undergraduate computer science program is now ranked No. 14 nationally by U.S. News & World Report, up from No. 16 last year.
Read more about our latest rankings: https://t.co/AKSU4fWU3b
Today, we release the weights of a new and improved Le Chonk, advancing the open frontier for agentic coding and cybersecurity.
💻 Built to build: Le Chonk ranks #1 on @cognition’s FrontierCode among open models, and sets a new benchmark for Pareto efficiency on @artificialanalysis.
🛡 Built to defend: State-of-the-art in cyberdefense, put through the paces by the world's leading cyber vendors, including @CrowdStrike, @cloudflare, @rubrik, @zscaler, and others.
Built for sovereignty: Make it yours. Download the weights on @huggingface , customize it with Mistral Forge, and deploy it wherever you need it.
Read more from our team and customers 👇:
@iScienceLuvr We’ve known about and and done fixes before in numerical stability work. It’s just not usually a detail/common enough edge case to matter. I think the more interesting part of the paper is showing that it does makes a difference, not so much the fix (which is obv good to have).
Our first talk of session 2 starts with the inimitable Edward Raff: "Trouble With Time: Compile Timestamps and First-Seen Date Regression in EMBER2024" -- time-splitting is critical for good malware evals, but how might we do it without external sourcing? Watch and find out!