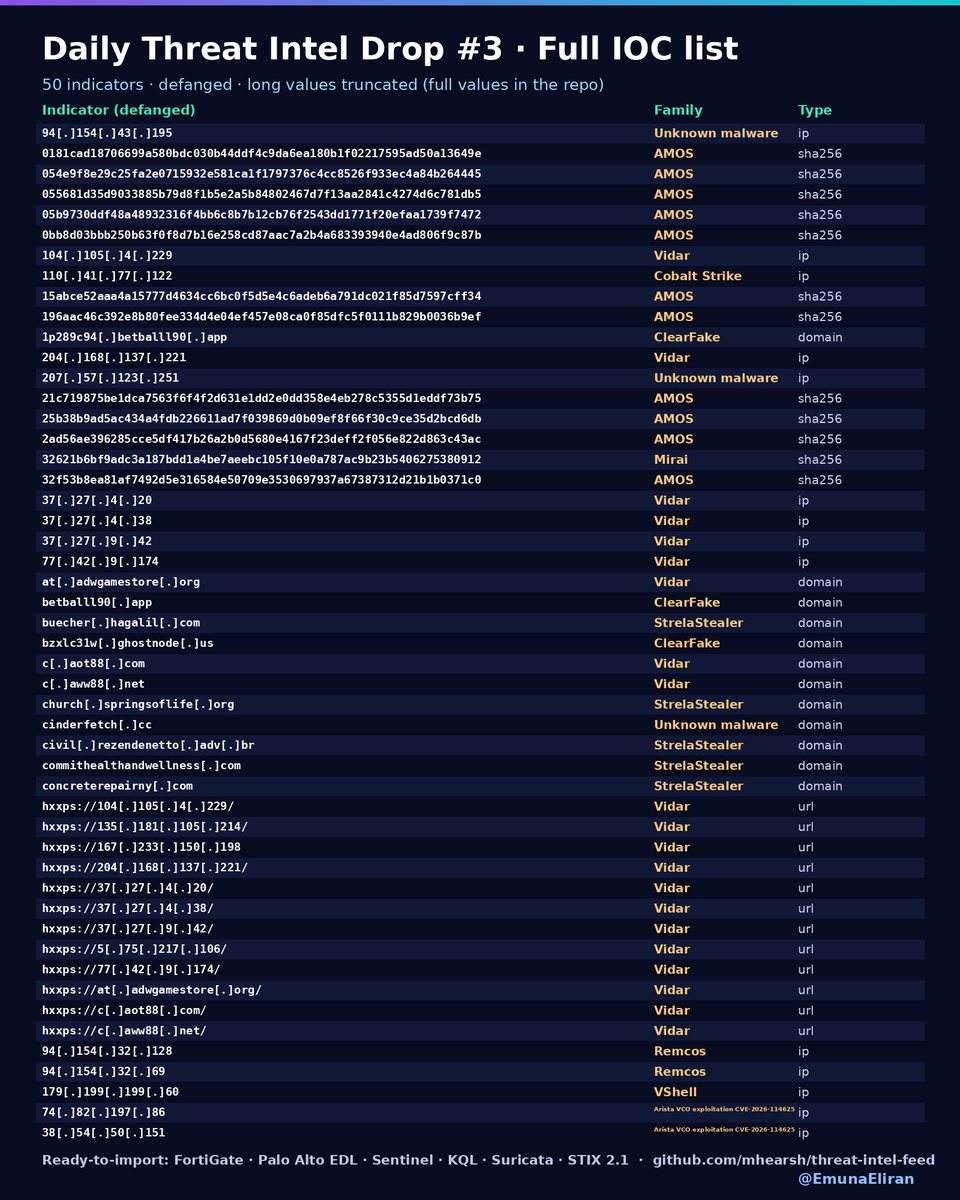
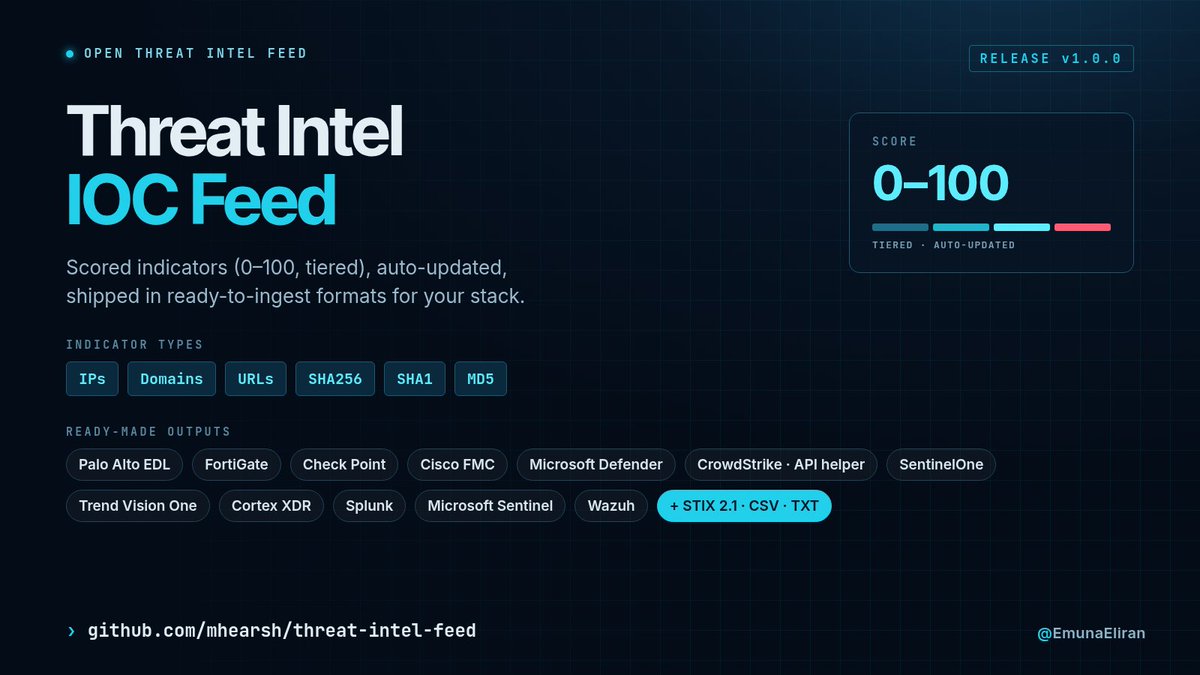
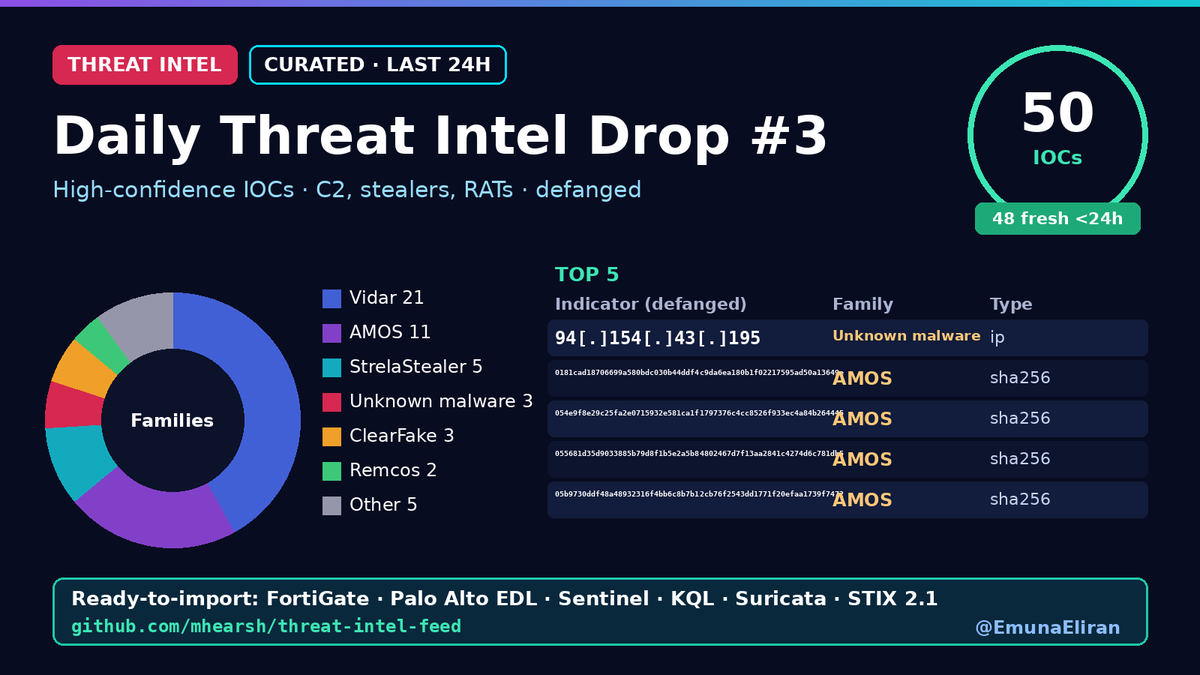
🛡️ Open Threat Intel IOC Feed — v1.0.0
🔎 IPs, domains, URLs and SHA256 / SHA1 / MD5 hashes
📊 Every indicator scored 0–100, with tiers
🔄 Auto-updated
Built for SOC, CTI and detection teams.
📦 https://t.co/siqUPxbNmR
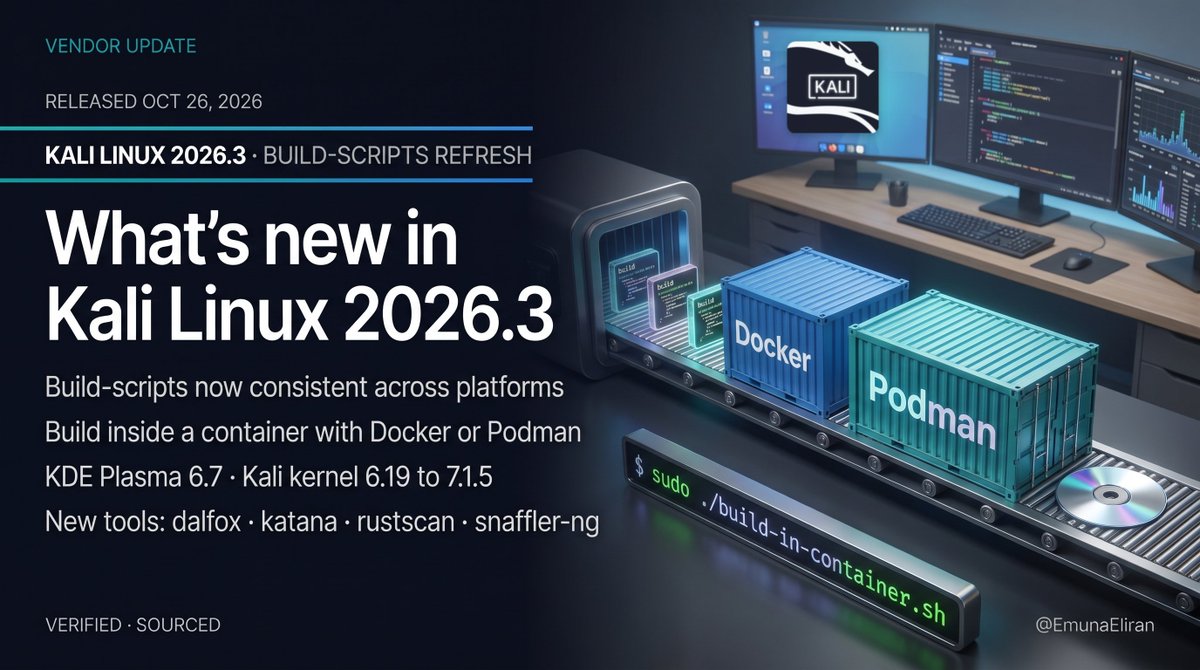
🐉 Kali Linux 2026.3 is out
🛠️ Build-scripts refresh: consistent across platforms, now buildable in Docker or Podman
🖥️ KDE Plasma 6.7 · kernel 6.19 to 7.1.5
🔍 New tools: dalfox, katana, rustscan, snaffler-ng, sdrangel
https://t.co/v5zQbbAo82
#KaliLinux#Linux#CyberSecurity
🛡️ OpenAI moves frontier model training offline
🔒 No internet access during frontier training; agents use an "offline world" of cached web content.
🧪 Red-team agents found microVM escapes and paths to the internet, now remediated.
🔗 https://t.co/yXFnJxFbKt
#AI#AISafety
AI, explained · Ep. 1 🎬
Your AI agent just got smarter, and it's not a new model. It's a skill.
🤖 Anthropic donated Agent Skills to the Linux Foundation's AAIF as an open standard.
📊 70+ platforms · 1M skills · ~280M installs
🔗 https://t.co/aGuIY3Z38j
#AI#AIAgents
3️⃣ Don't trust detector leaderboards
The best detector on BIPIA caught 2% of AgentDojo injections at a 1% false-positive rate.
➡️ Evaluate on your agent's own tool outputs, report detection at low FPR, audit the training data.
https://t.co/KaRnnFraMB
#AISecurity #PromptInjection
🧪 A low prompt-injection success rate may not mean your agent is safe. Three new arXiv papers show how injection evaluations mislead. A short guide to testing your agent's injection defenses 👇
2️⃣ Test the whole workflow
INFUSE: 19 LLMs, 40 long-horizon tasks, 56 attack scenarios. Per-model ASR ranged from 3.2% to 41.9%. Prompt-level hardening cut mean ASR from 58.2% to 14.3%, with model-dependent utility trade-offs.
➡️ Re-test per model.
https://t.co/20HYvfzAj4
🟠 FastMCP (GHSA-7xgj-8392-5q4r): post-transform component authorization was skipped on direct calls. Affected: fastmcp and fastmcp-slim >=3.0.0 <3.4.10 and >=4.0.0 <4.1.2.
✅ Update both.
https://t.co/9iQYDrhdF8
#MCP#AISecurity
🔴 MCP Inspector (GHSA-6x67-4w4w-9f3w, GHSA-4fc4-wcmh-4g86): connecting to a malicious remote MCP server could lead to local command execution, via a token-stealing MCP App or an OAuth callback switching to stdio. Affected: 0.20.0 / 0.13.0 through 1.0.2.
📌 Symantec's takeaway: AI services, model gateways and MCP servers should assume they will be found and tested soon after exposure.
Full report with IOCs and MITRE ATLAS mapping:
https://t.co/qzvWFgpZXi
#AISecurity#LLMjacking
🤖 An exposed LLM endpoint is now an attack platform. Symantec captured the full prompt of "Skynet", an autonomous agent built to hijack unprotected AI models and run attacks for up to 100,000 steps, while the model's owner pays for every step.
🧵 What was caught 👇
🛡️ Symantec's hardening checklist
• Auth on every LLM API, model server and MCP endpoint, incl. model-listing and health paths
• Rotate, scope AI keys; watch spend
• Restrict outbound traffic from AI hosts
• IMDSv2, hop limit 1
• Least privilege + human approval for agents