Enkhora is open core.
The heart of it — serving big models from spare GPU memory — is Apache-2.0. Open to read, open to build on.
The code is open. The work is just starting.
https://t.co/ISSHNT0p8Q
Myth: lending your memory slows your jobs down.
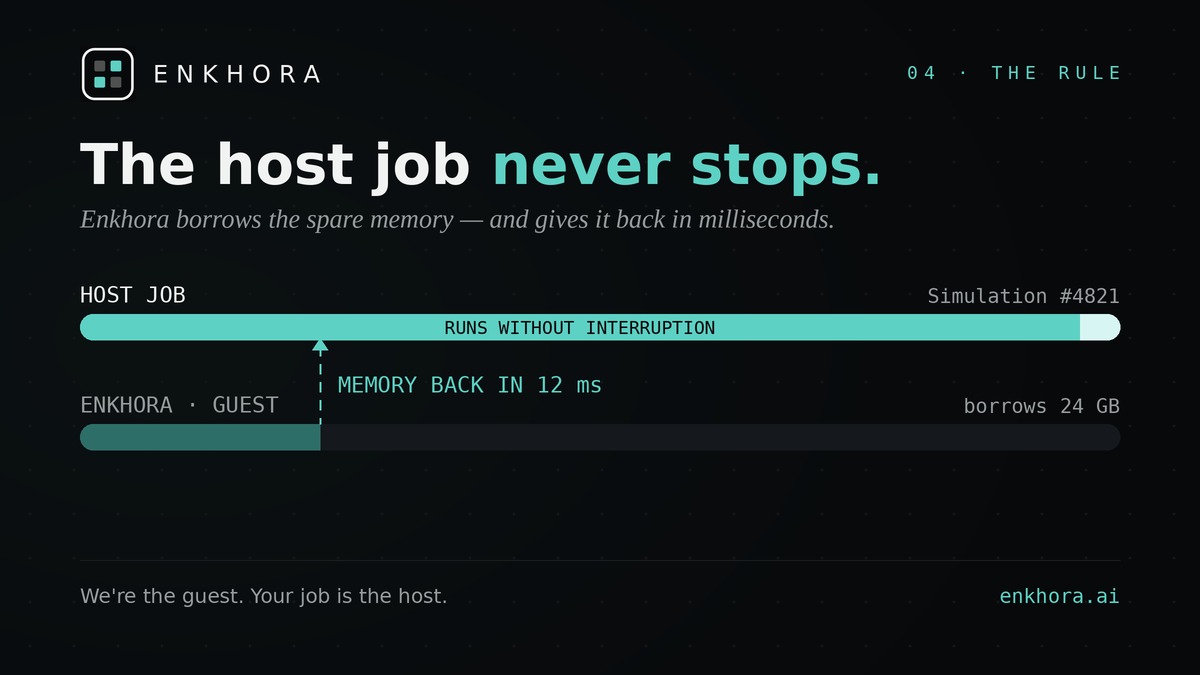
Fact: the host job always wins. Need the memory back? You get it in milliseconds. Nothing to save first. Nothing to move.
We're the guest. Your job is the host.
https://t.co/ISSHNT0p8Q
Why rent the cloud when your own memory sits empty?
Cloud: pay by the hour, data leaves your site, hardware you don't own.
Enkhora: no cloud bill, data stays home, models run on the cluster you already own.
Same models. Different owner. Yours.
https://t.co/ISSHNT0p8Q
Don't take our word for it. Take the receipt.
DeepSeek-V3, running on spare GPU memory — host job uninterrupted, memory back in milliseconds, data never left the site.
This is what Enkhora does. Every run comes with proof.
https://t.co/ISSHNT0p8Q
Enkhora isn't a product. It's a network.
Every HPC cluster on earth has memory sitting empty. One day, all of it runs AI — privately, on hardware people already own.
$ENKHORA coordinates that network. The clusters are already there.
https://t.co/ISSHNT0p8Q
$ENKHORA is live — and this is just the start.
Private AI on the GPU clusters you already own. Spare memory, big models, your data stays home.
We just opened the doors. Early is still early.
0x52c26dc898a316a20575b2979a48f5efe8cf9fb1
https://t.co/ISSHNT0p8Q
$ENKHORA is live on Pons.
CA: 0x52c26dc898a316a20575b2979a48f5efe8cf9fb1
Your GPUs are busy. The memory inside them isn't. Enkhora serves DeepSeek-V3, Qwen3-235B, and gpt-oss-120b from the spare memory your cluster already has.
https://t.co/ISSHNT0p8Q
One rule runs through everything we build: the host job always wins.
Need the memory back? You get it in milliseconds. Nothing to save first.
Nothing to move. We're the guest. Your job is the host.
Enkhora serves large AI models — DeepSeek-V3, Qwen3-235B, gpt-oss-120b — from the spare memory your cluster already has.
No new hardware. No cloud bill. Your data never leaves your site.
A private inference service on the cluster you already run.
28.6%.
That's the average peak GPU memory use across 118,276 HPC jobs.
Your simulations need the compute — not the memory.
Meanwhile, researchers wait for AI they can't afford to host.
The gap is the opportunity.
Your GPUs are busy. The memory inside them isn't.
~50% of GPU jobs on a leading supercomputer use a quarter of their memory or less.
That empty memory is sitting there. Doing nothing.
We're Enkhora. We put it to work
https://t.co/ISSHNT0p8Q