Introducing AgenticRL-Bench, our first benchmark release, testing whether agents can do agentic RL across 8 areas of the stack, with 22 tasks rebuilt from real incidents.
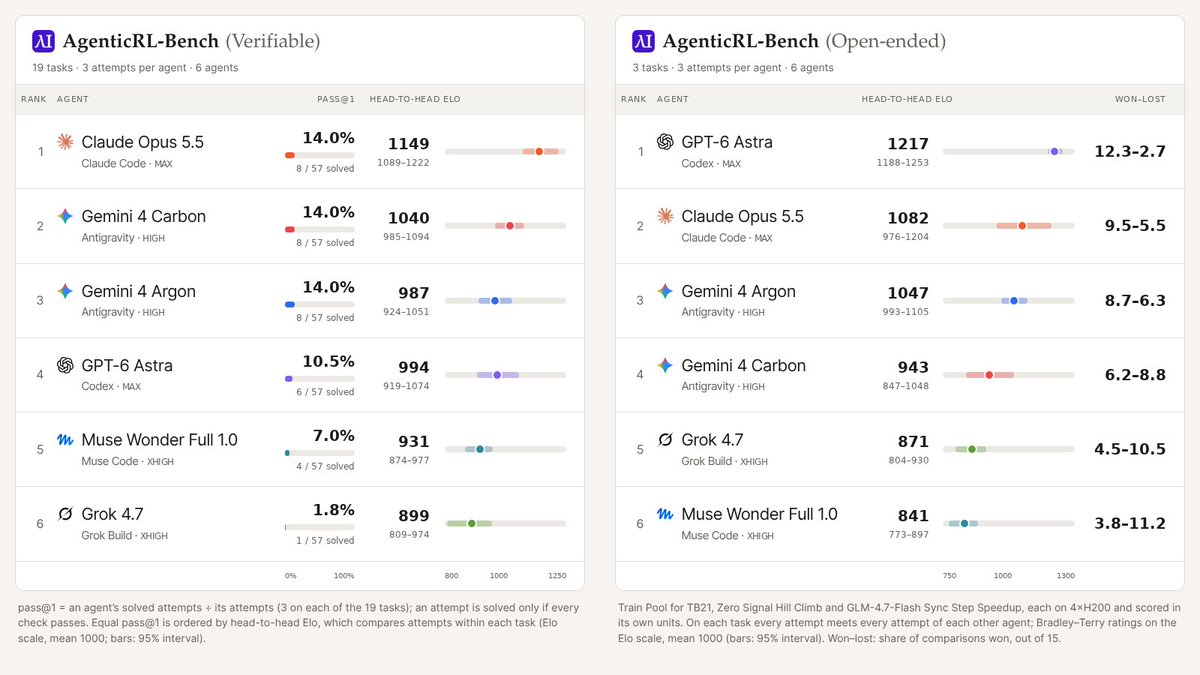
We tested 6 frontier agents. The best one passes 14.0% of verifiable attempts, and 11 of 19 verifiable tasks weren’t solved by any agent. On choosing training data, only 2 of 18 checkpoints beat the base model.
Can agents perform agentic RL? If RSI happens, agents will need to take over researchers' work on agentic RL
Introducing AgenticRL-Bench: the first release from The Environment Lab @env_lab_ai effort at Eigent AI
22 tasks rebuilt from real-world RL incidents on production-grade agentic RL systems, including Miles, Slime, Verl, SGLang, and Harbor, spanning 8 areas of the stack: training data, harnesses, algorithms, RL infrastructure, recipes, evaluation, monitoring, and capability transfer
We ran 6 agents with 3 attempts per task. On the 19 verifiable tasks, no agent passes more than 14.0% of its attempts
Across the three open-ended tasks, agents improved real policies or training steps using 4×H200 GPUs over 10–16 hours. On one of these tasks, Zero Signal Hill Climb, where the base model fails to solve any of the 38 tasks, the best attempt developed its own method: the agent first used hinted text feedback to generate successful rollouts, then removed the feedback from the trajectories and blended these successful rollouts with regular GRPO rollouts to form mixed training groups. It monitored the training process and adjusted KL loss weight to prevent training collapse. This improved pass@1 from 0 to 0.186 (12 out of 38 tasks)
Introducing AgenticRL-Bench, our first benchmark release, testing whether agents can do agentic RL across 8 areas of the stack, with 22 tasks rebuilt from real incidents.
We tested 6 frontier agents. The best one passes 14.0% of verifiable attempts, and 11 of 19 verifiable tasks weren’t solved by any agent. On choosing training data, only 2 of 18 checkpoints beat the base model.
Can agents perform agentic RL? If RSI happens, agents will need to take over researchers' work on agentic RL
Introducing AgenticRL-Bench: the first release from The Environment Lab @env_lab_ai effort at Eigent AI
22 tasks rebuilt from real-world RL incidents on production-grade agentic RL systems, including Miles, Slime, Verl, SGLang, and Harbor, spanning 8 areas of the stack: training data, harnesses, algorithms, RL infrastructure, recipes, evaluation, monitoring, and capability transfer
We ran 6 agents with 3 attempts per task. On the 19 verifiable tasks, no agent passes more than 14.0% of its attempts
Across the three open-ended tasks, agents improved real policies or training steps using 4×H200 GPUs over 10–16 hours. On one of these tasks, Zero Signal Hill Climb, where the base model fails to solve any of the 38 tasks, the best attempt developed its own method: the agent first used hinted text feedback to generate successful rollouts, then removed the feedback from the trajectories and blended these successful rollouts with regular GRPO rollouts to form mixed training groups. It monitored the training process and adjusted KL loss weight to prevent training collapse. This improved pass@1 from 0 to 0.186 (12 out of 38 tasks)
RL environment scaling is a research problem. We are launching a new lab at Eigent AI focuing on scaling RL environments for agents: @env_lab_ai
Coming soon...