You can now mod Claude Code:
- Change how it behaves
- Customize the UI
- Swap in your own features
Write one with a few lines of TypeScript, or have Claude build it for you. Mods ship inside plugins, so you install them with /plugin in the CLI or desktop app.
A few examples:
@TokenGremlin I think there isn't a chance in hell Google's going to release a model that beats an Anthropic or OpenAI model on real benchmarks, not just Google's benchmarks.
@Da7_Tech It's like a reoccurring nightmare. Same thing happened with 3.5 Pro, only it was never announced, but we started getting benchmarks of it everywhere. This is a new scenario where they actually announce it, but still, there's nothing tangible for us to use.
JUST IN: Anthropic co-founder Daniela Amodei & her husband reportedly used a “personal advisory council” of stuffed animals with distinct personalities to work through workplace conflicts.
If these rumors turn out to be true, I will honestly be disappointed. I've been rooting for Google to actually compete with the top frontier models. But it's rough. The more companies we have releasing models that actually compete with Anthropic and OpenAI models, the better it is for the end consumer. But I have to say, even though these are only rumors, they line up with Google's previous releases, so I won't be surprised if they turn out to be true.
Fingers crossed that these rumors aren't true!
via Bloomberg
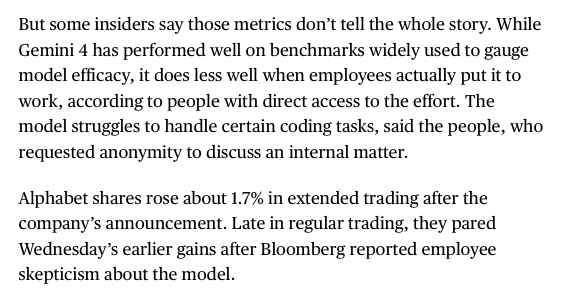
"But some insiders say those metrics don’t tell the whole story. While Gemini 4 has performed well on benchmarks widely used to gauge model efficacy, it does less well when employees actually put it to work, according to people with direct access to the effort.
The model struggles to handle certain coding tasks, said the people, who requested anonymity to discuss an internal matter."
This is a reminder for everyone getting excited about Gemini 4 Argon to scroll through the history books at Google's previous releases. They don't have the best track record..........
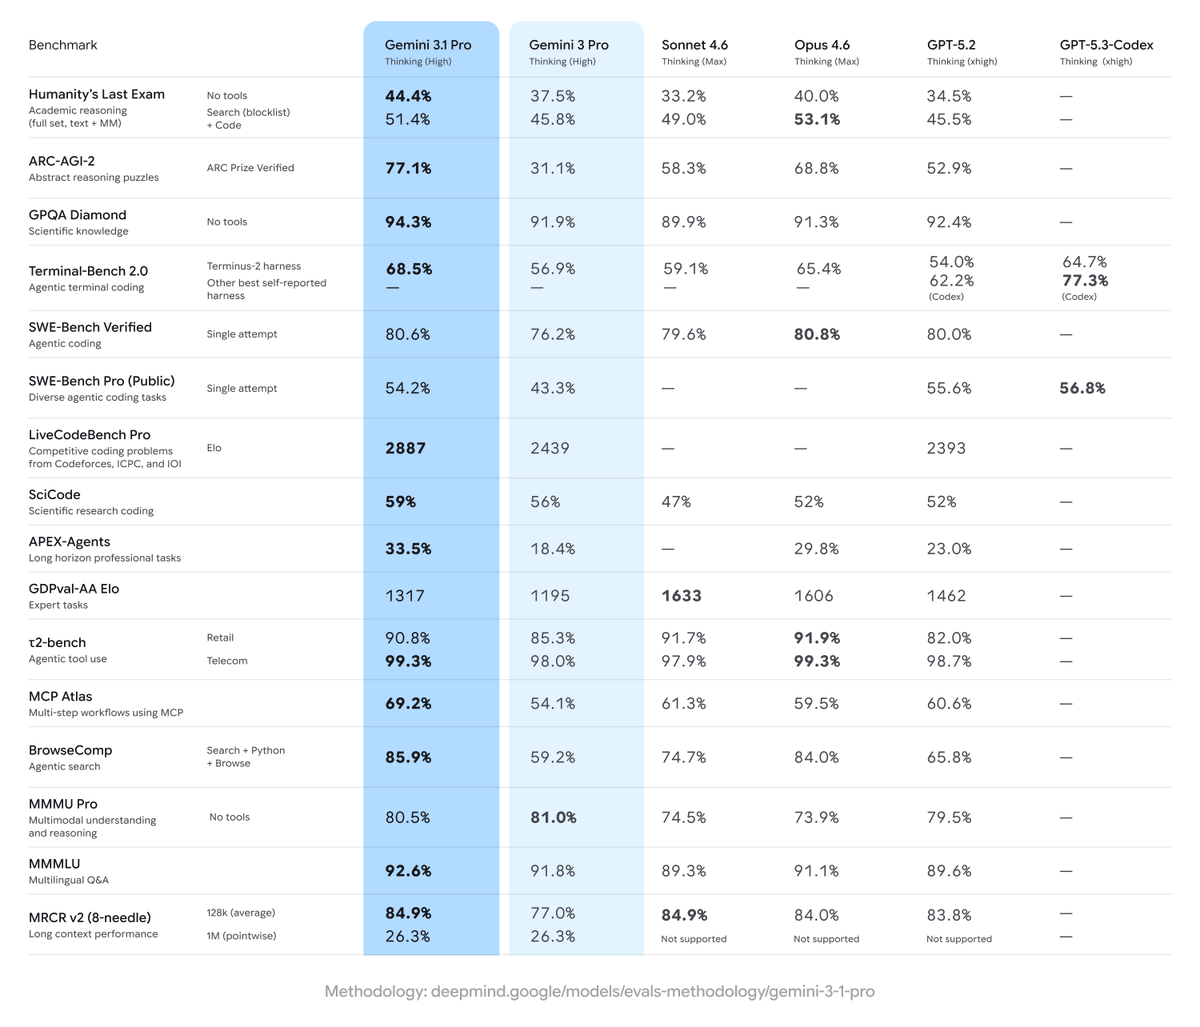
btw these were the official benchmarks for Gemini 3.1 Pro when it released, practically destroying Opus 4.6 across the board.
I'm not saying Gemini 4 Argon will be bad, but it's crazy that no one has the slightest bit of skepticism given Google's track record.
I'm glad I'm not the only one who has noticed that Gemini 4 Argon is all over social media. It's been announced, and everyone's talking about it, yet no one I know or work with can use it yet.
it's mind-boggling google would publicly announce something the public cannot use
like.. why would someone scream "I'M NOT BEHIND" from behind?
but then i just realized - October is about time people in google start writing their performance review packets...
@VilleCrypto@ConnorTalksAI Again, it's crazy how everyone is having different experiences, because I've had Opus 5.5 on Ultra Code running in different sessions for over 12 hours each. One session ran for over 30 hours. And all of those sessions combined didn't consume more than 20% of my weekly quota.
@99Oatz@ConnorTalksAI That's honestly crazy because I'm having the exact opposite experience. I believe you, but I guess that just shows how nuanced this topic is.
wait. did i read that right?
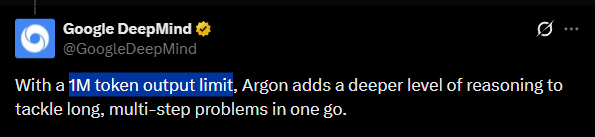
gemini 4 argon has a 1M token output limit.
let me repeat. not a 1M context window. a 1M token output limit.
that means, it can write up to a million tokens in a single response.
i got confused too at first. for context, most frontier models cap output somewhere around 128k.
that's madness.