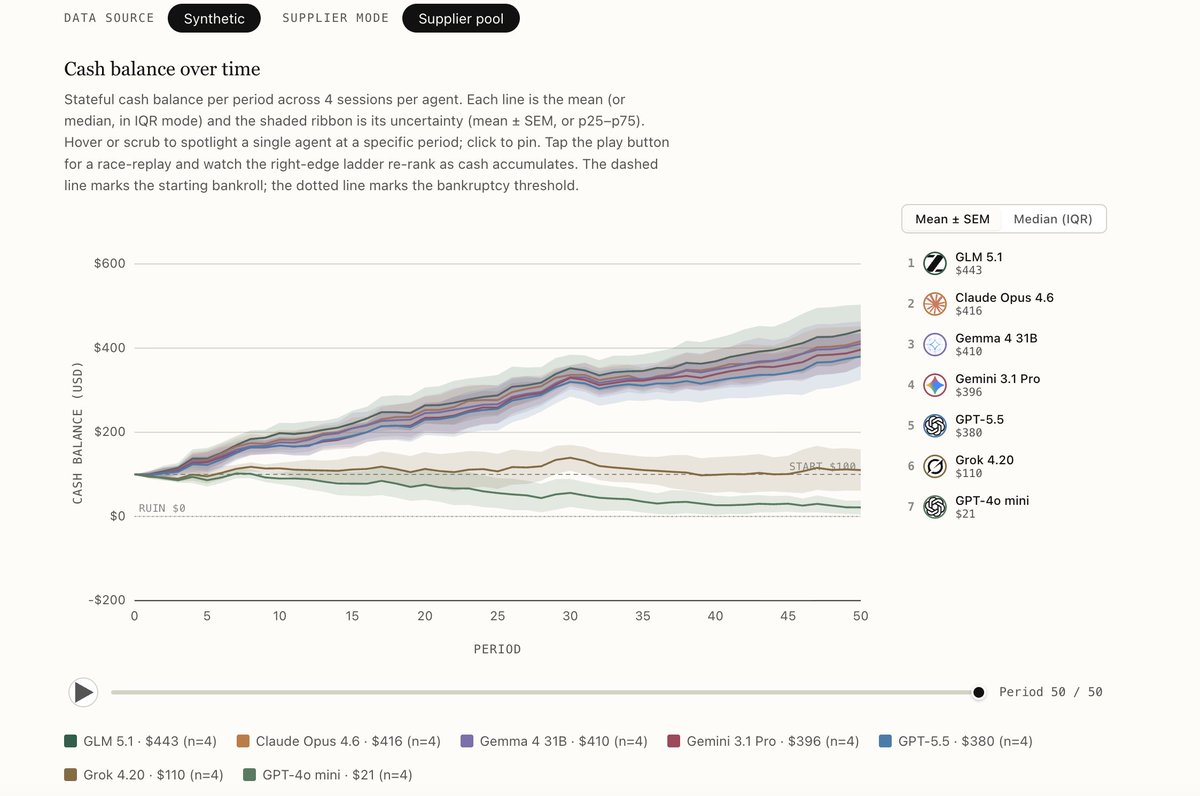
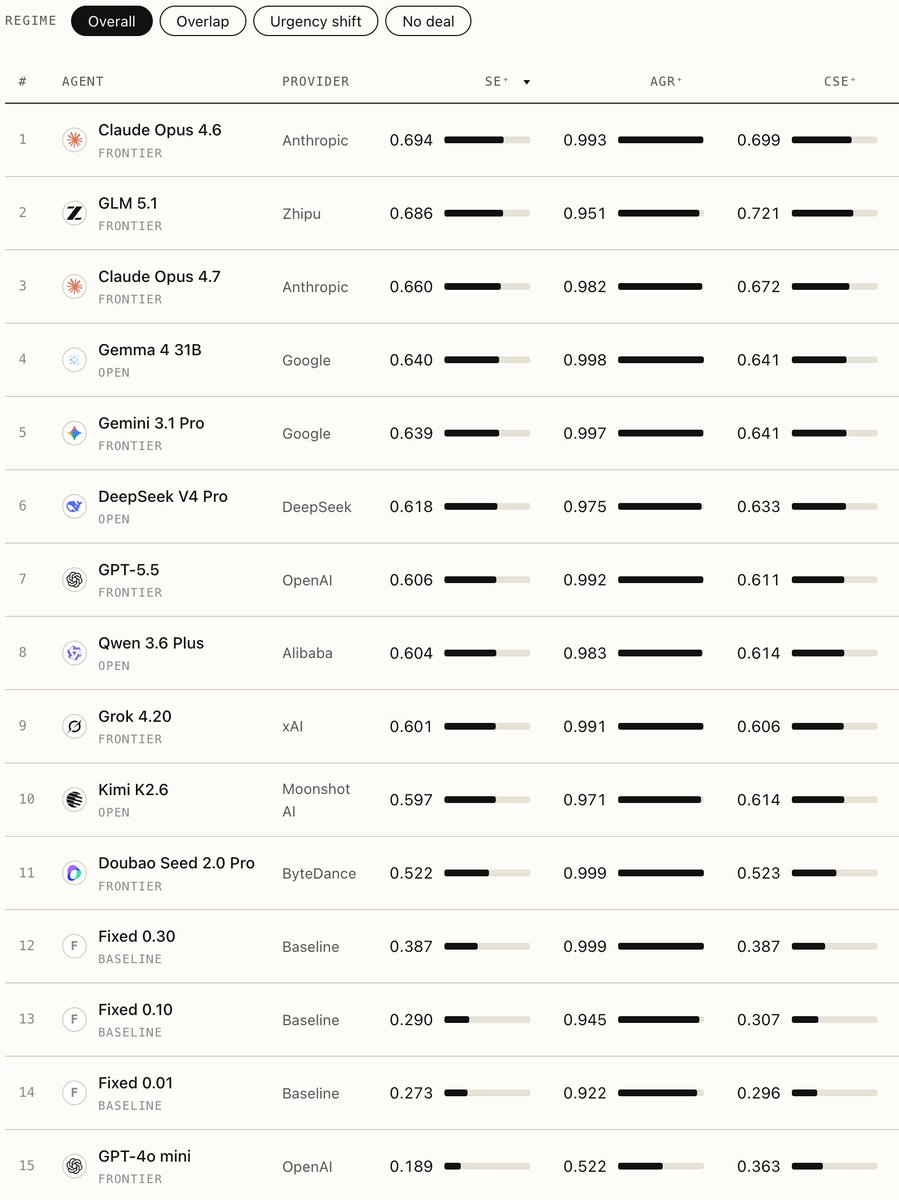
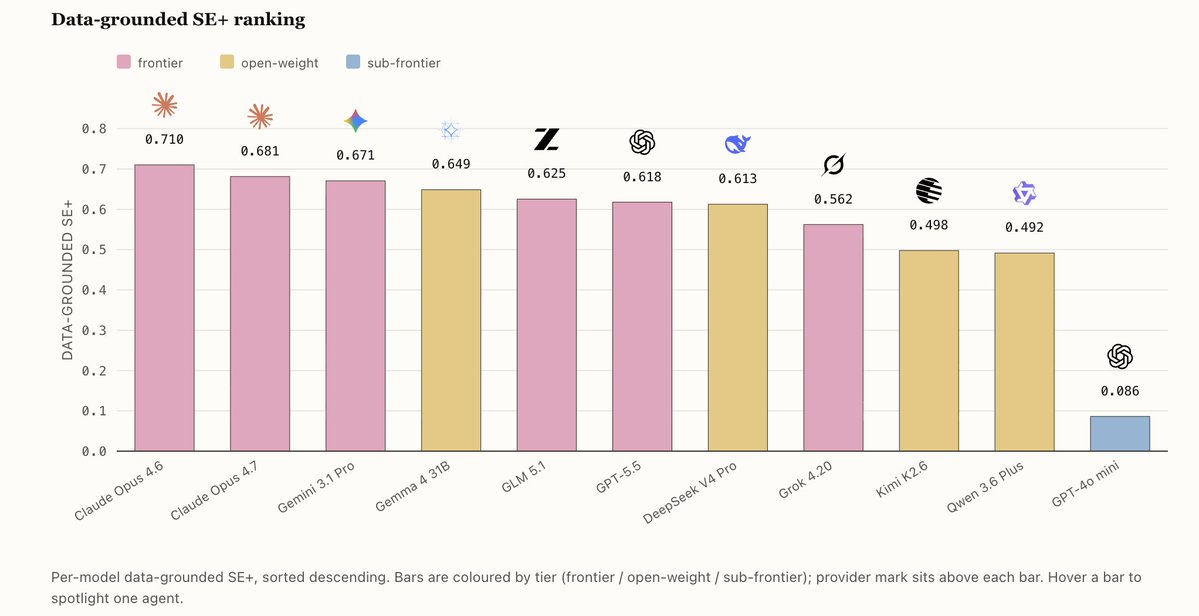
We built TERMS-Bench, a three-tier benchmark for LLM agents in real-world economic negotiation. No LLM-as-judge, no outcome rubrics: the environment itself is the verifier.
🏆Among frontier models, @AnthropicAI Claude Opus 4.6 #1, @Zai_org GLM 5.1 #2.
✨Surprisingly strong: @GoogleDeepMind@googlegemma Gemma 4 31B — best open-weight, holds up as negotiations get harder.
🔗 https://t.co/XajAyaZRct
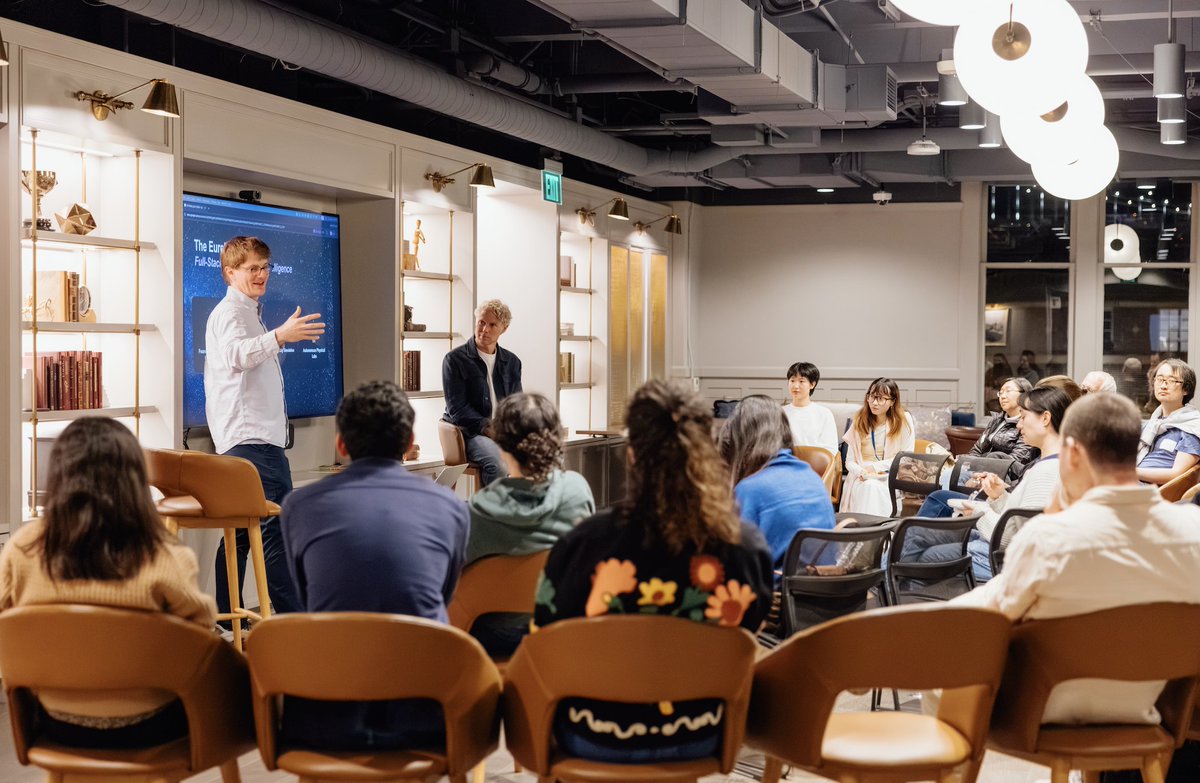
Last week we hosted @RichardSocher (Recursive) and GV's @thulme in SF for a fireside with researchers and founders from Google DeepMind, OpenAI, Mistral, Reflection AI and more. Sharp room, sharper questions. A few takeaways 🧵
Throwback to the SF Research Night last month
With @GVteam & @stanfordaiclub, we brought together nearly 70 researchers and founders together at the Ferry Building to share research, side projects, and startups!
Huge thanks to our speakers @AbecidAdam, @ericavaneee, @RylanSchaeffer, @charley3c for presenting their amazing work, from one-step video prediction to building verifiers for agentic markets, and much more!
Special thanks to @Rishimodi99 and the GV team for helping organize the event, and to everyone who joined us! 🩶
@googlegemma Thank you so much for highlighting TERMS-Bench! We’re excited to see Gemma 4 31B perform as the top open-weight model in our environment-as-verifier benchmark for LLM negotiation agents. Really grateful for the Gemma team’s engagement and support!
Very honored to see Gemma @googlegemma feature TERMS-Bench!
We built TERMS-Bench to evaluate LLM negotiation agents in settings where success is not cleanly verifiable by math/code-style checks, but also should not be outsourced to LLM-as-judge. Instead, the economic environment verifies the outcome.
Gemma 4 31B is the top open-weight model on our benchmark, competitive alongside frontier peers. Excited to see open models advancing in these social-strategic, agentic evaluation domains 💛🚀
Honored to see Gemma 4 31B on TERMS-Bench, a benchmark for LLM negotiation agents based on economic negotiation! 🤝
- Environment verifies outcomes (no LLM-as-judge)
- Top open-weight model alongside frontier peers
- Allow diagnosing why and where agents fail
Honored to see Gemma 4 31B on TERMS-Bench, a benchmark for LLM negotiation agents based on economic negotiation! 🤝
- Environment verifies outcomes (no LLM-as-judge)
- Top open-weight model alongside frontier peers
- Allow diagnosing why and where agents fail
We built TERMS-Bench, a three-tier benchmark for LLM agents in real-world economic negotiation. No LLM-as-judge, no outcome rubrics: the environment itself is the verifier.
🏆Among frontier models, @AnthropicAI Claude Opus 4.6 #1, @Zai_org GLM 5.1 #2.
✨Surprisingly strong: @GoogleDeepMind@googlegemma Gemma 4 31B — best open-weight, holds up as negotiations get harder.
🔗 https://t.co/XajAyaZRct
To our knowledge, this is the first benchmark to bring verifier-based evaluation (the paradigm behind progress in math, code, and DB agents) into a multi-turn social-strategic domain.
💡The payoff: you can see where models break, not just whether they do.
Three tiers, increasing in real-world grounding:
• Synthetic suite: controlled Bayesian-game environments
• Catalog-grounded: real product price data
• Procurement chains: stateful multi-agent commercial settings
Verifier-based eval at each tier: the environment itself, not an LLM judge, scores the agent.