I am excited to be an investor in trade(xyz) as they partner with ICE to bring 24/7 perpetual futures on Hyperliquid to the United States. As a market participant, I am looking forward to to using their innovative product to enhance my investment process.
We're releasing dense Argus-format annotations for >5,000 hours (290k episodes) of public robot data (ABC-130k, MolmoAct2 YAM, DROID, GM-100, ABC-Sim), labeled with GPT 6.1 Sol.
Per-hand subgoals and actions, plus outcomes, mistakes, recoveries and object-state changes 👇🧵
🤗 https://t.co/v6GbJlD36D
Hey, I agree tactile is somewhat separate, but I've still merged some changes to better accommodate diverse modalities eg tactile, depth, and more: https://t.co/L29iwkxDVD.
You can find some examples here:
1. https://t.co/yFVNEqKCiK
2. https://t.co/zNuF4TL5EM
3. https://t.co/IiVA8Pg3dy.
We recently published the eight-week process behind scaling our UMI dataset to 1M+ tasks and 45k+ new tasks a day.
Now, we’re open-sourcing DiverseUMI-100, a collection of 12,000+ tasks from a 100-hour sample of our dataset, complete with dense annotations by Argus, our advanced robotics annotation pipeline.
Another cool update from the robotics world! While we're all wow-ed in mental land, there's a ton of progress and i feel like acceleration happening in physical land too now.
My guess is in good part also (but not only) thanks to the coding models progress over the last year.
- $10/hr and dropping
- 90 international operators and growing
- No two tasks exactly alike
- Maximum customizability (any change to the environment/operator instructions/etc. is a single phone call to our wonderful team in Mexico)
- Ungodly amounts of custom camera firmware written for max operational efficiency
- A self built 20 petabyte data cluster to store all of this
At Pantheon, we like to bet on things that scale.
This has been and will continue to be an unbelievable push by the team. Infinite moving parts and countless people involved.
How do you build the most diverse UMI dataset in robotics?
In the last 8 weeks, we scaled an international UMI data collection operation from 5 to 90 operators, built out a dataset of over 1M+ unique tasks, and continue to capture over 45k+ new tasks each day.
Robotic World Models require much higher diversity of tasks than imitation learning. Here's the why and how behind our operations. 🧵
How do you build the most diverse UMI dataset in robotics?
In the last 8 weeks, we scaled an international UMI data collection operation from 5 to 90 operators, built out a dataset of over 1M+ unique tasks, and continue to capture over 45k+ new tasks each day.
Robotic World Models require much higher diversity of tasks than imitation learning. Here's the why and how behind our operations. 🧵
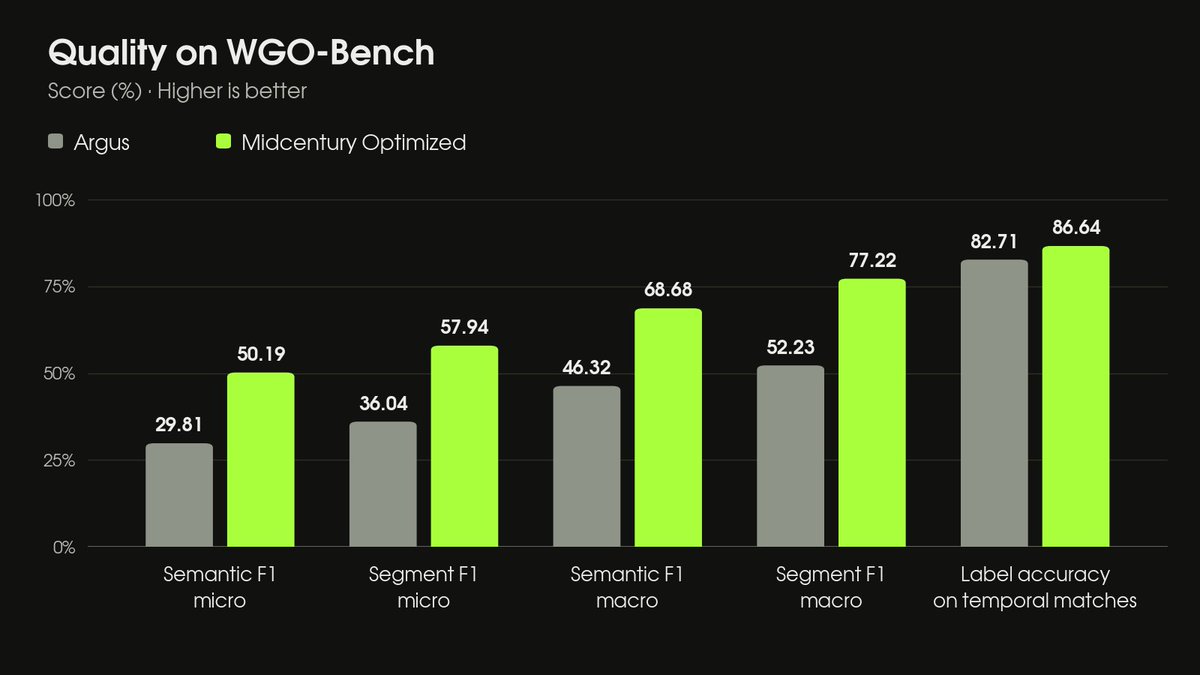
We spent the weekend experimenting with Argus and pushed it to SOTA on WGO-Bench.
Our optimized version scores 50.2% semantic F1, up from the 29.8% out-of-the-box score, and well ahead of other leading annotation services.
All of the gains came from how the model sees the video. We gave it denser frames, a second look at each action's boundaries, and a final check on every label.
Thanks to @PantheonInc@calixo888 for open-sourcing Argus.
The full repo is coming soon. For now, you can read our tech report here: https://t.co/Ue1gHmWoBT